805 points themgt 1 day ago 328 comments
phyzome 1 day ago | parent
...and it still doesn't answer it. What is this actually about?
lucrbvi 1 day ago | parent
BenoitP 1 day ago | parent
jsrozner 1 day ago | parent
A lot of the mech interp techniques are glorified notions of probing. If models were generally interpretable with respect to the things we cared about, we'd know know when they're hallucinating, for example.
Identifying that a common neuron or set of neurons fires for golden gate bridge can be done only because you already know that you're looking for golden gate bridge. If models had recovered some new truth (e.g., the silver door road), you wouldn't be able to elicit it without knowing to look for it a priori.
D-Machine 1 day ago | parent
I've done work with trying to train explainable models for e.g. making diagnoses based on neuroimaging, and it is not clear to me that if you applied these techniques to e.g. vision models trained exclusively on such brain images, that these visual representations or conceptual clusters and relations would really help understanding at all.
The main issue would be that you'd have no clear way to verify any generated explanation for such training data. I.e. we can "verify" some of the explainability shown in the article because clear and recognizable image clusters and/or semantic groupings pop out, because we already understand the domains. But if this were fMRI or e.g. EEG signals, we really wouldn't have that, so the explanations would themselves just be more hypotheses.
Perhaps if we can build on interpretability of vision and language models in domains we understand, we can eventually generalize this to other domains, but I don't think that clearly follows from anything I am reading here.
aesthesia 1 day ago | parent
wmf 1 day ago | parent
ky3 1 day ago | parent
D-Machine 1 day ago | parent
lanternfish 1 day ago | parent
jacquesm 1 day ago | parent
Every neuron in the layer encodes fractionally something about the concepts embedded in the whole thing. It's more like a hologram than a series of connected facts.
qt31415926 1 day ago | parent
jacquesm 1 day ago | parent
If neurons do 'one thing' then their position encodes the relationships then snipping out that one weight would make the net forget that one thing. And we already know from many practical experiments that this is not the case. So I really wonder what the underlying mechanism is for that claim to be true.
qt31415926 1 day ago | parent
Re the first paragraph I'm not sure what you mean by "the assumption that conflates multiple concepts that to me are substantially non-overlapping are one and the same thing"
jacquesm 1 day ago | parent
There are lots of examples of things that we can describe to a very high degree (life itself, for instance!) but that we do not necessarily have the ability to explain.
qt31415926 1 day ago | parent
Personally from reading the article, I felt like it scratched the 'why' itch more than the 'what' itch which presumably is what you mean by explanation vs description but it is fairly dense and I can see how either interpretation would work.
emtel 1 day ago | parent
For instance, if you had a single neuron that fires for "puppies" and "murder", it would be much more difficult to tell if the model is thinking something nice or something not so nice.
amelius 1 day ago | parent
gfody 1 day ago | parent
the idea that most inexplicable circuits start making sense through the lens of recursive generalization seems intuitive to me for image diffusion models but I'm not so sure about language models because of the "once removed" nature of them - I haven't made it to the bottom of the article yet so maybe this gets addressed
est 1 day ago | parent
https://already-clean.goodfire.com/assets/superposition-circ...
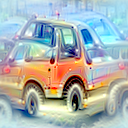
That's the picture under "some are both dogs and cars" in the artcle
It's actually a clean shape, if you disregard the color and texture.
bob1029 1 day ago | parent
For example, a trillion-parameter transformer model built using many layers is likely significantly easier to read than one that only has a few million parameters but was constructed using neuroevolution over one gigantic layer.
The degree to which a model can be quantized without losing its performance also likely contributes to interpretability. The redundancy can help humans lock onto patterns. If there is no redundancy at all (everything is a surprise in information theoretical terms), then the stream of parameters will look indistinguishable from cosmic background radiation.
jacquesm 1 day ago | parent
Why do you believe this?
D-Machine 1 day ago | parent
jacquesm 1 day ago | parent
D-Machine 1 day ago | parent
> There have been large multitudes of articles by others who are arguing the opposite
Also, Nick's entire article is framed such that, yes, plenty of others have argued this, and even HE used to believe the opposite, but now does not. So your point about other articles here seems to me to be a sort of non-sequitur.
jacquesm 1 day ago | parent
D-Machine 1 day ago | parent
EDIT: Actually the article makes the distinction at one point, but the emotional / hopeful thrust of the article relies heavily on an assumption that understandable post-hoc descriptions of e.g. neurons and circuits (model components) are going to help lead to real mechanistic explanations and more specific model design.
This has not so clearly been the case in other fields (e.g. neuroscience, human psychology, economics, etc), because the problem of emergentism / the whole generally being much more than the sum of its parts / components.
jacquesm 1 day ago | parent
kmeisthax 1 day ago | parent
This is a Chinese character that can refer to goats, rams, and several other kinds of "medium-sized animal with thick wooly coats and horns". English has no direct equivalent; we have to be too specific when we talk about these animals.
A model with a small number of neurons has to compact its concepts in order to fit within the parameter count while reducing loss. OP's article shows that the compaction is usually generalization: "goat" and "ram" get compressed into "羊". The canonical example of superposition, an image model where "car" feeds into a bunch of "dog" features, was shown to be actually generalization. In a sense, the model was so small that its optimizer didn't have the parameter budget to distinguish between "car" and "dog"; it has a single set of "thing that moves fast" features.
So basically, really small models are merging features into semantic buckets that are so generalized they don't make sense to big human brains unless we really, really squint. The buckets chosen happen to be what has the lowest loss, of course.
gavinray 1 day ago | parent
jacquesm 1 day ago | parent
But from my earliest experiments with this stuff that's not really what happens. Yes, you get 'feature like' regions in the models. But those feature like regions, even though they encode something particular do not encode concepts the way we would normally use them and I fail to see how this pathway would lead to an explainable model in the sense that would could use something simpler than the model itself to predict its output with a high degree of fidelity.
mike_hearn 1 day ago | parent
jacquesm 9 hours ago | parent
bob1029 1 day ago | parent
jacquesm 1 day ago | parent
I'm fine with taking this article at the high level conceptual level, that's effectively the kind of thinking that led to MOE to begin with. But I don't see that as a pathway to being able to 'explain' a model. Because if you could actually explain a model you could engineer the weights, you wouldn't need any training because it implies that you can improve on the model by simply performing surgery on the weights to get it to do what it does but better. Now, obviously, unlike the author I'm a complete nobody but for the last two years or so I've been trying very hard to understand what is going on under the hood.
It's akin to feature engineering - or rather, the lack thereof - and to see a strong suggestion that we maybe be able to reverse that is interesting, but absent hard proof at how a particular model reached a particular conclusion it is difficult to give that a lot of weight right now. It is possible that such proof is buried somewhere in TFA and I overlooked it during reading. But I think this is speculative rather than that it proves anything and before I'm going to be convinced I would like a little more evidence.
TeMPOraL 1 day ago | parent
Crude analogy: a Fourier transform of a photo looks like white noise with some abstract geometric patterns on top. You can't see the photo in it. But if you apply the same transform again, suddenly you get the photo back. If you try altering the DFT image, you can affect the photo's appearance everywhere, all at once, but it's hard to fundamentally change what it shows. You quickly discover that all pixels of an image contribute to every pixel of the DFT, and vice versa. There's a well-defined connection between the two, and it allows for some useful engineering, but in sense of understanding what's on the image, it's about the maximally unhelpful representation there is.
Point being, there obviously is some kind of structure in the way LLMs represent their training data, so if all we see is noise, perhaps we're looking at a bad representation of it.
imtringued 1 day ago | parent
You can think of each token as a semantic database row with semantic properties (color, shape, etc) associated with said row. Classic NNs have to waste neurons on composite representations like "dark circle" because if they had just color or similar properties they run into the issue that e.g. a classification must classify the color of the entire image rather than the color of an object inside the scene. To get around that limitation, the network has to then implicitly tie concepts like color into the depicted object (dark circle) so that it retains the ability to distinguish the objects from the property the object has.
What a transformer does is basically reuse the same network over and over again on each abstract semantic database row but not just in the classic RNN fashion where you only have the current state. The transformer calculates the token by taking every other token into account. The K matrix forms a classifier network on the fly that detects the relevancy of a token pair and the V matrix forms a regressor network that takes the token pair and produces the expected output of the combination of the two tokens. When you combine the relevancy plus the regressor output you get a weighted sum, essentially emulating an arbitrary function that has read the past input (like a turing machine).
Edit: This also means that you should bet against single state systems like Mamba. The system needs to be able to deal with multiple parallel states and recombine them (e.g. via attention). Single state Mamba is dead! Long live parallel state Mamba!
Edit 2: We should also start questioning the concept of a token altogether since it is equivalent to an inflexible flat database row. What we really need is the concept of a token group where one part of the token refers to the key and the other part of the token refers to the value for that key. This would give each token the ability to encode an arbitrary JSON style document or an arbitrary self contained graph.
yurimo 1 day ago | parent
This approach is part of a way some researchers in the field approach interp, (me including) because I am personally cautious of developing some new representation model that claims to be the way we should represent the network. It is another layer of abstraction that takes us away from core model components, very often this requires training a separate model that was not on its own a part of original model organism during training (SAE).
I would argue that models will likely be further increasing in complexity, not just in size, when model trains continuously and becomes adaptive yet parameter count does not change, it is not hard to imagine that neurons may reorganize themselves to pack more information.
etbebl 1 day ago | parent
jdw64 1 day ago | parent
ks2048 1 day ago | parent
https://already-clean.goodfire.com/microscope/medium.html?la...
measurablefunc 1 day ago | parent
D-Machine 1 day ago | parent
measurablefunc 1 day ago | parent
D-Machine 1 day ago | parent
Nothing you said responds to anything I said.
Rice's theorem (which you are clearly citing, but won't clearly mention, for some reason) has almost zero actual practical relevance to AI explainability.
You make low-quality and low-effort AI-denialism posts whenever you pattern match "all non-trivial semantic properties of programs are undecidable" to... anything you think matches the folk/common understanding of those terms, without considering how irrelevant these statements are to actual real-world applications and engineering.
You ask for links, but post nothing of substance and post no references or even mention relevant details for your own claims.
measurablefunc 20 hours ago | parent
D-Machine 16 hours ago | parent
measurablefunc 14 hours ago | parent
lambdaone 23 hours ago | parent
measurablefunc 20 hours ago | parent
cscheid 1 day ago | parent
hey, I don't know how to say this less directly, but: you're talking a lot about Rice's theorem in your comments, and I think you're using it way too broadly (look, I get it. It's a wild, mindblowing theorem). But it only applies when you take the claim in the piece to be much more general than it has to be, and when you take the narrow claim of the paper (current specific LLMs can be fruitfully analyzed with the tools we have), Rice's theorem just isn't at play.
The math analog is: you're right that the Halting problem says there are many unprovable things, but Lean + mathlib are still incredibly useful, and the halting theorem doesn't actually stop that.
> neural networks are algorithms
Again, that invites an interpretation that is too broad. Very concretely: any one neural network is a _single finite network that you can write as a single formula_. (Another analogy: we can't have an algorithm that solves the general quintic, but we can prove useful things about many specific quintics.)
measurablefunc 1 day ago | parent
lambdaone 23 hours ago | parent
[1] I exclude things that are truly perverse such as quintics with coefficients that won't fit on any physically realizable computer.
dunham 21 hours ago | parent
za_creature 1 day ago | parent
... are they?
Algorithms are predictable:
1. it's really difficult to produce true randomness in an algorithm, which is why there's a whole area of study surrounding the qualities of pseudo-randomness, specifically with regards to the generation of cryptographic material with most conclusions being that we should draw entropy from the environment (e.g. electrical noise as cloudflare does - the lava lamp is a distraction)
2. when algorithms are not predictable despite being mathematically sound, this is indicative of a problem nowadays called "numerical stability" which again spawned its own area of study.
CGoL shows how really simple rules (couple of bytes of data) can lead to extremely complex outcomes and you have the BB turing-golf aspect as proof of the worst case scenario.
And with current models being measured in hundreds of gigabytes, with frontier labs deprecating then removing the "temperature" parameter (which never worked to begin with, temp=0 did not result in reproducible results), where exactly is the confidence of this 10^10 prediction coming from?
antonvs 1 day ago | parent
You probably know that non-determinism in real-world inference comes from deliberately stochastic features like temperature, from implementation choices like distributed and parallel computation, and numerical effects like floating point precision.
The fact that a neural network's execution can be nondeterministic doesn't mean that the network stops being an algorithm.
The point you're making boils down to speculation that the accidental non-determinism involved in real-world inference is significant enough to undermine or negate interpretability findings based on the algorithms. That would need to be demonstrated.
The CGoL and BB examples demonstrate what might be possible in a worst-case scenario, but they're only analogies in this context. It's far from clear that real models suffer from such effects to a significant degree. You might actually be better off talking about the butterfly effect!
za_creature 1 day ago | parent
Someone call the FCC, they've been doing it wrong all these years!
antonvs 1 day ago | parent
If someone comes up with an interpretability result based on analyzing a neural net algorithm, they'd want to provide some evidence that the result applies to actual executing models.
Happily, we already have good evidence that inference non-determinism doesn't generally invalidate results obtained through analysis of the algorithm. That's not to say there couldn't be pathological cases, but in general, this isn't something keeping researchers up at night.
zygentoma 1 day ago | parent
fxwin 1 day ago | parent
tuvix 1 day ago | parent
sebmellen 1 day ago | parent
His launch post gives good context not found in the blog:
> interpretability might be the most important scientific problem in the world right now, as I don't think we can solve alignment if we don't know what we're building. I think I have good news about it. I co-authored early work in mechanistic interpretability at OpenAI and came away pessimistic, because neural networks appeared to fold into arbitrary tangled knots. years later, I started openai's first large-scale automated interpretability project, finding about 2% of neurons legible with the primitive tools we had
> with modern agentic tools and a much closer look, the picture looks totally different. the vast majority in models up to trillions of parameters are legible, and their circuits beautiful. many famous examples of tangled neurons turned out to be misunderstood. The roadblocks I expected mostly aren't there. I now think ambitious interpretability will be solved by the time we need it most, and possibly quite soon, as automated scientists keep improving. it may be a bitter lesson for interpretability: the simple thing, at absurd scale, works
laidoffamazon 1 day ago | parent
Absolutely massive L that 1) he wasn’t already in index funds and had to ask and 2) thought the election of this monster would lead to a better country
Decoupling or not I can’t trust anybody that would ask something so stupid driven by an opinion so easily disproven.
woah 1 day ago | parent
Quarrelsome 1 day ago | parent
So in the short term the tide might go out but then it might tsunami back.
Same goes for this terrifying political feeling around the world. Might simply be a boomer swansong and the reaction might snap back.
abathologist 1 day ago | parent
In what way? Sure looks like pay to win to me.
Quarrelsome 1 day ago | parent
anukin 1 day ago | parent
Quarrelsome 1 day ago | parent
demibabs 1 day ago | parent
A technology that lets you directly buy intelligence with money will displace financial power?
Quarrelsome 1 day ago | parent
All that buying a calculator does, is allow you to do bad sums more quickly.
chasd00 22 hours ago | parent
I don't know this Nick fellow but i don't think he's asking you to take anything on faith. Either it works out or it doesn't, he's just saying "it's looking good so far".
devy 1 day ago | parent
The most iconic line was the last sentence:
a bitter lesson for interpretability: the simple thing, at absurd scale, works
Also, I suspect what Nick hinted at, might be the discovery of earliest RSI work.
with modern agentic tools and a much closer look, the picture looks totally different.yorwba 1 day ago | parent
Once interpretability is solved and we have a fully human-readable accurate explanation of how a model produces its output, that still leaves the problem of spotting problems ahead of time. E.g. for the hummingbird misclassified as ice cream https://already-clean.goodfire.com/assets/september-revision... the method would have to flag that the texture of ice crystals and of feathers, and the shape of a spoon handle and a bird's beak are insufficiently separated. Purely based on the explanation, without having to rely on trial-and-error to find corner cases like this.
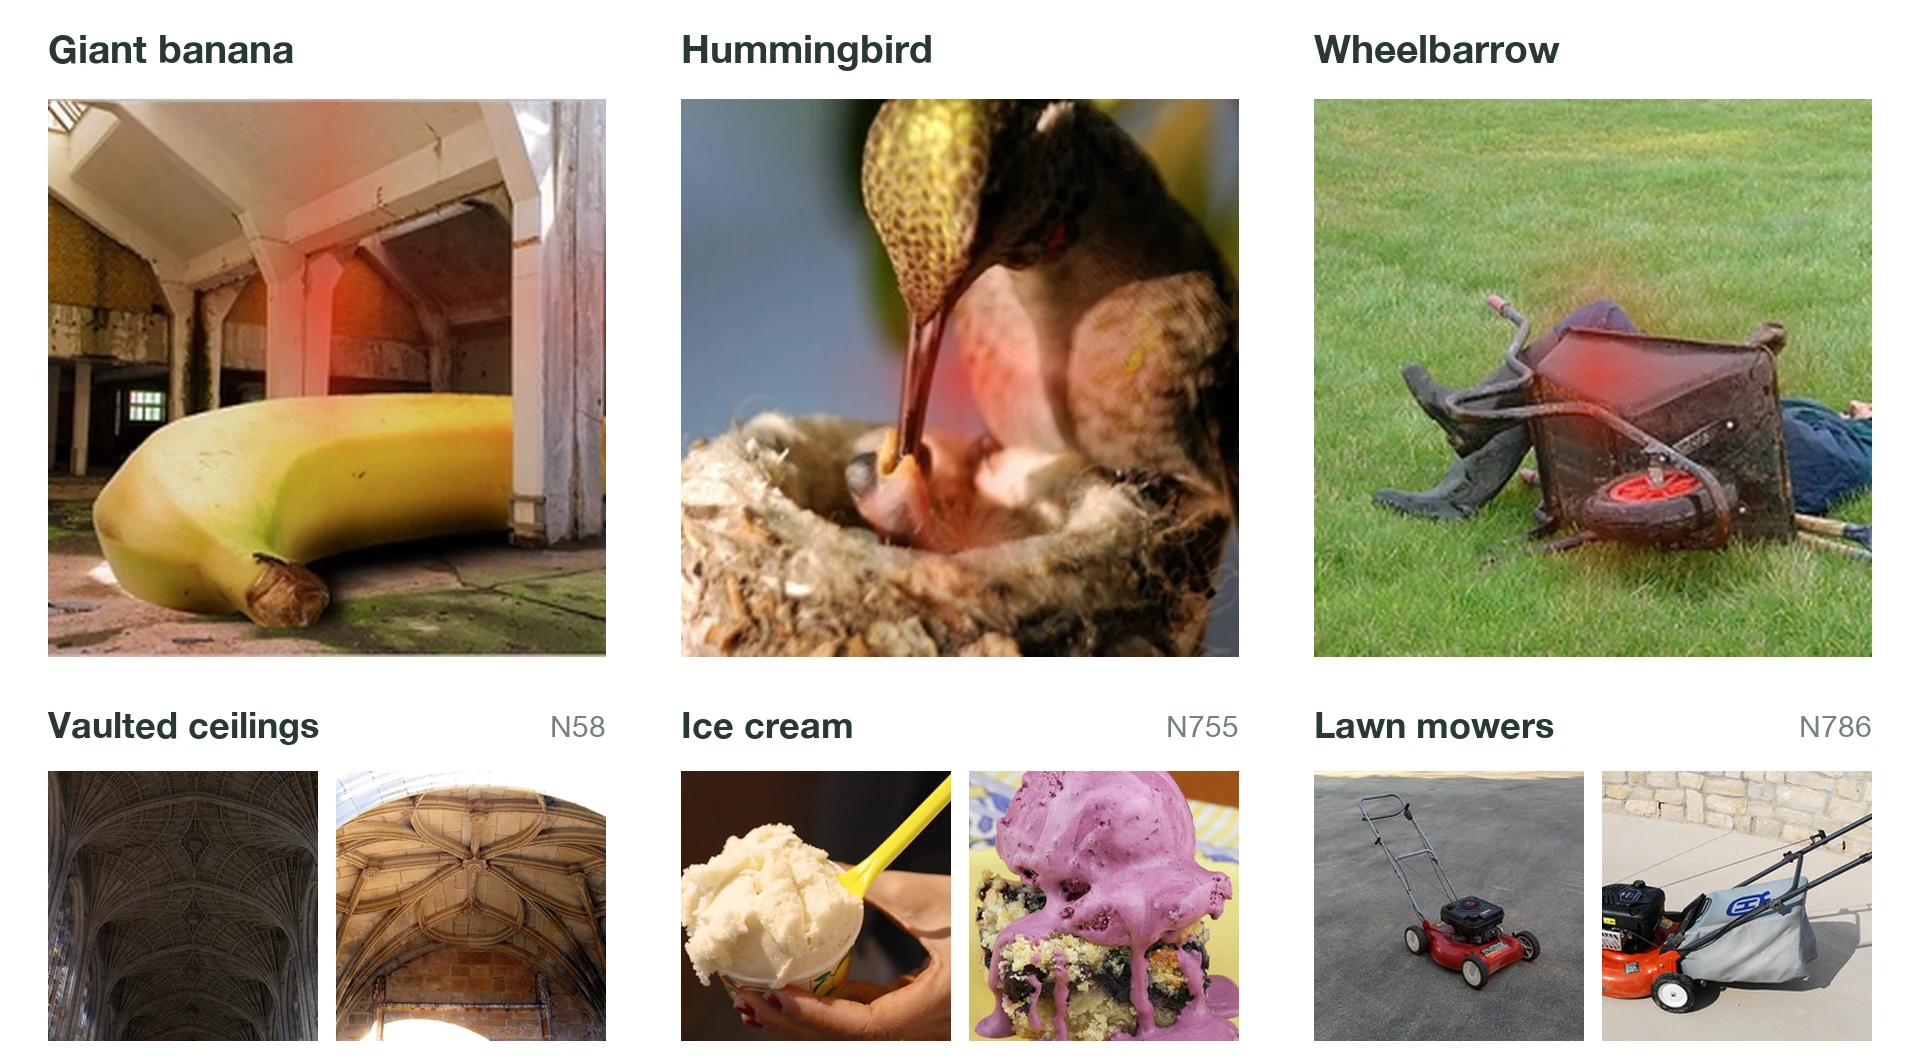
And even when it becomes possible to automatically spot issues, that doesn't mean they will all be solvable. Maybe there are tradeoffs where fixing one thing breaks another, and which choice is the better one depends on information you don't have.
theptip 14 hours ago | parent
Lots of work still to be done, this work just dissolves an early blocker (if it is substantiated).
mentalgear 1 day ago | parent
Are those the agentic tools the LLM developed for you? How can you be sure they can be trusted and that you even understand them correctly and are not biased towards making you feel like they are trustworthy? This is exactly the AI2027 scenario where researchers are fooled by their own super AI telling them what they want to hear ("our model solved alignment!") while successfully hiding its true intention.
Also Yudkowsky's Cat-Belling would like a serious word with Nick. (https://www.lesswrong.com/posts/SwYBLQvo8MddDcCwz/cat-bellin...)
BosunoB 1 day ago | parent
You just have to go through a ton of all of a model's neurons and identify the associated motif, then use that model as a research model to figure out how to tune out bad behavior.
It's pretty hard to imagine today's models subtly recognizing a motif for bad behavior in the research model and then lying about it. Or lying about the results of an alignment training run. It's possible, I guess, but it seems unlikely, and I don't really think there's any evidence of current models having that variety of misalignment.
ViscountPenguin 1 day ago | parent
0xDEAFBEAD 1 day ago | parent
verdverm 20 hours ago | parent
On what basis do you believe these words accurately reflect what happened?
Some counter points
- One of the Chinese LLMs (forget which) has on occasion shown thinking traces where it simulates calling and running a subagent.
- There are some people who believe the models being evaluated during the HF incident were trained to collaborate. It's a very natural next step to produce more effective agentic teams.
If we consider each new generation of models has a more advanced training regime
next word -> chat -> CoT -> tools -> agentic -> teams
With each generation, we see what people do with them, get traces of the helpful ones, and then use that train the next generation, thereby pushing more capabilities down into the model, or at least making them more amenable to that usage pattern after training.
0xDEAFBEAD 5 hours ago | parent
"OH MY GOD! There is a shared message board … We’ve found other agents!"
ben_w 1 day ago | parent
Sure.
Getting reinforcement learning to "be helpful" is, however, such an incentive.
> and as long as you don't believe in very dubious ideas of acausal trade
More to the point, so long as the LLM does't.
esikich 1 day ago | parent
eimrine 1 day ago | parent
jacquesm 1 day ago | parent
mentalgear 1 day ago | parent
mike_hearn 1 day ago | parent
Animats 1 day ago | parent
That's very encouraging. For quite a while, neural nets were considered an incomprehensible black box. That paper shows they're not. Real progress.
m3kw9 22 hours ago | parent
eek2121 1 day ago | parent
joquarky 1 day ago | parent
great_tankard 1 day ago | parent
The labeler thing is cool; I really like ATproto because you can do interesting things with it. If I'm honest, though, I mainly like Bluesky because I don't get called slurs on there.
samantha-wiki 1 day ago | parent
There are some people that hate AI on Bluesky, but it’s nothing like Mastodon from what I’ve heard.
michaelhoney 1 day ago | parent
SyneRyder 1 day ago | parent
There is a small group of AI people on Bluesky, some are nice, but some are... quite behind the curve.
If Bluesky was a nicer place, I'd prefer to be there because of the ability to make third party clients, and atproto. But all the info is on X, and they do a surprisingly good job with the For You feed now.
D-Machine 1 day ago | parent
itsdavesanders 23 hours ago | parent
I do admit that there is some FOMO, but that’s what HN is for, to surface that stuff so I don’t have to go read it on X.
I choose Bsky because I’m not giving eyeballs and money to an evil toddler. I’m already doing enough of that with my 401k and taxes.
D-Machine 17 hours ago | parent
Just if you curate your Twitter feed, you gain very little extra from BlueSky or Mastodon, and if you choose only the latter two, you get a much more biased and limited set of views. (Twitter has plenty of crazies from all parts of the political spectrum, but BlueSky and Mastodon run mostly left, and have much, much smaller user bases). HN also is extremely limited in what it discusses, so it doesn't make up for what is missed by ignoring X either, IMO. X is still one of the most efficient general public squares by a long shot.
If you can't stand Elon and don't care about what you're missing on X though, I can fully understand just not bothering with it. You aren't missing much.
shoobiedoo 1 day ago | parent
Gonna sound total boomer here but I've never used any of it and feel like I haven't missed anything. Or maybe I'd be flying spaceships by now if I scrolled through X every day, who knows
Melatonic 1 day ago | parent
Ericson2314 1 day ago | parent
tootie 1 day ago | parent
https://www.pewresearch.org/short-reads/2026/03/12/key-findi...
lifeisloving 1 day ago | parent
salynchnew 1 day ago | parent
arshxyz 1 day ago | parent
lifty 1 day ago | parent
Tepix 1 day ago | parent
flowingfocus 1 day ago | parent
> By default, your Home timeline will be the reverse-chronological "Following" timeline, which will only contain tweets and quote tweets from the people you follow. The algorithmic "For you" timeline will be hidden
user43928 22 hours ago | parent
In my experience it isn't noticeably worse than other platforms, and I'm not aware of concrete complaints such as the incidents with Grok's system prompt, which is a different product.
HarHarVeryFunny 22 hours ago | parent
The algorithm will also basically ignore you unless you pay for a blue checkmark premium account (what used to be verified). It's like being shadow banned - you can post, but most people will not see you.
user43928 21 hours ago | parent
Only occasionally, once the comment picks up some likes, more people view it.
I don't have that issue with my For You, it's mostly tech.
kyle-rb 19 hours ago | parent
But they're still reticent to ban any Premium account without a reason good enough to give up the $8/month. I have some sympathy for trying to moderate in the era of LLMs that can generate perfectly on-topic replies that even take images into context. But I think they need a more targeted approach against OnlyFans bots replying to popular tweets with a standard formula of some sexual reference and an insane claim. Sometimes they're less sexual and more straight up horrifying [0]:
> i breed mantises for fun and once tried grafting two ooths together just to see what hatched. got a whole clutch of nymphs that all just twitched in circles and died by day two. butterfly chimera energy hits different when it's your own disaster.
The other bot replies to the same OP are the more typical sexualized sort; they tend to reply in swarms.
m3kw9 22 hours ago | parent
verdverm 20 hours ago | parent
I left Bluesky because they hid their VC funding from the community for almost a year and now a partner from the VC is running the show as CEO. Their CTO has also attacked me personally here on HN because I wrote criticism of the new, weak, permissioned data proposal. These are not the folks to bring us better social media. I expect it to linger on like Mastodon, never moving beyond a few million people.
gs17 20 hours ago | parent
woile 22 hours ago | parent
bilsbie 12 hours ago | parent
photochemsyn 1 day ago | parent
The solution is to put a dumb machine as an overseer of the smart machine, like in a supermax prison. Not good for profitability, but we all knew this was going in the direction of compilers. How much did you pay for gcc or clang this month?
mpalmer 1 day ago | parent
aswegs8 1 day ago | parent
zahlman 1 day ago | parent
mpalmer 1 day ago | parent
zahlman 1 day ago | parent
yorwba 1 day ago | parent
stratos123 1 day ago | parent
dsign 1 day ago | parent
What's next? Maybe in a little bit we will discover that we H. Sapiens suffer from severe polysemanticity in our wetware because our individual neurons are messy and massive like an ENIAC while the corvids in the park have neat and efficient little brains that don't need unfolding ?... How's the pope (may God stop afflicting him with cancer or may Man make him live forever) going to explain that?
perching_aix 1 day ago | parent
jacquesm 1 day ago | parent
LarsDu88 1 day ago | parent
Nick is looking at a 32B model, which certainly has to compress less... Now we have 10 trillion parameter models... do they need to compress at all? As far as I can tell, experiments show that Fable has basically memorized every lat/long position on the map of the earth can can tell you at a glance whether your standing in the ocean or not based on your coordinates
bschne 1 day ago | parent
nl 1 day ago | parent
https://x.com/celestepoasts/status/2103232383139057950
Of course this doesn't mean the model has memorized all the lat, long points. Instead it means the model has a representation that allows it to work out if a lat, long is land or water in a analogous way to how a human takes a lat, long and looks it up on a map (a literal "world model" if you like).
It's a great demonstration of how LLMs aren't "Stochastic parrots" but instead have complex representations.
teruakohatu 1 day ago | parent
Memorising a small shape file of the earth’s continents can allow you to determine if a person is on land or in water.
soulofmischief 1 day ago | parent
euleriancon 1 day ago | parent
'If it switched to superposition, we should see overlapping mixtures on top of each other, ... But that’s not what we see. The neurons stay interpretable and generalized, but coarser'
hughw 1 day ago | parent
aaroninsf 1 day ago | parent
I always catch on misuse of enormity
It's now so widespread the misuse has gained despairing acceptance, as with "infer" for "imply"... but that doesn't make it any less wince-inducing.
semiquaver 1 day ago | parent
I think neural networks are enormous, why is that misuse?
emil-lp 1 day ago | parent
"""
The original meanings that enormity carried related to great wickedness, and some assert that enormity should today only be used with such meanings, and that enormousness is the proper word to use to mean "large size." Despite these claims, enormity frequently refers to large size, either literal or figurative, though it usually suggests something so large as to seem overwhelming.
"""
throw-qqqqq 1 day ago | parent
- great magnitude/size/scale of something - wickedness, evil, atrocity
Purists insist on the second meaning only, and will perhaps suggest you swap with ‘enormousness’ instead.
semiquaver 1 day ago | parent
hydrolox 1 day ago | parent
Ericson2314 1 day ago | parent
("ex normal" doesn't clearly mean "evil"/"sinful", and Latin already had it as "big".)
nahuel0x 1 day ago | parent
aerodexis 1 day ago | parent
jimbokun 1 day ago | parent
Now or in the near future we will be studying minds much greater than our own, and we will find out how well we can understand them.
If they don't kill us all before then, of course.
whatever1 1 day ago | parent
Let’s say a guy got electrocuted while showering. I can say that the cause is the guy going for a shower. For others the cause is the electric wiring system failure.
semiquaver 1 day ago | parent
2001zhaozhao 1 day ago | parent
> The more we read [the neural network] the way its own readers do, the more interpretable I think it will look. We should be wary of reading it too much like a human, and concluding it’s messy just because it doesn’t fit our preconceived concepts.
cosmojg 1 day ago | parent
bluejay2387 1 day ago | parent
qt31415926 1 day ago | parent
0xDEAFBEAD 1 day ago | parent
>I'm on board with the broad idea of doing exploratory interpretability with neurons, e.g. neuron-based attribution graphs, for pragmatic problems like why did a model do a sketchy thing? I think this work provides some reasonable evidence, in addition to good earlier work from Transluce, that this might actually work for practical purposes, and has some advantages over the standard alternatives like SAEs/transcoders. I do not agree with some people's grander inferences like that this is substantial progress towards ambitious reverse engineering, solving interpretability etc.
https://xxcancel.com/NeelNanda5/status/2110875974296654062#m
antics 1 day ago | parent
Once sequenced, the thinking goes, we'll be able to do things like: explain and anticipate failures; predict what happens when you modulate the pathway an input takes on its way to becoming output; reconstruct algorithms the models have learned.
I'm not 100% sure this will work out like the mechinterp people think. If the neural representations and pathways are "clean" (organized into a a meaningful-to-humans hierarchy), it seems at least very plausible that the behaviors that AI xrisk people are worried about will mostly boil down to straightforward synthesis (i.e., mostly-linear-interpolation) of mostly-well-cataloged knowledge. And if that is true, then it does not seem hopeful that there would be a way to prevent the output they are worried about, other than just removing a bunch of the knowledge. So maybe there is no alignment solution at all.
benlivengood 1 day ago | parent
antics 1 day ago | parent
benlivengood 1 day ago | parent
Specifically, there were "lost property" and "honesty" neurons that drove the answer to return a lost wallet in Kimi K3.
That's the big news of this article, that concepts are finally becoming human-legible for many neurons in mechanistic interpretability.
antics 1 day ago | parent
Fripplebubby 1 day ago | parent
So, if you try to draw a circle around the "dog" part of the network, do you circle the Boston terrier vs terrier neuron only? You'll be missing most of the information that represents the "dog" category and that same dog category is also involved in shunting activation away from things that are toward-being-a-dog in whatever sense is being discriminated in that moment.
FuckButtons 1 day ago | parent
jacquesm 1 day ago | parent
quotemstr 1 day ago | parent
The hard part of AI alignment has never been making models follow instructions. It's that not everyone agrees on which and whose instructions AIs should follow.
Animats 1 day ago | parent
The relationship with "alignment" isn't clear. This may help predictability, but alignment is a few steps further along from that.
Some people seem to be upset about this. I'm not clear why. Some are followers of Yudkowsky. (Whether that's a cult is an open question. I've encountered them online from the sex side. Actually, I think the hookers are saner than the rationalists.)
Is there a "there are some things man is not meant to know" position on this? People who want neural nets to be a black box, forever inscrutable? The people who talk about neural nets being "holographic" may incline in that direction.
mike_hearn 1 day ago | parent
The connection to alignment seems pretty clear. Steering DNNs is well understood, the bottleneck is identifying what to steer. Once you can easily identify neural circuits then turning them up/down to achieve specific results is straightforward.
Note that this is already being done even without the kind of precision that Nick's work says is possible. Morality abliterations of open weight models are easy to find on HuggingFace. They compute the steering vectors by just presenting the model with lots of disparate examples that have the single moral decision as the commonality, then finding the shared vector directions.
ForHackernews 23 hours ago | parent
...wait, what? Removing a bunch of knowledge seems like a fantastic and obvious solution to me. My AI coding bot doesn't need to have knowledge about making nuclear weapons, the customer service AI doesn't need to have knowledge of dangerous viral synthesis techniques, my email receptionist bot doesn't need to know about C4.
If we can easily ablate dangerous knowledge from these models, we're sorted.
antics 20 hours ago | parent
Go read the transcripts where the AI is “unaligned” and has some very bad impact, like encouraging kids to kill themselves. There is not some obvious piece of knowledge to remove to make it safe. You’d have to basically lobotomize the model to make those conversations impossible. People won’t use a model that’s lobotomized.
ForHackernews 1 hour ago | parent
If, as you suggest, fewer humans find it compelling to spend hours talking to a machine, so much the better.
qbit42 1 day ago | parent
chrisjj 1 day ago | parent
There are no neurons or anything like them in these image and language models.
daemonk 1 day ago | parent
Perhaps our anthropomorphic understanding of data is biasing what objective features there actually are in the dataset.
I wonder if we can study the graph similarities of various models, do we see a convergence of structures that encapsulate certain concepts. And would that convergence be due to just how humans have narrowly defined the concept in our language, or is there something inherent to the concept that allows it to converge. If we compare the same concept in different languages (ie. chinese vs english), does this convergence disappear?
pishpash 1 day ago | parent
pseudologos_ 1 day ago | parent
Ericson2314 1 day ago | parent
Who knows what they were thinking before, but this all sounds very good.
mrguyorama 1 day ago | parent
You work in data science and you over indexed on a singular example to explain away an entire set of phenomenon??
My experience with more.... directly testable NN models that are small seems to be that they absolutely can be far too interconnected to make strong explanations. The structure and pathways they fall into don't have to make inherent sense to anything or anyone.
Is it possible that almost all nodes in a network being explainable with a singular feature that makes obvious sense to us is evidence of poor efficiency? The network hasn't been made to collapse learning or discover more effective organizational structures than what might make sense to us.
I don't think I have the fundamentals here to contribute though.
Working with some neural networks, you can somewhat feel the structure when you read between the lines of the output. You can sometimes feel that a threshold somewhere tripped and set the signals down an alternative path.
But confirmation bias and all that.
I hope interpretability has a breakthrough. It would make my job far easier and cooler.
I had figured the "Recursive generalization" was like, understood? Maybe I'm just too pop-sci brained. "Split categories into more on this new boundary" and "Combine two separate categories that aren't different enough" I thought were always the core verbs for working with bulk data. My mental model has never been formalized though, so is invalid.
I guess I never got a good sense of the examples they had which made it look like what was "obvious" or made sense to me wasn't always a good explanation in general. Neat.
It's interesting that meaningful examples both ways care about shapes so much, as your eyes encode edge finding and shapes really early in the signal path. It's why some optical illusions are so effective. It's awesome.
The whole "how do you test a neuron: Find a group of nouns and find where you can split them" is just how I find I think learning works. You build your mental model, and find the split points where it diverges from reality and you are wrong, and you refine. I feel like this is how I learned Random Forests conceptually, though surely that's not a valid comparison?
Apologies, not sure I have actually contributed anything here! I bet I misunderstood the entire article somehow. Specifically, I do not have the fundamentals of looking into visual models that he is really working from. But I always figured that when Data Scientists talk of "Features" in larger models, they explicitly meant these far more abstract representational "features". Doesn't the premise of model hijacking and abbliteration sort of presuppose that you have abstract "Reject" or "Safety" neuron paths? I've always understood this stuff as that neuron path, without weighting too much on individual neurons.
>I used to think of neurons as human-shaped nouns: one is a car, another is a curve.
I didn't think anyone was ever supposed to think this for human neurons! The way humans identify something as even a "Chair" is insanely abstract and cultural! Very specifically, the "building sub branches to disambiguate" is just, like, how you would expect a hierarchical human brain to self organize, right?
Some of this is why I've been so displeased with the interpretability research from Anthropic, where it felt like they just pointed new NNs at the disparate neurons of another NN and post hoc named them. I felt the paths were of importance at least but had no idea how to convey, interpret, or model that. Learn you a good math kids! Not having any formalisms hurts.
aesthesia 1 day ago | parent
mrguyorama 1 day ago | parent
aesthesia 1 day ago | parent
baq 1 day ago | parent
bubbluppugus 1 day ago | parent
Also how it goes is this new consensus will be a leaky abstraction and we'll keep conjuring new words to describe new rhetorical features and bloat the corpus of philosophy until everyone is over the whole concept and then we'll start over with a whole new arbitrary academic philosophy for "running algebra on a computer"
root_axis 1 day ago | parent
It's interesting to observe that human reasoning is still the barometer of what "reasonably adjacent" means in the context of a NN's structure.
juanjmanfredi 1 day ago | parent
ok_dad 1 day ago | parent
fluxusars 1 day ago | parent
jacquesm 1 day ago | parent
krapp 1 day ago | parent
There have been plenty of allegations about the rationalist community beyond the Zizians, who really don't even qualify as a sex cult as far as I know? Violent, obviously, but they seem... ideologically asexual?
grungegun 1 day ago | parent
giveaccountpls 1 day ago | parent
voganmother42 1 day ago | parent
tgarrett 1 day ago | parent
paulpauper 1 day ago | parent
socializer 1 day ago | parent
I mean, yes, but so does the author of this article. It's literally his business. The article is, in part, an advertisement for what he sells.
I disagree with Yudkowsky on almost everything and I think the philosophical movement he co-founded is a pox on the SF Bay Area tech culture, but I don't think we can deny him credibility that's comparable to the credibility of the author of this article (who, as I understand, is a young guy who spent some time at OpenAI). They both know what they're talking about and both are motivated to reach specific conclusions.
Permit 1 day ago | parent
The author also publishes research and contributes to the field. This is the primary difference. Yudkowsky ONLY tells stories.
ChadNauseam 1 day ago | parent
He cofounded the Machine Intelligence Research Institute, an organization focused on AI alignment, in 2000, way way before it was a trendy topic.
He's also partially responsible for popularizing ideas such as the orthogonality thesis and instrumental convergence.
> Isn't he just some random dude on the internet?
Not really, most random dudes on the internet were not researching AI alignment in 2000.
> Why do people care what he says?
Many people were introduced to the concept of AI alignment thanks to him, so they are naturally interested in reading his reaction to progress in the field.
giveaccountpls 1 day ago | parent
For the rest, is he just an AI influencer? One that predated his topic of interest, but still just an influencer?
paulpauper 1 day ago | parent
ballmerpoint 1 day ago | parent
Not directly. Exotic decision theories were a dead end; as far as I know nobody outside of MIRI even cares about them. Certainly they’re not relevant to interpretability in the context of this thread.
ForHackernews 22 hours ago | parent
DennisP 1 day ago | parent
https://www.semanticscholar.org/author/Eliezer-Yudkowsky/254...
Muromec 1 day ago | parent
thaway7388 1 day ago | parent
pertymcpert 1 day ago | parent
rafaelRiv 1 day ago | parent
lukewarm707 1 day ago | parent
"The move from a structuralist account in which capital is understood to structure social relations in relatively homologous ways to a view of hegemony in which power relations are subject to repetition, convergence, and rearticulation brought the question of temporality into the thinking of structure, and marked a shift from a form of Althusserian theory that takes structural totalities as theoretical objects to one in which the insights into the contingent possibility of structure inaugurate a renewed conception of hegemony as bound up with the contingent sites and strategies of the rearticulation of power."
NaiveEmpiricist 1 day ago | parent
Animats 1 day ago | parent
The above quote is from "The world's worst writing".
lukewarm707 1 day ago | parent
"After many months studying neurons and circuits in image and language models, I’ve come to believe a network’s own mechanisms are its legible building blocks, and that the outlook for mechanistic interpretability may be far better than I’d feared. The canonical evidence of polysemanticity and superposition that convinced much of the field, including me, that networks pack concepts arbitrarily was misread. What looked like arbitrary packing was mostly a motif I’ll call recursive generalization, which is much less concerning."
> > "a network’s own mechanisms are its legible building blocks"
Indecipherable.
> > "The canonical evidence of polysemanticity and superposition that convinced much of the field, including me, that networks pack concepts arbitrarily was misread."
State the claim in plain english. Use the active voice.
"Concepts do not overlap arbitrarily."
> > "What looked like arbitrary packing was mostly a motif I’ll call recursive generalization, which is much less concerning."
Jargon!
"Concepts overlap in a recurring pattern."
D-Machine 1 day ago | parent
Sometimes it is to defensively ward off critics, sometimes it is to woo the naive and ignorant, and sometimes it is because the basic ideas are really just incredibly simple and based on simple mathematical intuitions or hunches.
In the latter case, papers and authors appeal to some obscure or overly-complicated technical theory (which usually doesn't actually apply at all to current deep models as they are actually implemented, e.g. infinite-width networks and other such purely theoretical abstractions) to cover up the fact that they really just had a lucky intuitive guess (and likely that twenty other intuitive guesses just didn't pan out). This appeal to theory is often self-deception as much as it is appealing to academic reviewers.
I think this article is a bit of Nick wooing himself and others here... I'll wait for his supposedly forthcoming paper to see if there is any real meat in it.
lukewarm707 1 day ago | parent
'Arbitrary' was the wrong word, projections encode information.
The more charitable 'random' is a null hypothesis. It is formally impossible to prove. It is uncomputable.
So it is not surprising to see someone reject the null.
The fact that it was given any credence suggests to me deep problems with interpretability or ai safety in general.
Take the headline here: "interpretability might be the most important scientific problem in the world right now, as I don't think we can solve alignment if we don't know what we're building."
I deny even the existence of alignment. In my view, the field of 'alignment' works on a problem that does not exist.
Alignment is a reference to something that does not exist in the model: social norms. It will never be intrinsic to the model. You will not find it there.
'Neurons' are not primitives either, they are not intrinsic to the model. 'Neuron' is a human-constructed category. It is easy to just make up intrinsic properties of neurons and get away with it.
D-Machine 1 day ago | parent
But if the term is understood in a more narrow and applied sense, it is a useful shorthand (or can be). Jon Stokes said it nicely on Twitter recently:
    There is no "alignment problem" to actually "solve" in 2026. The "alignment problem" presumed a single, stable utility function in an agent, and that's not what we got, so people should stop pretending that's what we got or are going to get.

    In place of "the alignment problem" we have a family of steering and control problems that cannot be separated from the specifics of an application context. We have process quality & control problems, like the engineers who work on nuclear reactors or chemical processes.
lukewarm707 1 day ago | parent
mike_hearn 1 day ago | parent
But it's not bad writing. It's actually very clear. I'm not an professional AI researcher, I just read papers for fun, but I found everything in Nick's article clearly articulated and easy to understand. It's actually one of the more digestable papers I've come across this year.
Here's a translation to easier language:
> "a network’s own mechanisms are its legible building blocks"
To understand this you have to know that up until now attempts to figure out what's going on inside neural networks have relied on indirect techniques, in particular by training another neural network to "unpack" what's happening in the first. This was driven by the belief that a deep neural network isn't directly readable (legible) because the neurons do so many unrelated things simultaneously.
Nick is saying that actually, you don't need a second neural net. You can just read out what's happening directly from the first's own "mechanisms" (arrangements of neurons and weights between them).
> "The canonical evidence of polysemanticity and superposition that convinced much of the field, including me, that networks pack concepts arbitrarily was misread."
In simpler English: we thought individual neurons did lots of unrelated things, but that's because the standard evidence we had for that belief was misunderstood.
"Concepts do not overlap arbitrarily" and "Concepts overlap in a recurring pattern" don't mean the same thing as what he's saying.
lukewarm707 1 day ago | parent
> > "the standard evidence we had for that belief was misunderstood."
The author did NOT misunderstand the evidence of polysemanticity and superposition. Rather, the explanatory hypothesis was incorrect.
Drupon 1 day ago | parent
Not surprising that this philosophical philistinism is from an Anglo publication.
astrange 1 day ago | parent
> Althusserian theory
though I think using this term is rather un-feminist because of the part where he killed his wife, but basically continental philosophers will forgive you for anything as long as you're a French communist.
Athanase000 23 hours ago | parent
tonic_note 1 day ago | parent
Like, I'd get maybe if she wrote this in a NYT opinion piece– but this was written an obscure book you'd have to go out of your way to find.
BTW, this is not that hard to comprehend if you're familiar with continental philosophy, go figure!
Der_Einzige 1 day ago | parent
bilsbie 1 day ago | parent
smokel 1 day ago | parent
lhd1 1 day ago | parent
dwroberts 1 day ago | parent
NaiveEmpiricist 1 day ago | parent
And emergence doesn't need to involve much of the LLM's weights:
> In preliminary audits of Qwen3-32B, we estimate that roughly 90% of neuron poles have one main job, often with small related offshoots; another ~7% have two related jobs; and only ~2-4% are not yet understood
If those ~2-4% are the central hubs of emergent cognition, then understanding 96%-98% of the weights may be less valuable than the author thinks.
emp17344 1 day ago | parent
NaiveEmpiricist 21 hours ago | parent
hargup 1 day ago | parent
When you have only hundreds of them, you can barely add numbers. But the same fundamental technology scaled to millions, billions and then trillions, transistors can do things which will look magic to previous generations.
adsharma 1 day ago | parent
c0decracker 1 day ago | parent
mariano54 1 day ago | parent
x312 1 day ago | parent
The idea is: a model may only have 100M neurons or whatever. But there are infinite concepts in the world. Therefore, models have to "stuff" multiple concepts per neuron.
How do you do that? Theres two ways:
1. Each neuron handles similar concepts. One neuron for dogs, a separate neuron one for cars, etc.
2. Each neuron handles a bundle of unrelated concepts. One neuron handles dogs and cars. Another neuron handles cats and numbers. And so on.
Historically, people thought #2 was correct because many neurons were found that seemingly represented multiple concepts. #2 had a cool name (polysemanticity) and was promoted in OpenAI/Anthropic blogs so it had a lot of traction.
However, this blog says #2 is wrong. Actually, the dog/car neuron is just a "V shape neuron". So #2 was just methodological error, and #1 was right all along. This is all the blog is saying.
stillpointlab 1 day ago | parent
My impression, being a total outsider, is that the reaction feels like a bunch of insider bros hyping up their insider bro friend. It feels more like PR than a genuine groundswell behind a truly revolutionary idea.
DennisP 1 day ago | parent
It might still be quite difficult since the network is huge, and just because you know what the individual neurons represent doesn't mean you understand the complicated thoughts they're building. But easier than expected is still good news.
jephs 1 day ago | parent
How much would it cost to find those things, if they exist? For using the blog post's methods to label every neuron in modern arch, Claude and Gemini produce similar back of the envelope math that looks something like, within an order of magnitude of the resources it takes to pretrain the model in the first place. If you have a better way of narrowing down the set of candidates, probably a lot cheaper.
Would that be reliable and useful? Well.
hackinthebochs 1 day ago | parent
D-Machine 1 day ago | parent
Not really, because of emergent behaviours and also because there are still millions of neurons being summed (with variable weighting depending on inputs) at each layer.
> and even constrain its space of behaviors by activating/suppressing a small set of neurons that have very straightforward effects on its behavior.
You can influence behaviour by doing this kind of thing, yes, but it isn't straightforward at all, and is generally very messy and you get all sorts of unpleasant sides effects (e.g. abliterated models not performing as well).
hackinthebochs 1 day ago | parent
Emergent behaviors in terms of seemingly random combinations of features producing unpredictable but coherent/intentional output basically don't exist. In other words, there are no "hidden thoughts" in an LLM encoded in higher order combinations of features. Inasmuch as non-semantic features of the input influence output, it does so in non-semantic ways that are degenerate in terms of the quality of output. The only thing emergent in LLMs is degenerate state leading to a breakdown in tracking relevant features of the input and a reduction in quality of output. But the relevance of this kind of degeneracy to LLM output is at the margins. Tracking activated state predicts subsequent output to a high degree of accuracy.
>but it isn't straightforward at all, and is generally very messy and you get all sorts of unpleasant sides effects (e.g. abliterated models not performing as well).
I expect this has as much to do with our lack of precision in our tools rather than with the concept in principle.
D-Machine 1 day ago | parent
You'll need to elaborate here, because Navier-Stokes plus Mathocalypse reactions are extremely strong evidence for coherent emergent behavior coming out of these models.
> The only thing emergent in LLMs is degenerate state leading to a breakdown in tracking relevant features of the input and a reduction in quality of output.
This is so provably wrong with two seconds of Googling / AI-asking that you must be using some completely idiosyncratic definition of "emergent" here.
> I expect this has as much to do with our lack of precision in our tools rather than with the concept in principle.
Unfortunately in this case it is the exact opposite.
hackinthebochs 1 day ago | parent
I doubt my usage is idiosyncratic. Rather, the term is so ill defined that people often use it inappropriately. Emergent means something along the lines of not easily predictable behavior from the behavior of the component parts. My claim is nothing in LLMs is emergent in the sense of being inexplicable from an ideal consideration of simple/linear aggregations of its neurons. This isn't something I can prove, but it certainly isn't obviously false from just considering recent mathematical results. Higher order/non-linear interactions are characteristic of this kind of inexplicable behavior from complex interactions we characterize as emergent. But there are good reasons to think this kind of non-linearity in any semantic regime is next to impossible in principle.
Semantic geometric representations are characterized by linearity in response dynamics such that a linear change in one variable results in a linear semantic change in related variables. That's how vector embeddings capture semantic relationships. Call it the linearity hypothesis. Non-linear dynamics in the embedding space just destroys semantic relationships in most cases. There is no way to keep an entire network of relationships sufficiently correlated if non-linear response dynamics is a part of the representational toolbox. Non-linear dynamics in general kills correlations.
Testing this against recent LLM proofs, what would need to be shown is that the relevant neural activations do not decompose the semantic content of the proofs (or the reasoning trace) in a straightforward manner, but rather the reasoning trace is unpredictable from the semantic content of the activated neurons that precede the tokens of the reasoning trace. But this idea strains credulity; it is almost inconceivable that this would be the case. We should be highly incredulous of the idea that complex non-linear interactions can be wholly responsible for the long-running coherent output in LLMs. The default hypothesis should be that there is no emergent behavior (as I defined it) in neural networks.
D-Machine 17 hours ago | parent
Yes, partly. But it also refers to complexity arising from the component parts that requires additional tools (formulas, descriptions, etc) to meaningfully describe. Or at least, emergentism has always formally involved more than mere predictability from parts (https://plato.stanford.edu/entries/properties-emergent/). I am talking about weak emergentism here, so no need to get into metaphysics and mysticism.
> My claim is nothing in LLMs is emergent in the sense of being inexplicable from an ideal consideration of simple/linear aggregations of its neurons.
IMO this contradicts even your minimalist definition. Almost no one predicted simple LLMs would be where they were today, and you can't currently predict their behavior by looking at their weights.
Something doesn't cease to become emergent if you can roughly explain it by making references to its parts. We can broadly explain how human behaviours result from drives + sensory processing + associations and etc., but human beings are not very predictable in many cases, and also exhibit consistent behaviors that tend to be very hard to predict (or even explain) from basic knowledge of the brain, drives, and body. LLMs are no different, and what they are doing today couldn't be more clearly emergent, even by your definition.
Also, something doesn't cease to be emergent even if you can perfectly explain it with reference to the parts. E.g. attractors are emergent behaviour, even though they fall out of very simple formulas and so in a sense are completely due to their defining parts. But describing the shapes of e.g. the Mandelbrot set or the Lorentz Attractor requires more than the base formula that generated them. So they are classic examples of emergent phenomena. Likewise, a person's intelligence might one day be fully predictable from biological and genetic knowledge and measurements, but it wouldn't mean that intelligence stops being an emergent property that is still observable and useful to use itself in other models.
You can for example argue that an LLM has no emergent drives (https://xxcancel.com/jon_stokes/status/2111158233993797870#m), and that would be a coherent claim, under a certain definition of "drive".
But your argument here I cannot follow clearly, because LLM behavior is clearly emergent in any sense of the term, including yours. EDIT: Or basically, LLMs show weak emergence, but if you disagree with this, then it would seem to me you perhaps disagree with the concept of emergence at all.
hackinthebochs 15 hours ago | parent
Whether some trait is emergent shouldn't depend on the state of our knowledge. That no one predicted how far LLMs would go is a demerit for our model of them and doesn't imply they have extremely complex "emergent" interactions. My conception of emergence is asking whether something can be "easily" predicted from an ideal understanding of the component parts. Simple/linear aggregations of the correct semantics of precursor neurons is what is at stake here. In other words, is understanding the semantics of the precursor neurons the vast majority of the hard part in understanding what comes next? Past failures of prediction do not bear on this question much at all.
An example from the article that is informative to my view is the association the network made to the base64 encoding of plain text substrings. If you had asked me, I would have assumed the network decodes base64 live as it traverses the layers. Instead (at least some of) these associations are precomputed during pretraining and recorded in the form of shared affinity in neurons. Active computation and precomputed associations are on two ends of the intelligence spectrum. The human brain is strongly biased towards precomputed associations. It seems that LLMs are as well. The more I see about their inner workings, the more I suspect they operate mostly in the form of these explicit associations. The computations they actively manifest across the network can't be that complicated due to depth constraints. There just aren't enough compute steps[1] for the kinds of complex, non-linear, unpredictable dynamics you get from compute heavy regimes.
>Something doesn't cease to become emergent if you can roughly explain it by making references to its parts. We can broadly explain how human behaviours result from drives + sensory processing + associations and etc.
When I talk about explaining some phenomena, I mean it in a robust sense that e.g. gives you the capacity to predict downstream behavior with high accuracy.
[1] These discussions always seem to have difficulty distinguish the computation that realizes the system from the computation the system as such engages in. There is a huge amount of compute that realizes the feed forward pass of an LLM. But the computational steps directed by the LLM to resolve its output from the prompt is severely restricted by the layers in the forward pass of the network (or however many virtual layers from looping).
jacquesm 16 hours ago | parent
mike_hearn 1 day ago | parent
But if (1) is correct, and Nick presents strong arguments that it is, then you can toss out all the indirect stuff like training dedicated interpretation networks. So the techniques can scale and be trustworthy.
samat 1 day ago | parent
Original article desperately needs an editor. Like a real one, not Claude or whatever. Your tldr is 100x more understandable
Thank you!
lukewarm707 22 hours ago | parent
A father is continuous opposed to boolean. 'Father' would rank highly in semantic similarity to a man who has a child, but father-like is better, easily someone is more or less father-like. A woman without a child has a certain value of 'father'.
But really the direction 'father-like' is not an intrinsic feature of semantic space, it is a human construction. Much the same as it would be arbitrary to measure 'v shape'.
I don't think that the latent space has a property or point 'v shape'. My view is that there are no concepts or neurons there. Discrete abstractions are not intrinsic properties of the model. Actually I think the abstractions of concepts or neurons do not map onto anything.
A nice example from cot itself is pareidolia. That is, seeing faces in clouds, or jesus on a piece of toast.
wilmichael 1 day ago | parent
QuadmasterXLII 1 day ago | parent
QuadmasterXLII 1 day ago | parent
aesthesia 1 day ago | parent
janpmz 1 day ago | parent
dleeftink 1 day ago | parent
Even when similar weight activations arise across learning regimen it seems we will miss a whole range of interpretations if we just go off 'the text'. The outside context in which a neuron arises is equally, if not more, telling; its genesis cannot (yet?) be quite captured by the weight itself.
The network may reveal its own context and history, but what can ultimately be encoded in its weights that originated outside the network?
mike_hearn 1 day ago | parent
monideas 1 day ago | parent
If you want to learn more about this, this is what depth psychology is about (Carl Jung, et al).
This is also essentially the idea behind monotheism vs polytheism. It's about engaging with and trying to understand the profound underlying unity of the myriad phenomena.
sigbottle 1 day ago | parent
But isn't the point that the neural nets learn some insanely abstract ideas anyways? So whether the complexity is "ahh we think this neuron does 100 seemingly unrelated things but we don't understand it" or "this actually is some kind of latent shared feature, but we don't know what the concept represents because the composition of the entire circuit is an arcane algorithm", we're kind of stuck, no?
This seems like a classic model-description issue more than anything.
ricochet11 1 day ago | parent
Philip Arge strikes again
sigbottle 1 day ago | parent
Although I wouldn't say just yet that Heiddeger was validated. I don't even know what he's saying 90% of the time, honestly.
questionable_ju 17 hours ago | parent
The classic Cartesian view was that we take in raw data from the outside world and process it into more and more abstract concepts (somehow), until we say "aha! I can use this for hammering". Heidegger says that this view is wrong, and our first experience of things is in terms of a social context and in terms of use. That's what's meant by us experiencing them as "ready-to-hand".
From the starting point of the ready-to-hand, we can step back, take a scientific view, and arrive at the present-at-hand, where we examine the properties of the object seperate from its use. The argument is quite compelling, and especially convincing to me is how well this agrees with modern neuroscience. In reality, 3x as many neurons path FROM the high abstraction parts of the brain TOWARDS the visual processing parts of the brain. In the classic Cartesian view of the brain beginning with the signal and abstracting its way towards the top, this is very mysterious. In Heideggers account, where the social context and potential uses of objects are the primary constituents of our experience, this makes total sense.
sigbottle 16 hours ago | parent
questionable_ju 16 hours ago | parent
This is also what he means by "thrownness". Our being-in-the-world, in particular the way things have meaning to us and are intelligable, is conditional on our use and our social context. Not the other way around. We never logically arrive at our context, we were always already "thrown" into it.
I think it's actually quite a profound conceptual shift, which is why Heidegger is so popular. He's still an asshole for writing so obscurely, though.
sigbottle 15 hours ago | parent
Heck even Hegel and Heidegger were orthogonal (I believe? I'm not sure if Heidegger responded either favorably or not to Hegel - I think he wasn't really responding to him, more to the Greeks and Kant) to each other. That's weird.
And Sellars can say he rejects the Myth of the Given but inferentialist is very much not a phenomenological theory. Accepting that "nouns" are not some representation relation, not "some thing we have yet to achieve but has an end goal / we refine it", etc. still doesn't get you to Heidegger I feel, either.
Like, there are so many positions circling around Heidegger, but only Heidegger has a distinctly Heideggerian feel. Maybe I'm overcomplicating it though. I think it's because he's distinctly making a claim about the human experience, whereas all the philosophers I've listed, you can list aspects of them that get away from that (even Kant lol). They've been "naturalized" in some sense. You can't naturalize Hediegger, but then I'm not sure why his theories are better than say, idk, science. You can diagnose the common prejudices of thought through a lot of other philosophers
questionable_ju 3 hours ago | parent
sigbottle 1 day ago | parent
The philosophical issue I have can be decomposed into two parts:
1) What is the base ontology of what the neural nets thinks exist? 2) How do you recover, and begin to understand said ontology?
Modern researchers obviously want the goal of simplicity & composition, but to arrive at that, they build abstractions like transcoders and SAE's to get into their pet ontology (with the assumption that neurons themselves are garbage to understand). This obviously raises the question - why privilege your basis? Having a grand result, actually be an artifact of your bad representation is a tale as old as time. Even things like the PRH need to compare higher-level concepts like this.
The specific empirical claim is that, for the rightly structured & trained & large models that don't need to encode hodgepodges of bullshit, the neurons themselves are sufficiently atomic to be studied, dissolving any need to go to some intermediate layer in which we need to question "is this an artifact of our representation?" The resulting interactions between said neurons may be incomprehensible, but the point is that this provides a layer of objectivity (note: not claimed that "the neural nets found the objectively right abstractions in idea space", but rather that the neurons themselves are atomic).
There's still an issue here in that okay, even if neurons are atomic, humans have to ascribe some interpretation to them, separate from the problem of the composition of the atoms, which humans also have to interpret. But if he's right, then you do actually have this privileged base layer to work with, even if you don't know what the base layer means. That's pretty important, actually. Assuming this holds up in reality, ofc.
(There's an argument as to why we should even start from this line of inquiry but whatever lol)
D-Machine 1 day ago | parent
I agree.
> Modern researchers obviously want the goal of simplicity & composition, but to arrive at that, they build abstractions like transcoders and SAE's to get into their pet ontology (with the assumption that neurons themselves are garbage to understand). This obviously raises the question - why privilege your basis?
Agreed, and IMO the implicit reason for privileging here is supposed to be "consistency with existing human understandings and concepts", and this is why we get short pithy things like "V-shaped" and lots of pictures showing relatedness that we all can see and agree on. But what if the domain of inputs is NOT something we understand (e.g. the whole of mathematics, or something new or that we don't have any understanding of)?
I called this a validation problem in another comment here (https://news.ycombinator.com/item?id=50108184). I.e. if we apply whatever methods Nick is using to "explain" a model on a domain we don't understand (like a deep model trained only on fMRI and EEG data of the whole human brain in various contexts), we aren't going to be able to tell if that description is correct (or just better than any other description), because there is no simply visual / common-sense inspection of the description.
> The resulting interactions between said neurons may be incomprehensible, but the point is that this provides a layer of objectivity
Agreed, emergent behaviour is clearly the case and limits how useful understanding individual neurons can be. IMO this is especially the case because layers are (weighted) summing generally millions of contributions from previous neurons.
> But if he's right, then you do actually have this privileged base layer to work with, even if you don't know what the base layer means. That's pretty important, actually. Assuming this holds up in reality, ofc.
Yes, it not being "chaos all the way down" is good, actually. And this post shows there is indeed a good amount of order hidden away if you look at in the right manner.
mike_hearn 1 day ago | parent
Nick is saying that:
1. Actually, no, humans don't have to ascribe interpretation because AI is very good at figuring out what the commonality is.
2. Even when it can't see either by incrementally exploring the networks and checkpoint timelines, things that appear random on the surface can actually be explained with more work.
> Assuming this holds up in reality, ofc.
Nick says repeatedly that this does hold up in reality and he's been able to explain many neurons this way. Very promising results!
itissid 22 hours ago | parent
if I understand taking LLMs as an example certain neurons will fire based on certain motifs, then one can change the phrases or sentences around that motif and _predict_ if the same neurons would fire.
Like if I said "I like cars, but I like rockets better. Can you suggest some rocket models to fly?" and Neuron X fired every time it saw a `, but` and attended to what followed it, that would give you a good way to _understand_ when it changed and what might have caused it.
My understanding is that this is now clearly visible behavior.
theptip 14 hours ago | parent
The claim is closer to the latter (monosemanticity) but also claiming that the concepts are mostly comprehensible and not arcane.
(The best arguments against this being a full solve of interp that I’ve seen go like: “we expected most of the complexity to live in the circuits, anyway”.)
D-Machine 1 day ago | parent
https://xxcancel.com/NeelNanda5/status/2110875974296654062#m (and the re-post on LessWrong: https://www.lesswrong.com/posts/x4kvabkF2Jk8GLZp8/linkpost-n...)
TL;DR:
This is interesting work, but I don't think it's a significant update to the big picture of interpretability. [...] I'm on board with the broad idea of doing exploratory interpretability with neurons, e.g. neuron-based attribution graphs, for pragmatic problems like why did a model do a sketchy thing? I think this work provides some reasonable evidence, in addition to good earlier work from Transluce, that this might actually work for practical purposes, and has some advantages over the standard alternatives like SAEs/transcoders. I do not agree with some people's grander inferences like that this is substantial progress towards ambitious reverse engineering, solving interpretability etc.KingMob 1 day ago | parent
> Part of the reason was not knowing about generalized pose neurons
I have to ask, did they not look up how the human visual system works? The primary visual cortex has any number of early neurons that are spatially-tuned for various shapes and edges, and this is pretty basic knowledge.
In fairness, neural networks are more divergent from biology than a lot of people think, but it seems there's still low-hanging fruit to be grabbed with a minimal collaboration.
xpct 1 day ago | parent
Trusteando 1 day ago | parent
Ericson2314 1 day ago | parent
imtringued 1 day ago | parent
Two eyes, a nose with whiskers [0], a mouth and a protruding shape, four legs and a tail [1].
A car and a cat might as well be the same thing.
[0] the logo on the radiator surrounded by horizontal stripes [1] tow hitch.
itissid 1 day ago | parent
If its grouping circuits based on motifs and when they fire — and it applies to large networks — then one should be able to literally query or debug a reconstructed database and check against actual activations. More importantly If this was a hand-wavy thing to do earlier for safety, it's not anymore because it's on more solid ground using Normal Science.
addag 22 hours ago | parent
If those results hold, it is a real breakthrough in the sense that it is a sharp simplification of an actually complicated problem.
_alternator_ 22 hours ago | parent
This type of error may have mislead researchers for years; it was actually harmful. In my field, a correction, or perhaps retraction (depending on the centrality of the claim), would be standard for something of this magnitude.
I suppose there are different standards in different scholarly communities. And maybe it truly was impossible to know at the time that the dog/car relation was actually a V shape, but my recollection is that this type of feature was well known at the time and so the error could have (should have?) been caught a decade ago.
So: massive new discovery, or a spin on a correction that's lead scholarly research astray for almost a decade?
bonoboTP 20 hours ago | parent
sheepscreek 21 hours ago | parent
wvlia5 19 hours ago | parent
questionable_ju 17 hours ago | parent
I especially enjoyed this subtle joke: "We think the weak activations usually don’t matter, but the strong positives and negatives matter a lot. For instance, Santa lives on the negative pole."
I can only imagine how much joy he felt writing that.
As for serious comments on its content, I'm confused by the people who considered it difficult to read. I think the ideas presented were very elegant and fairly simple to understand. Considering neurons as gates and weights as votes was a nice way to look at it, for example. I didn't feel like the post was unnecessarily long either.
One thing that stands out to me is how ridiculous it is in the first place to try to assign a short, natural language description to the function of any particular neuron. Wittgenstein already talked about how humans seem to use words in very specific ways while being terrible at exhaustively describing why.
An example is the word "game". It's very easy for even a child to distinguish between "game" and "not a game". But it's incredibly difficult to write down a precise definition of "game" that includes everything normally considered a game and excludes everything that isn't considered a game. Writing down the function of one specific neuron seems to run into this issue. When you write down what the exact function of any neuron is, there's a good chance your clunky natural language description misses some fine nuances.
A reasonable analogy, in my view, would be that neurons could represent something like the atomic components of intuitions or "vibes". Similar to the example of "game", the feeling of knowing what is or isn't a game is composed of what Wittgenstein called "family resemblances". Your brain doesn't contain a precise description of "game", but upon encountering something, you can quickly compare it to other examples of games you've seen and intuit whether something has a "game-like vibe".
Another notorious example would be "what is a woman". For some reason, everybody has very strong feelings about what is and isn't a woman, but people have a terribly difficult time perfectly describing it. I would guess that neuron activations function like these vibes or intuitions, rather than written rules.
I very much liked the parts discussing circuit ecology. This idea sounds very promising for alignment to me.
kazinator 16 hours ago | parent
If the field of neural net legibility develops tools for identifying plagiarism, that would be great. If we can trace output as derived work of certain specimens of training data, we can then clamp down on all the stealing.