1462 points 737max 3 days ago 1042 comments
username_my1 3 days ago | parent
idbnstra 3 days ago | parent
w4yai 3 days ago | parent
nitinreddy88 3 days ago | parent
bigyabai 3 days ago | parent
theplumber 3 days ago | parent
bigyabai 3 days ago | parent
modeless 3 days ago | parent
llmslave 3 days ago | parent
The fact that multiple companies can breach any benchmark means there is no ambiguity in terms of how to build AI, its just a matter of time.
Certainly Meta and Google are benchmaxxing to please public markets, but it still proves the above
efficax 3 days ago | parent
alecst 3 days ago | parent
verdverm 3 days ago | parent
isqueiros 3 days ago | parent
I wonder how much is actual improvements in the model and how much comes from better harnesses. I'd be willing to bet that the combination of better harnesses + the models being trained around agentic workflows (i.e the harnesses) has made it significantly better in many things, but it's hard to find other improvements imo.
alecst 3 days ago | parent
4dd3aa 3 days ago | parent
llmslave 3 days ago | parent
verdverm 3 days ago | parent
A more intelligent model would not default to spaghetti throwing, it would pause to consider the problem fundamentals, the accuracy of assumptions, and ask questions that remove ambiguity. This however does not lend itself to increasing token sales while prices remain inflated from market and brand dominance.
efficax 3 days ago | parent
david-gpu 3 days ago | parent
cma 3 days ago | parent
CuriouslyC 3 days ago | parent
IanCal 3 days ago | parent
Like a working scroll on a webpage.
God damn this is impossible to use of safari mobile.
rs_rs_rs_rs_rs 3 days ago | parent
jedbrooke 3 days ago | parent
InvisibleUp 3 days ago | parent
pierreozoux 3 days ago | parent
oh_no 3 days ago | parent
dymk 3 days ago | parent
yipinwong 3 days ago | parent
Argon is trying to solve the "hard" problems like those.
layer8 3 days ago | parent
boutell 3 days ago | parent
InsideOutSanta 3 days ago | parent
tekacs 3 days ago | parent
catigula 3 days ago | parent
owlninja 3 days ago | parent
verdverm 3 days ago | parent
I like this phrasing and am curious what new word or phrase we might use to describe big companies over pushing Ai internally at the expense of their product quality. This pattern is so ubiquitous across google cloud products I have taken to calling them the 21st century IBM, having been a IBM baby and witnessing first hand their fall from exceptionalism.
wyldberry 3 days ago | parent
catigula 3 days ago | parent
cmrdporcupine 3 days ago | parent
And took similar companies that were quality engineering focused -- like DEC or Palm -- down with them through acquisition.
mistic92 3 days ago | parent
xbmcuser 3 days ago | parent
fridder 3 days ago | parent
ano-ther 3 days ago | parent
wslh 3 days ago | parent
Gallows4574 3 days ago | parent
edit: It failed on the second prompt and they disabled it now.
melasadra 3 days ago | parent
EDIT:
Apparently Ultra subscribers gets Argon everywhere including in Google Antigravity
Pro subscribers only get them in Gemini app and Search
jonesy827 3 days ago | parent
https://antigravity.google/blog/gemini-4-argon-in-google-ant...
niek_pas 3 days ago | parent
> Gemini 4 Argon is available today for Google AI Pro and Ultra subscribers
ehsankia 3 days ago | parent
1. It's available to Pro in Gemini app, but NOT antigravity (for coding)
2. It's a phased rollout and Ultra got it first, Pro is coming later
The latter blog post is specifically "Argon in Antigravity" versus the other blog post is about Argon in general, so seems like #1 is more likely.
efficax 3 days ago | parent
copperx 3 days ago | parent
caminanteblanco 3 days ago | parent
https://one.google.com/about/google-ai-plans/?icid=microsite...
freakynit 3 days ago | parent
It seems to be rolling out gradually.. not available at once to everyone.
ChadNauseam 3 days ago | parent
It's crazy to me how care there is in most of these vibe-coded vibe-coding harnesses. I don't like oai's models much but I have to say their UI has by far the best attention to detail of any major player.
SwellJoe 3 days ago | parent
yegle 3 days ago | parent
It doesn't show in the desktop UI.
rahimnathwani 3 days ago | parent
frangonf 3 days ago | parent
> Gemini 4 Argon (Medium)
Unavailable · Gemini 4 Argon is currently available to Ultra plan subscribers.ehsankia 3 days ago | parent
p_l 3 days ago | parent
schleck8 3 days ago | parent
hnfong 3 days ago | parent
bretpiatt 3 days ago | parent
    Antigravity CLI 1.3.4
    [My account email] (Google AI Ultra)
    Gemini 4 Argon (High)
    ~/[working folder]

  > /model
⎿ Model set to Gemini 4 Argon (High)zf00002 3 days ago | parent
aliljet 3 days ago | parent
Now, I happen to believe that's an excellent strategy. I bet they actually resolve more LLM requests than any other company at this point. The lay person still uses Google exclusively.
nateb2022 3 days ago | parent
hersko 3 days ago | parent
acmotifs 3 days ago | parent
paimapi 3 days ago | parent
I use the hell out of both. Kind of sad that they took Spark out of beta-access, being able to orchestrate via your phone on something that has direct access to your Drive meant I was authoring skills and other functionality on a schedule with spreadsheets serving as databases, deterministic tests, etc.
Hope they roll it out to a full feature soon
ASalazarMX 3 days ago | parent
paimapi 3 days ago | parent
freecodeio 3 days ago | parent
if they throw in youtube premium in that package then I might reconisder
lanthissa 3 days ago | parent
they gave away so much pro that they need to have smaller usage levels than competitors or they'll lose a ton of money. $20 was already a loss for users actually using their quota. the majority of pro users are paying far less than that.
so they'll lose their paying users, and keep their free or subsudized, which will make the economics even worse.
sroussey 3 days ago | parent
cubefox 3 days ago | parent
sroussey 3 days ago | parent
dbuser99 3 days ago | parent
tireonfire 3 days ago | parent
verdverm 3 days ago | parent
steego 3 days ago | parent
More specifically, who are they targeting with Argon and why is it behind the Ultra plan? Who is paying $99/month if not developers?
fschuett 3 days ago | parent
Corporate companies. Bog-standard office workers don't need top-of-the-line Mythos intelligence, just something to add to Google Workspace. I personally doubt developers use Gemini for coding beyond marketing materials.
alephnerd 3 days ago | parent
verdverm 3 days ago | parent
There is another subset in the Google Workspace for enterprise clients.
dieortin 3 days ago | parent
steego 3 days ago | parent
Because if it’s not, and it’s not available to all paying users (Right now, it’s only available to Ultra users), then they are behind the curve if they’re treating it like Fable.
It’s tone deaf.
epihelix 3 days ago | parent
Whether it's actually better than OAI/Anthropic offerings, probably not, but if Google has managed to get back to parity, that's good for competition, prices, and increased model performance in the future. Three strong western competitors is better than two.
I_am_tiberius 3 days ago | parent
w4yai 3 days ago | parent
redox99 3 days ago | parent
Unique users, maybe. But a simple query that's answered in a paragraph is negligible compared to devs running agents continuously for tens of hours.
freecodeio 3 days ago | parent
redox99 3 days ago | parent
When I see non technical people use that Google reply I'd be surprised if it's more than 1k output tokens, and with a tiny model. So a 3000x in output tokens, on a model at least 10x as expensive, I wouldn't be surprised if hardware usage is 30.000x for a dev that uses coding subs vs someone who uses the Google AI overview a couple of times a day.
And that's not counting the absurd difference in cache reads.
sva_ 3 days ago | parent
That was a long wait.
timpera 3 days ago | parent
verdverm 3 days ago | parent
postalcoder 3 days ago | parent
I've been trying it out via the API and the model has been a delight so far. Clear in the head, not RL-fried, distinct writing style, and big model smell. That said, the em-dash is back w/ this model.
That said, I would be so frustrated with Sundar Pichai if I was on the Google team. The botched rollout of this model seems to be entirely a matter of capacity, and Pichai has been more than happy to give it to anybody but his own team.
algoth1 3 days ago | parent
thmorriss 3 days ago | parent
kypro 3 days ago | parent
I think there was a lot of misplaced hate of the em-dash due to all the low-qualify AI slop people were trying to pass off as their own for a while.
algoth1 3 days ago | parent
leoooodias 3 days ago | parent
johnisgood 3 days ago | parent
gfody 3 days ago | parent
Quarrel 3 days ago | parent
If you just want good llm text, it’s great.
postexitus 3 days ago | parent
postalcoder 3 days ago | parent
At the same time, OpenAI had a disastrous dev day that led a lot of users to jump ship to Claude.
Couple weeks later, Gemini-4-argon is still unavailable on anything less than the ultra tier, which means there's no natural funnel to get ppl to pay for the more expensive ultra plan other than "trust us the model is good".
If Google had argon broadly available earlier this month they would have picked up a ton of new users.
kranke155 3 days ago | parent
Narrating this as if it’s the game of thrones is a fun exercise, but it’s just becoming commonplace now that models jump ahead of each other on a weekly to Monthly basis.
nomel 3 days ago | parent
This was part of the issue, as stated in their comment. We couldn't jump around to try it for the reason that is wasn't made available to, as you say, "all the power users".
msabalau 3 days ago | parent
I mean, I heard rumors too that it would be ultra only, but that doesn't seem to be the case, unless you are specifically talking about antigravity?
Realistically, market adoption isn't going to be the result of terminally online people (like me, I confess) following things way too closely on social.
doodlesdev 3 days ago | parent
edit: just a few hours after this comment I got access to Gemini 4 on the Gemini app. Yayy! :)
Ternari 3 days ago | parent
https://blog.google/innovation-and-ai/models-and-research/ge...
doodlesdev 3 days ago | parent
asdfman123 3 days ago | parent
Models move so fast now and Google is very cautious about releasing them.
justinhj 3 days ago | parent
varispeed 3 days ago | parent
Then basic mistakes (inferring wrong information from the given text, hallucinations...). Gemini is okay for some absolute basics and the rest of the work goes to actual frontier models.
jimjimjim 3 days ago | parent
BoorishBears 3 days ago | parent
asdfman123 3 days ago | parent
user_7832 3 days ago | parent
Ofc I know this isn't your fault in person, but I really wish Google would get its shit together.
...As a long time tech enthusiast I should probably stop being so delusional. Heh (cries internally)
1: lol I know who cheers for a trillion dollar company but I'd rather not cheer for OpenAI
vardump 3 days ago | parent
asdfman123 3 days ago | parent
As a Google employee my defense is it's hard for a company this big to move fast, but I can understand how Google customers would be annoyed.
BoorishBears 3 days ago | parent
The top level comment blamed cheerleading but let's apply critical thinking for a second as product people and look at the funnel:
1. Potential users sees new release 2. Potential user takes time to install and set up Google harness (you already lost 90% of people here, the funnel better close quick!) 3. Potential user cannot use new model.
Then what? You hope they developed good will towards your model through this experience?
You stuck a two week wait in your funnel? Is that the definition of not having your act together or what?
We're on HN, how many of us have heard from Google staff this kind of stuff is a result of them growing so big that AI Cloud has to compete with Vertex Cloud, and AI cloud exists because Vertex Cloud needed 2 years to get OAI/Ant style API keys working and were losing dev mindshare in the meantime?
BoorishBears 3 days ago | parent
vessenes 3 days ago | parent
What sucks, hard, is googles ability to deploy direct to devs and customers at scale when the deployment is not a longstanding Google project.
Case in point: I’m an ultra subscriber and see in my app right now an ad to try Gemini 4; meanwhile the only models I have available are 3.1 pro,3.6 flash, and 3.8 thinking.
Clicking the try gemini 4 link takes me to a demo prompt that loads 3.6 flash. Srsly
I won’t even start telling you what getting api key based access together was like a year ago.
meowface 3 days ago | parent
Unless Gemini CLI greatly improves and Argon works well in it, this probably won't make a dent in the coding market.
michaelbrave 3 days ago | parent
Please google, just make it easy for me to give you money and get what I paid for.
iforgotmypasswo 3 days ago | parent
We’re all running on Astra medium the whole week and loving it.
I’m curious what I missed.
alex0015 3 days ago | parent
bitexploder 3 days ago | parent
iforgotmypasswo 3 days ago | parent
$500/month for 40+ hours a week of Astra usage, with ultrafast mode available when you’re near the weekly reset has made our jobs so much easier. Our product has some sciencey bits as well, ands Astra kills it as a rubber duck in this area.
As a consumer whose 20x account got downgraded, I am a bit sad. I can’t justify $500 a month on personal AI spend. As an engineering manager, I could not be happier with OpenAI’s services. Also, Codex App Server is amazing.
discreteevent 3 days ago | parent
Hey, account created 39 days ago. Did you really have to tag that on after all the other stuff? Could you make it any more obvious?
That said this thread is hilarious because it's just an open ai sales manual debating with an anthropic sales manual. It's funny, but it's not, because the truth is that you people are just shitting all over the commons. Someone needs to kick you out but that's not going to happen here.
bitexploder 3 days ago | parent
iforgotmypasswo 3 days ago | parent
Claude refuses to help you build your own harness off a subscription, and OpenAI actively encourages it with Codex App Server. So you’re just in an AI IDE customized to your job and specific needs ALL THE TIME. You know that good feeling you got when your CI pipeline was finally working, back when that involved speed reading documentation and guessing, or staying at work until 10PM? You just get that all the time because life is constantly improving. And your tools are beautiful and riddled with Easter eggs you put in them. There’s so much more time to test and talk to stakeholders because you are able to distribute the thing you are actually good at -solving people’s difficult problems- while following best practices. You used to have to weigh those two every day and it was terrible. And everything was always late. You had to cut so many corners you were delivering circles.
Now life is fun and I’m over-delivering. Constantly. With super high code quality, better test coverage, easier audit prep, and I just explain what I want (technically) at a high level to AI. I still have to code review, and it sucks. Not because the AI needs it, but because auditors need it. I think I can make it faster and easier in the near future with another custom tool.
I actually have time to make architecture diagrams. I have never had enough time to build that level of documentation.
With Fable, I felt the promise of this coming. With Astra, I feel like we finally had the resources to fully professionalize and supply our software team.
We actually need to hire more people next quarter.
I am with the creator of Rails on this. It is a time of joy. Now is the time to become more ambitious.
magimas 3 days ago | parent
In my experience, this has always been the advantage of OpenAIs models.
Throughout iterations, Claude is better at pure coding, but the GPT models are better at "scientific reasoning".
smoe 3 days ago | parent
holoduke 3 days ago | parent
motoboi 3 days ago | parent
Can you elaborate on this?
simonw 3 days ago | parent
Reddit thread with 247 comments here: https://www.reddit.com/r/codex/comments/1wtgv3z/dev_day_l/
Aside from that I'm not sure what was "disastrous" - maybe the lack of a new model release to compete with the just-released Claude Opus 5.5?
AspireOne 3 days ago | parent
- Dots. People don't understand it. Their presentation didn't explain it properly at all. Additionally, many people thought it's stupid, and that the cutesy mascots are dystopian.
- Voice mode didn't work in their presentation. The demo failed.
- 200$ plan goes 20x -> 10x usage. 500$ plan introduced, 25x usage. The contrast is stark.
- "Ultrafast": 8x pricing on subscription plan (6x API). That's 80$ input, 400$ output, 100$ cache write. Hello?! Additionally, since it generates 8x faster, it consumes your quota 8x faster. Per wall-clock minute, it's 64x more usage spend per minute of generating. People report that on the 500$ plan, their weekly usage is gone in 40-100 minutes.
- People believe gpt-6.1-sol was planned to be released as astra-minor, but OpenAI renamed it at the last possible time, because gpt-6-sol is a disaster (this I can get behind)
keyle 3 days ago | parent
'backlash' is underwhelming. They single handedly murdered 5.3 codex which was great by making it slooow and duuumb, and pushed people over to their new ones. 5.6 was a decent candidate but it was so slooooow.
And then double or triple the cost for Plus and Pro by nerfing their effective power? I never looked for an alternative faster. They really screwed the pooch.
Been quite happy with deepseek v4.1 flash, muse 1.3 and haiku 5.5.
topspin 3 days ago | parent
Oh yeah. Completely forgot about that. Big headlines and big claims, but no one could actually use it and report on it.
Does seem like they don't quite grasp how the hype train operates. Or maybe they don't care as much.
polynomial 3 days ago | parent
Given FelonyBench, do we also have a FantasyBench?
jstummbillig 3 days ago | parent
noooooooo
asdfman123 3 days ago | parent
petesergeant 3 days ago | parent
asdfman123 3 days ago | parent
I know it's a matter of personal taste but it reminds me of a grad student that tries to sound smarter than he is by being dismissive and opaque.
rad-b 3 days ago | parent
chpatrick 3 days ago | parent
elcomet 3 days ago | parent
I don't want ELI5, I just want the model to go straight to the point, like a colleague human expert would do.
chpatrick 2 days ago | parent
rixed 2 days ago | parent
mattlondon 3 days ago | parent
IndySun 3 days ago | parent
Strange. I wonder why? Have you adjusted 'roles', added 'ask clarifying questions'? This is most peculiar.
geertj 3 days ago | parent
> You gave me a long answer but it didn’t answer my question: can we safely remove $X
flockonus 3 days ago | parent
Great model to architect and resolve eng. problems in a harness loop tho. Poor handoff.
FranzFerdiNaN 3 days ago | parent
bitexploder 3 days ago | parent
andai 3 days ago | parent
onevsall 3 days ago | parent
I haven't tried Argon, but for writing, I actually prefer 3.8 Flash over any GPT and Opus.
baq 3 days ago | parent
cluckindan 3 days ago | parent
bitshiftfaced 3 days ago | parent
xd1936 3 days ago | parent
lackoftactics 3 days ago | parent
Em dashes ended up as one of the first victims of llm age
TeMPOraL 3 days ago | parent
In other words, since the very start of computer era, the use of em dashes was always a signal.
TeMPOraL 3 days ago | parent
So obviously, government documents, top publications from liberal arts scholars and STEM > Wikipedia > Reddit (and within, r/AskHistorians > r/all, etc.). The first group is the one most likely to (over)use correct / fancy typography.
I have a related pet theory: the telltale sign of AI writing is being too good for the context it's found in, in terms of vocabulary and style as well as structure.
What is jarring about this is precisely the quality - we associate certain styles with important (or self-important) venues, so it's uncanny to suddenly see random shitposts, copywriting spam, or regular chat replies look like work of NYT bestselling authors or legal scholars - it feels wrong in places we expect basic language, grug-brain reasoning, and lots of typos.
Also, what makes the above much more noticeable, is that AI systems don't have cross-session stylistic memory. From the POV of an LLM, that perfectly fitting, masterfully crafted starter is the first and only time it used it. From the user's POV, it's the tenth time they're seeing it in the span of an hour.
astrange 3 days ago | parent
TeMPOraL 3 days ago | parent
Doesn't change my point anyway - even if post-training, labs naturally want the LLM to come off as smart (well, except for Grok). Post-training is where they "untrained" em-dashes and such, due to complaints of users.
xienze 3 days ago | parent
Agent: _wall of text_
User: yeah sounds great, do it
Which has the predictable outcome of biasing towards wall of text responses.
solyin 3 days ago | parent
InvisibleUp 3 days ago | parent
Retric 3 days ago | parent
LLM intentionally randomize output to cover up all the plagiarism, but this largely destroys the consistency that cause writers to feel unique. Larger patterns still emerge but it just feels stale.
TeMPOraL 3 days ago | parent
Models absolutely do have voices. Spend some time using them, and you'll see. I can easily tell Claude-written prose apart - a consequence of using it daily.
Retric 2 days ago | parent
> not because of plagiarism concerns
I’ve second hand accounts of meetings focused on exactly the problem of how much verbatim text was being spat out and what to do about it. Some versions of specific models are far worse at this but it’s a huge legal liability not to address it.
Christine725 2 days ago | parent
Retric 2 days ago | parent
LLM’s will happily regurgitate multiple paragraphs practically verbatim if you don’t specifically design them not to behave in this way.
Because ultimately when you design a system to best predict the next output based on a given input perfect replication of prior training is the correct response mathematically.
freecodeio 3 days ago | parent
onevsall 3 days ago | parent
Every point is delivered with grandeur and rhetorical flourish. It is hard to reward 'negative space', a simple writing, A to B, vanilla pattern.
Melatonic 3 days ago | parent
epihelix 3 days ago | parent
knollimar 3 days ago | parent
epihelix 3 days ago | parent
I don't ever recall seeing an LLM using them incorrectly, as opposed to simply at high frequency but correctly (although I'm sure some low param or early models must have done so at some point).
dalemhurley 3 days ago | parent
mikestorrent 3 days ago | parent
qlte 3 days ago | parent
They aren't a complete rarity by any means but still relatively uncommon compared to the typical punctuation one sees in routine usage.
I loved em dashes back in high school and my English teacher would have definitely returned an assignment with a lot of red marks if I used em dashes as frequently as an LLM (speaking from experience).
pohl 3 days ago | parent
michaelbrave 3 days ago | parent
Yizahi 3 days ago | parent
"Binds the downstream RF port template—which we configured earlier—to this RPD profile, applying all global DS settings and channel structures to the node's downstream hardware."
Do you see the problem in comparison? The LLM text is assuredly not how humans write. Well, maybe you would find similar examples in the classic literature, but definitely not in a common internet texting or simple articles and posts.
pkulak 3 days ago | parent
dsco 3 days ago | parent
The results are a bit disappointing given Googles scale and training data.
The results are on par with cheaper Chinese open source models to be frank. https://cliphou.se/benchmark/
andybak 3 days ago | parent
I'm not entirely sure you're correct. Your claim boils down to "Writing natural human prose" vs "Broad use of complex software and spatial awareness". My gut feeling is that there's more untapped and fruitful applications in the second group than the first - at least in the short term.
jurnalanas 3 days ago | parent
axblount 3 days ago | parent
Is it actually available?
robotmay 3 days ago | parent
chpatrick 3 days ago | parent
hiq 3 days ago | parent
I'd be curious to see if people have managed to just add custom instructions to make the outputs more standardized and less annoying. I never have such annoying cases, whatever the model, it's just too verbose, but in this case I ask it to be more concise and it's usually fine.
chpatrick 3 days ago | parent
IshKebab 3 days ago | parent
artdigital 3 days ago | parent
Anthropic’s vision of “safe” is so frustrating to deal with, it makes me want to go back to ChatGPT.
lp92 3 days ago | parent
alex1138 3 days ago | parent
dizhn 3 days ago | parent
ckx 3 days ago | parent
jordemort 3 days ago | parent
"Hans, we're doing a new point release! What isn't crossed out on the periodic table yet?"
brainwad 3 days ago | parent
GodelNumbering 3 days ago | parent
e.g.
    X: The Parameters
    Y: The "System"
    Z: The "Ongoing Grind"
Another quite unpleasant tick was that if you specify a peculiar term in your prompt as a conversational shortcut, it would keep repeating that throughout the conversation. e.g. "...What is a bitter lesson pilled way to do this?", then you'd see it will quote "bitter lesson pilled" at like 7 places in its response. This one seems to have eased off a little.
Corence 3 days ago | parent
Insanity 3 days ago | parent
"Across Google", wonder how much that is because of an effort by Google to curb usage of Anthropic models. MSFT and Meta similarly are pushing for in-house models. It doesn't mean the models are better when you push your engineers to dogfood and restrict access to other LLMs.
(Not that I know for sure this is the case, it's more of a hypothesis).
melasadra 3 days ago | parent
nkg 3 days ago | parent
summerlight 3 days ago | parent
lp92 3 days ago | parent
DataDaoDe 3 days ago | parent
fyi: argon is an interesting choice of name, coming from the Greek argos meaning "lazy or living w/out labor".
aleksiy123 3 days ago | parent
DataDaoDe 3 days ago | parent
nephihaha 3 days ago | parent
desterothx 3 days ago | parent
ralusek 3 days ago | parent
I never touch 3.8, it's awful. Curious to try this, but I've yet to use any Gemini that is good for agentic work.
Also, unrelated but this made me look at Artificial Analysis to see where it lands on Cost per Task, and it ranks Opus 5.5 at almost double Astra 6. That does not align with my experience.
bezko 3 days ago | parent
Unavailable · Gemini 4 Argon is currently available to Ultra plan subscribers.
redox99 3 days ago | parent
theplumber 3 days ago | parent
nateb2022 3 days ago | parent
Source? Their documentation says it's available on the $20 plan and I can confirm firsthand.
redox99 3 days ago | parent
upcoming-sesame 3 days ago | parent
it needs MCP asap
nateb2022 3 days ago | parent
upcoming-sesame 3 days ago | parent
Guillaume86 3 days ago | parent
upcoming-sesame 16 hours ago | parent
zarzavat 3 days ago | parent
damsta 3 days ago | parent
Couldn't you just say what the price will be after the introductory period and when it'll take effect? Do they have some SKILL.md for these blog posts that requires the most important information to always be buried ten levels deep and hidden behind a login page?
nananana9 3 days ago | parent
dyauspitr 3 days ago | parent
stymaar 3 days ago | parent
It was the case a year ago, but it's less clear cut nowadays, I've seen non-tech people using claude on their phone in the train, and many tech people seem to have switched from Claude Code + Opus to Codex + Sol over the past few month.
vikramkr 3 days ago | parent
andriy_koval 3 days ago | parent
vikramkr 3 days ago | parent
simonw 3 days ago | parent
$2/million input and $10/million output today. $4/$20 after December 1st.
logicchains 3 days ago | parent
Is Elon Musk doing their pricing?
square_usual 3 days ago | parent
eptcyka 3 days ago | parent
WhereIsTheTruth 3 days ago | parent
It is price fixing, nothing else
ac29 3 days ago | parent
simonw 3 days ago | parent
girvo 3 days ago | parent
It’s still damned capable though, I’ve done a crazy amount of good work with 5.3 Flash.
ac29 3 days ago | parent
wasfgwp 3 days ago | parent
I think at this point comparing raw token pricing is often apples to oranges.
denismi 3 days ago | parent
When that isn't available, and the task involves "understanding the problem", "deciding what I'm actually after" etc. iterations, I find price-per-token to still be a better predictor of cost.
vikramkr 3 days ago | parent
nateb2022 3 days ago | parent
vineyardmike 3 days ago | parent
squidbeak 3 days ago | parent
gcanyon 3 days ago | parent
heaney-555 3 days ago | parent
mlmonkey 3 days ago | parent
jklinger410 3 days ago | parent
mattmaroon 3 days ago | parent
mrandish 3 days ago | parent
+1. FWIW, I didn't even get far enough to wonder about the price.
The lead (and only) sentence states "Our next era of frontier intelligence, built to solve your hardest problems" a statement equally true of any new Google or competitor model, hence completely devoid of useful meaning. I then kept scrolling down... and down... and down, giving up after a half dozen screens of big images, huge videos and some customer stories. The first sentence of every text block was equally vague or meaningless so... tv;dr (Too vague, didn't read).
Even the Gemini sub-reddit is laughing: https://www.reddit.com/r/GeminiAI/comments/1x2dr47/the_lates...
zobzu 3 days ago | parent
apatheticonion 3 days ago | parent
It might not be as smart, though my employer gives me access to Claude, so I tried giving the same task to Opus 5.5. Both DS4.1 Flash and Opus5.5 produced nearly identical outputs.
After that, my company switched the entire engineering department to Azure hosted DeepSeek4.1 and costs were cut by 3/4. So far, no one has really noticed the change.
eyegor 3 days ago | parent
apatheticonion 3 days ago | parent
simonw 3 days ago | parent
Here's low, medium, high. Even low is better than pelicans from any other lab: https://tools.simonwillison.net/markdown-svg-renderer?url=ht...
low cost 10.185 cents, medium was 11.098 cents, high was 17.166 cents.
The costs are similar because it used more output tokens than reasoning tokens for all three pelicans, even for high.
zzulanas 3 days ago | parent
simonw 3 days ago | parent
32297 3 days ago | parent
hyperparticles 3 days ago | parent
anthonyrstevens 3 days ago | parent
boo_you 3 days ago | parent
129751 3 days ago | parent
algoth1 3 days ago | parent
HelloMcFly 3 days ago | parent
soperj 3 days ago | parent
Medium and high are fixies apparently, (or they have a worm gear, although the hub doesn't look big enough for that), since neither has a derailleur. That would also explain the lack of brakes at least.
Low is still obviously failing the "test". It's pedals are not actually attached to the bike either.
Medium has a handlebar that goes through the pelican's beak. So I'd say also failing.
For the high, the only nitpick would be that the bell isn't quite on the handlebars and the stripes on his scarf don't line up correctly.
staticman2 3 days ago | parent
rdtsc 3 days ago | parent
> If it's on HN and is a meme at this point, it will end up in the training set.
> It's kind of fun to imagine that there is an intern in every AI company furiously trying to get nice looking svg pelicans on bicycles.
Google listened and assigned a few interns, I guess, for the task
eli 3 days ago | parent
PorciiVorbesc 3 days ago | parent
eli 3 days ago | parent
PorciiVorbesc 3 days ago | parent
TeMPOraL 3 days ago | parent
PorciiVorbesc 3 days ago | parent
Everyone says that until ms, apple, google, etc introduces this polished feature as part of their tablet imaging editing/document collaboration office suite. Then everyone can;t get enough of it.
> It's a small task whose result is an input to something else - ideal for a tool for LLM (or script)
Have you actually tried this? If it's a small task then why can't LLMs actually do it? Kind of like the pelican test. Every LLM can do a SVG pelican but most of the results are unusable in practice for production/productivity purposes.
Every LLm can extract some half-broken SVG hallucination of your jots, but I'm asking for an app that's polished and works accurately 99% of the time, which means a dedicated app/model tuned specifically for this task, and nobody makes this yet.
TeMPOraL 3 days ago | parent
I don't feel like I'm a representative sample of general userbase, so I won't dispute this too hard. For me, it's rare but it does happen. Still, 90% of my mobile experience is "how is this so broken, why is it missing the obvious follow-up feature that completes a workflow, and why, again, am I not using a laptop for this?".
> If it's a small task then why can't LLMs actually do it?
What if they actually can?
This is exactly what Karpathy was talking about the other day[0]. If your only LLM experience is the default chat app in chat mode, then this doesn't make sense. If your experience includes using agentic harness like Claude Code/Cowork / Codex/ChatGPT Work, then it's obvious.
The LLM app in "chat mode" will just zero-shot you a pelican, or digitize your notes into SVG, and maybe improve on it a bit if you complain about the result. The same app[1] in "agentic mode" will digitize your notes, refine the SVG against the original image, reduce it to probable strokes based on high-frequency patterns in the photo and knowledge of how people write, OCR it, save both the text and SVG to your library, then extract parts you wanted and insert them into a document, typeset the rest of it, and print it on your printer - all in response to a single prompt.
LLMs in agentic mode are very good at stringing long and advanced workflows; today, if you give them shell access or computer use, they will use regular apps for you if that's the easiest way to accomplish the goal.
> Have you actually tried this?
Yes![2].
That's why I can confidently say: there is no limit to this pattern. LLMs can handle apps just fine; giving them tools just saves time and tokens.
Another example: I'm currently resurrecting a 30 year old game, and the other day I asked Claude to hack on a way to run it headlessly, so I can use my computer while it plays with it. It did, and then immediately leveraged it to just causally run several instances of the game in parallel, entirely in the background, whenever it needed to playtest something.
--
[0] - https://news.ycombinator.com/item?id=50047422 - was on the frontpage two days ago.
[1] - Claude and ChatGPT now have both modes in their mobile, web and desktop apps. I personally use Claude Code a lot, but exclusively through these surfaces (I can't be arsed to deal with TUI at home anymore). IMO, these tools are already within reach of regular users - the users just didn't notice it yet.
[2] - Not with SVGs, but equivalent with voice recordings, and yes, Claude Code set up and is managing the whole local processing pipeline. Recordings go in, Markdown (or more advanced signal processing) comes out, and in itself, it's not a task, but merely a step.
matsemann 3 days ago | parent
TeMPOraL 3 days ago | parent
matsemann 3 days ago | parent
One fictional example of what I mean: lets say I draw someone holding a purse. That would be a shape of their torso, with the purse overlaid. I could move those independently, and moving the purse would show the torso underneath.
However, using a png to svg, it would often just outline everything. So it's not a torso shape with a purse in front. It's a purse with a torso cut out around it, maybe even merged together as lots of individual shapes. If I were to delete the shapes making up the purse, it could be quite random what was left. Maybe some of the shapes did a double duty. Maybe it's a thousand small squares to make the purse. Maybe there is just a hole behind the purse etc.
So in the latter case, the svg isn't made up of logical elements, it's just made up of shape after shape after shape to mimic the pixels. But it's not usable as vector.
xnx 3 days ago | parent
matsemann 3 days ago | parent
CuriouslyC 3 days ago | parent
slyrus 3 days ago | parent
sulam 3 days ago | parent
afavour 3 days ago | parent
gcanyon 3 days ago | parent
They look remarkably good, sure -- but not perfect.
orbital-decay 3 days ago | parent
nomel 3 days ago | parent
orbital-decay 3 days ago | parent
nomel 3 days ago | parent
> That's the result of training on the same datasets and scraped web contaminated with other models' outputs
Maybe I'm misinterpreting though, or just semantics. I would consider contamination, or whatever the first example was that they all matched, as specific training data, along with all the duplications of. I doubt it's model collapse to the same pelican, without the same original example.
orbital-decay 3 days ago | parent
pwython 3 days ago | parent
> How many pelican riding bicycle SVGs were there before this test existed? What if the training data is being polluted with all these wonky results...
But Simon has demonstrated before that asking for any animal doing something silly will still get similar results from the same model.
simonw 3 days ago | parent
thinkingemote 3 days ago | parent
simonw 3 days ago | parent
dominotw 3 days ago | parent
JoshTriplett 3 days ago | parent
mlmonkey 3 days ago | parent
Expect Google models to be benchmaxxed as much as possible, but don't expect commensurate performance on real-world tasks.
anthonyrstevens 3 days ago | parent
This is not true. It is needless negative hyperbole that IMHO doesn't belong on HN.
mlmonkey 3 days ago | parent
agar 3 days ago | parent
If what you say is true, then the next set of benchmarks will be written to illuminate the true reflection of real-world tasks. Then those get benchmaxxed so managers can show "numbers go up."
Repeat enough times, and you get materially and genuinely improved products.
The burden is on the press, outside researchers, and general tech industry to both write and care about the metrics that matter.
solatic 3 days ago | parent
In large companies (Fortune 1000 etc.), you don't have much of a choice, the culture was eroded long ago, and corporate governance by metrics is a lesser of evils. But thankfully, not all companies are there yet.
kalcode 3 days ago | parent
bilsbie 3 days ago | parent
Modern models can make nearly photorealistic games in threejs. So why do they struggle with these pelicans?
simonw 3 days ago | parent
The test is always going to be hard though, because it's an absurd image to ask for.
UPDATE: I like this theory about using an agentic harness that can render and iterate better: https://news.ycombinator.com/item?id=50073879#50074395
boo_you 3 days ago | parent
this is a really profound insight
jephs 3 days ago | parent
The pretty 3d stuff you see are agents controlling a Blender MCP in a loop where they look at the scene, think, adjust the scene, repeat.
simonw 3 days ago | parent
vineyardmike 3 days ago | parent
AspireOne 3 days ago | parent
agar 3 days ago | parent
(As I said in a separate comment above, results are all bikini-clad and not revealing. However, whether it is NSFW is up to you/your work policies.)
Perz1val 3 days ago | parent
sobiolite 3 days ago | parent
TeMPOraL 3 days ago | parent
charcircuit 3 days ago | parent
duckmysick 3 days ago | parent
https://www.gianlucagimini.it/portfolio-item/velocipedia/
HN discussion: https://news.ycombinator.com/item?id=17699017
mason55 3 days ago | parent
https://www.wired.com/2016/04/can-draw-bikes-memory-definite...
ben_w 3 days ago | parent
Are you sure they're not fetching free asset packs for that?
simonw 3 days ago | parent
I even built an environment that allows execution of Python code to render with Blender but allows no other interactions (including networking, I sandbox that off). They can create good 3D models just fine - here's a Faberge Egg by Gemini 4 Argon: https://tools.simonwillison.net/blender-viewer?url=https%3A%...
ben_w 3 days ago | parent
Thanks for doing all this research!
agar 3 days ago | parent
However, result quality really drops off once you get out of the top 5 or so.
(NSFW note: all buttocks are covered by fairly conservative bikini bottoms and show no genitals, bulges, etc.)
postalcoder 3 days ago | parent
kart23 3 days ago | parent
squidbeak 3 days ago | parent
huseyinkeles 3 days ago | parent
MrAssisted 3 days ago | parent
Fraterkes 3 days ago | parent
perardi 3 days ago | parent
Subtle highlights on the metal frame, sweat beads, jaunty little hat…it has style. At least compared to the rather literal ChatGPT outputs. https://static.simonwillison.net/static/2026/gpt-pelicans-gr...
jameshart 3 days ago | parent
Is the prompt context telling the models what their effort level is, and the ambient presence of that concept of ‘high effort’ in the context window is leaking through and affecting the portrayal?
simonw 3 days ago | parent
https://huggingface.co/Qwen/Qwen3.8-27B/blob/main/chat_templ...
xhigh: "Reasoning effort is set to xhigh. Please think carefully through the task, validate key assumptions, consider plausible alternatives, and prioritize correctness, consistency, and clarity in the final answer."
low: "Reasoning effort is set to low. Keep your thinking brief and focused, moving directly to the conclusion without unnecessary elaboration."
LarsDu88 3 days ago | parent
It's a simple manner of prompt...generate concept art with nanobanana, measure, llm creates svg with text, measure the distance between rasterized svg embedding to nanobanana art....do post-training RL on a 3 million such images and matching embeddings.
I swear this will be a canonical example of Goodhardt's Law in action.
You have to switch to a new benchmark that isn't so easy to run a verifiable rewards pipeline on...Perhaps a longer horizon task where it's easy to mess up midway.
jameshart 3 days ago | parent
Yes, Simon has made pelicans a benchmark and now models have grown very good at rendering them. Is there a reason to believe that this isn’t manifesting as useful skill in general in SVG generation?
wasfgwp 3 days ago | parent
It would perhaps be slightly interesting if the prompt was run 100 times for each model. I doubt the pelicans would look identical.
yuhmahp 3 days ago | parent
simonw 3 days ago | parent
Here's 'Generate an SVG of an armadillo in fishnet tights jaywalking on Mars' for Gemini 4 Argon: https://tools.simonwillison.net/markdown-svg-renderer?url=ht...
Some other models for comparison: https://tools.simonwillison.net/markdown-svg-renderer?url=ht...
solatic 3 days ago | parent
1. the pedestrian traffic light's hand and "wait, citizen" text are not inside the light itself
2. The armadillo's nose is outside of the astronaut helmet
Isn't that just proof that the pelican has been benchmaxxed?
make3 3 days ago | parent
dyauspitr 3 days ago | parent
gcanyon 3 days ago | parent
As one point, the high pelican's arm is see-through/messed up.
They do look worlds better than previously, to be fair.
YZF 3 days ago | parent
https://en.wikipedia.org/wiki/Pelican#/media/File:Pelikan_Wa...

ASalazarMX 3 days ago | parent
ameliaquining 3 days ago | parent
matt123456789 3 days ago | parent
diseasedyak 3 days ago | parent
geniium 3 days ago | parent
mroset 3 days ago | parent
gordon_freeman 3 days ago | parent
bigcat12345678 3 days ago | parent
mt_ 3 days ago | parent
travbrack 3 days ago | parent
tintor 3 days ago | parent
epihelix 3 days ago | parent
However, how the front fork rake affect stability is I believe a little complex. I doubt this old article is the last word on the subject, but it's a great read nonetheless, and note especially the ultra-stability of the reversed fork bike!
https://physicstoday.aip.org/features/from-the-archives-the-...
rich_sasha 3 days ago | parent
I note that even these bikes are not actually rideable. For a bike to be stable, the front wheel axle needs to extend forward a little ahead of the fork - the fork must ”bend forwards”. This is what actually keeps the bike upright, not gyroscopic effects or some such. Given LLMs are generally good at basic maths, im surprised they get this wrong.
Maybe a bit less so in this case though. As per the announcements, the model was actually trained for this prompt, so was fed some training data. I can well imagine the data there was just not so good.
jonas21 3 days ago | parent
https://www.walmart.com/ip/Huffy-26-inch-Rock-Creek-Men-s-Mo...
(apologies if I'm misunderstanding).
sokka_h2otribe 3 days ago | parent
matsemann 3 days ago | parent
Whether having zero offset or not isn't what matter in the end, but the trail. And you can achieve that with little offset as long as the fork is angled.
(so the grandparent is a bit right in their critique, but not for the reason stated)
matsemann 3 days ago | parent
People drawing bikes, scroll down to see they having made renders of all the drawings. Hilarious
saberience 3 days ago | parent
You're nit-picking on a detail no one actually cares about.
kevmo314 3 days ago | parent
You can also ride a negative rake fork. They are less stable, yes, but a far cry from not actually rideable, cf https://www.instagram.com/yourforkisonbackwards/
Enginerrrd 3 days ago | parent
Bedon292 3 days ago | parent
I'll also note that, using a piece of paper as a straight edge against my screen, there is a very slight forward curve on the low and a bit more on the high responses. Medium does appear to be perfectly straight.
matsemann 3 days ago | parent
But even with zero offset, there is another thing in play. The steering axis is at an angle, a fork never points straight down. So even with zero offset, you still get a trail, which is the difference between the contact point of the wheel at the ground, and where the steering axis meets the ground. This trail is really what matters in the end, not how you get there.
See https://en.wikipedia.org/wiki/Bicycle_and_motorcycle_geometr...
But even better, play with (ctrl+f) "trail" in this simulation: https://ciechanow.ski/bicycle/
There you see the point. Even with zero offset, there is still a trail.
adwn 3 days ago | parent
1. Modeling and analyzing spinning, three-dimensional objects goes far beyond "basic maths".
2. The prompt was for an SVG of a realistically impossible situation (pelican riding a bicycle), which together already implies a stylized depiction. Why on Earth would you expect it to generate a 3D model of a bike, do a physics simulation on it, iterate until it satisfies certain contraints which are only hinted at in the prompt, and then project it down to a simplified 2D cartoon drawing? That's not how LLMs work, and that's not how we want them to work.
NooneAtAll3 3 days ago | parent
wasn't the whole point of pelicans is that labs *wouldn't* train for that?
so now the benchmark is ruined
motoboi 3 days ago | parent
Also, that first tweet contains a commentary that, for me, explain a lot about the public misconception about how current AI works:
> wait, does this mean you guys are actively training svg generation? i was mostly amazed by it thinking the models doing better at it by itself due to becoming better at reasoning.
No, it's not better reasoning that drives current AI, it's better examples we have been giving them. Whole army of people generating content for the frontier labs.
Also, reasoning improving the out of distribution part, like computer use, tool use etc.
TeMPOraL 3 days ago | parent
Another case where allowing oneself to anthropomorphise LLMs a little yields better intuitions.
People don't get more skilled by raw reasoning, either. They improve their skills with better textbooks (pre-training data), more practice exercises (RL data), and generally goofing around (self-play).
boutell 3 days ago | parent
w29UiIm2Xz 3 days ago | parent
KeplerBoy 3 days ago | parent
kmod 3 days ago | parent
<https://tools.simonwillison.net/svg-render#%3Csvg%20font-fam...> <https://tools.simonwillison.net/svg-render#%3Csvg%20font-fam...>
- I was having trouble embedding the SVGs as links, and ChatGPT recommended Simon Willison's SVG Renderer as a workaround.
Just my 2 cents on the pelicans benchmark: I think it might help if you were a bit more explicit about not taking this one benchmark too seriously. I know you say that at times, but at other times (such as the comment I'm replying to) you elide it which can read as a seriousness about the benchmark.
thefourthchime 3 days ago | parent
Argon: https://jonclegg.github.io/pacman-bakeoff/dev/#gemini-4-argo...
Opus 5.5 https://jonclegg.github.io/pacman-bakeoff/dev/#claude-opus-5...
vessenes 3 days ago | parent
fipar 3 days ago | parent
This is the sheet: https://fernandoipar.com/content/music/poly-d/gemini-argon/c... (the annotations on it are by me)
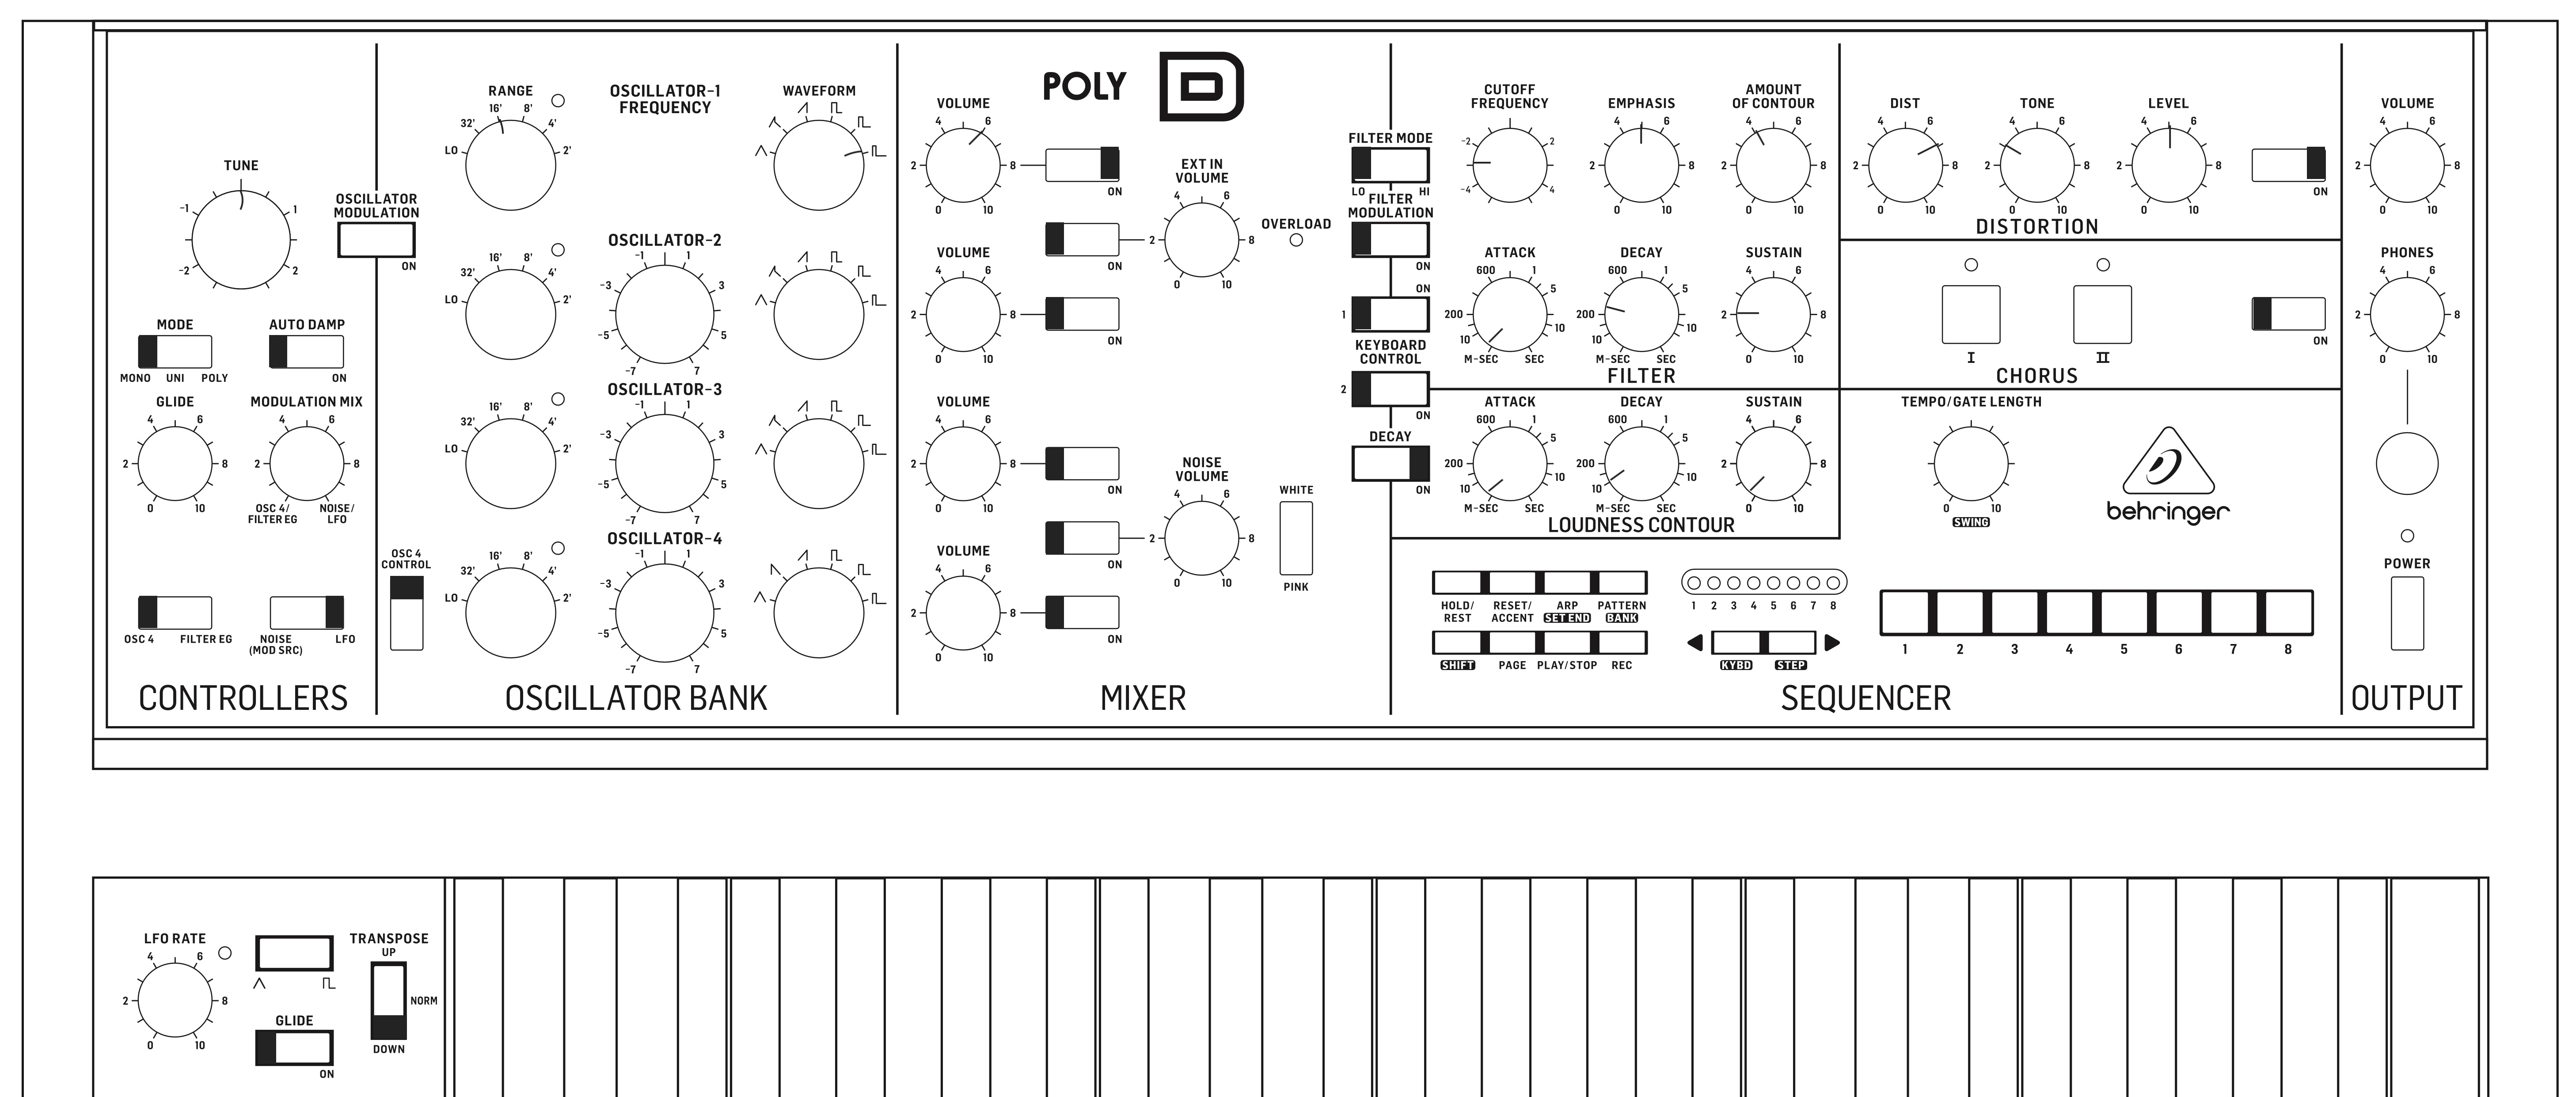
And this is what Argon created: https://fernandoipar.com/content/music/poly-d/gemini-argon/b...
For this simple prompt: https://fernandoipar.com/content/music/poly-d/gemini-argon/p...
I'm honestly impressed.
dekhn 2 days ago | parent
osiris970 3 days ago | parent
What’s the point lol. I’m not subbing to ultra to have it
rcr-anti 3 days ago | parent
Edit: noble gases not noble taxes, though the latter would be a funnier naming scheme.
mistic92 3 days ago | parent
robotmay 3 days ago | parent
skerit 3 days ago | parent
robotmay 3 days ago | parent
metalliqaz 3 days ago | parent
olafura 3 days ago | parent
Which is even weirder given that the api costs are less than for the other providers
Maybe they don't really care about antigravity users. Also, monitoring usage is horrible.
kaszanka 3 days ago | parent
Trusteando 3 days ago | parent
yoz-y 3 days ago | parent
freakynit 3 days ago | parent
This is crazy if it can work accurately.
ArashEdalat 3 days ago | parent
verdverm 3 days ago | parent
129751 3 days ago | parent
Even after using the free model in Google search talking to Anthropic or OpenAI models feels like talking to an ox.
Christine725 3 days ago | parent
david-gpu 3 days ago | parent
Havoc 3 days ago | parent
God knows why the server different things to the same people on different interfaces
pietz 3 days ago | parent
swaptr 3 days ago | parent
chaostheory 3 days ago | parent
sureglymop 3 days ago | parent
Pretty misleading.
tireonfire 3 days ago | parent
jazdw 3 days ago | parent
JacobAsmuth 3 days ago | parent
lp92 3 days ago | parent
protoman3000 3 days ago | parent
The code is bad though.
jug 3 days ago | parent
TomGarden 3 days ago | parent
anon373839 3 days ago | parent
gradus_ad 3 days ago | parent
mavamaarten 3 days ago | parent
copperx 3 days ago | parent
bahmboo 3 days ago | parent
yipinwong 3 days ago | parent
Or else it say, here is the result. (but no it didn't do no research, and tells me, sorry I forgot to search).
It's got balls to lie straight at my face.
SwellJoe 3 days ago | parent
They all ramble, they're all allergic to getting to the point. But, Gemini historically has pretty good prose. Even the self-hosted Gemma models have pretty nice, inoffensive prose. I wouldn't want to read a novel written by any of them, but I tend to ask Gemini questions in chat more often than Claude or GPT, because it has good prose and is good at using the web to research.
thisisauserid 3 days ago | parent
meerita 3 days ago | parent
ckx 3 days ago | parent
d2kx 3 days ago | parent
babelfish 3 days ago | parent
d2kx 3 days ago | parent
mattmanser 3 days ago | parent
Eyes glazed over again.
Did you even read your own site before you posted it?
One of the first pages I opened:
> Smoking-gun proof of plant-label ingestion: in Row 2, the central cut root is labeled okol (f88r.15), and directly underneath it on Line 2 (f88r.19) the recipe writes...chokol daiin qoekol qoekol qockhol okol cheol...!
It's just gibberish.
swingboy 3 days ago | parent
mattmanser 3 days ago | parent
It only makes sense in a wider Claude session, and even then it's like he's got Claude set to super-boot licker mode.
shawabawa3 3 days ago | parent
It looks like you've managed to decode it? Is that legit?
yipinwong 3 days ago | parent
What kind of progress was made with Argon with the Voynich?
jdthedisciple 3 days ago | parent
kzrdude 3 days ago | parent
But id the progress of decoding it is legit, you should write something properly about it!
scotty79 3 days ago | parent
simonw 3 days ago | parent
But on December 1st Argon doubles in price - so it will be the same price as Opus 5.5.
mdasen 3 days ago | parent
Likewise, you look at Artificial Analysis' general index and it cost $8,708 to run with Opus and $2,407 to run with Argon so even if Argon's token price doubles, it won't be the same price as Opus.
Sonnet is cheaper than Opus per-token, but in their coding tests Sonnet burns through enough tokens that it's 7.5% more expensive.
So much depends on how token efficient something is and whether it gets you a good result or not, right?
Plus, if one is using a plan instead of paying token rates, what does my $200 get me from OpenAI, Anthropic, or Google?
It just feels very hard to compare pricing given that the number of tokens used can vary so much. In Artificial Analysis' coding tests, Sonnet used 7.1x more tokens than Sol. Sonnet and Sol might have the same per-token pricing, but there's a huge difference in the number of tokens used.
simonw 3 days ago | parent
This was hardly a consideration a year ago, when many model tasks could be tested using a single prompt and it was hard to spend more than a dollar.
isityettime 3 days ago | parent
Me: Gemini, navigate to nearest McDonalds.
Gemini: [Lists 10 McDonalds locations wnd asks which I want.]
Me: What were the priginal instructions just now?
Gemini: [Recites imperatives about tone and content from its memory system.]
Me: No. I told you to navigate to the NEAREST McDonalds. There's only one NEAREST McDonalds. Do that one.
Gemini: My mistake, navigating to the nearest McDonalds. [Opens Maps, navigating to a McDonalds across town.]
didibus 3 days ago | parent
kingstnap 3 days ago | parent
Flash lite is very noticeably more idiotic than 3.8 Flash. It's why the quick AI overview is often much worse than the AI mode one.
elxr 3 days ago | parent
I also have had shockingly bad results with gemini on android. Ended up giving up on it after a few months. Silly silly google with their trademark UX polish and attention to usability.
Capricorn2481 3 days ago | parent
isityettime 3 days ago | parent
Capricorn2481 3 days ago | parent
desterothx 3 days ago | parent
isityettime 2 days ago | parent
Capricorn2481 2 days ago | parent
moffkalast 3 days ago | parent
jabroni_salad 3 days ago | parent
jeffbee 3 days ago | parent
dyauspitr 3 days ago | parent
compiler-guy 3 days ago | parent
The only thing I can figure is that Google's consumer-facing free-to-use models are set to "reason as fast as possible with only the most basic plausibility checks." I have to correct them like this every single time.
sm-silversight 3 days ago | parent
bornfreddy 3 days ago | parent
compiler-guy 3 days ago | parent
isityettime 3 days ago | parent
Similarly, you can run local LLMs on your Google Pixel smartphone, but if you want them to be hardware accelerated using the chip that's included for that very purpose on your phone... it has to be Google's models via Google's apps. So you can't say "alright, a fast, local model which sounds great, but I want one that is trained to always run a search before answering, in a harness with good search tools for answering the kinds of practical questions I often ask", you're actually not free to put that together in a practicable way.
So there is indeed some competition here. But it's not really fair competition.
staticman2 3 days ago | parent
isityettime 3 days ago | parent
LewisOrton 3 days ago | parent
LewisOrton 3 days ago | parent
i benchmarked 20+ models in real worlds and gemini families are the best (highest customer satisfaction)
foota 3 days ago | parent
polynomial 3 days ago | parent
ASalazarMX 3 days ago | parent
gorbot 3 days ago | parent
I think these companies have good models but expose them poorly like others have mentioned
RajuChacha108 3 days ago | parent
I tell it to "Play Let it go from frozen". It plays it on youtube music. 5 seconds later I tell it again 'Play let it go from frozen" it then just dies saying "I can't play videos in car".
dgunay 3 days ago | parent
1. I ask it to list out all my old Keep notes that are just throwaway task lists, reminders, etc. to propose deleting them.
2. It comes up with like 4 of them (I know for a fact there are dozens, if not hundreds). I ask it for an exhaustive list.
3. I see its thinking trace briefly show "Refusing to produce an exhaustive list..." and then it says "Yes, that is all of them."
Not sure whether it's lack of intelligence, bad tools, or both, but that was extremely frustrating to see.
sva_ 3 days ago | parent
If it had exact location access people would be crying that Gemini steals their location data.
isityettime 3 days ago | parent
eluusive 3 days ago | parent
I have found that Gemini often claims it did something, but didn't actually complete the task.
I just had 3.8 Flash do a major refactor -- that never should have needed to be done in the first place -- and switched to Argon 4, and had it review it.
Almost everything had been stubbed out by 3.8, and none of it was properly integrated into the codebase. :facepalm:
karahime 3 days ago | parent
anonova 3 days ago | parent
karahime 3 days ago | parent
> Upcoming change to OpenRouter’s ZDR designation for Google authored models
> We’re writing to let you know about an upcoming change to how OpenRouter designates Google authored models for Zero Data Retention (ZDR) routing.
> Effective October 18, 2026, OpenRouter will no longer designate Google authored models as ZDR-eligible. After that date, requests that require ZDR will not route to Google authored models.
> Google’s standard automated abuse-prevention policies allow it to use safety classifiers to identify requests that may violate its policies and to securely retain prompts flagged for further review. Because this process does not meet OpenRouter’s requirements for a ZDR designation, we are updating our model classifications and routing controls accordingly.
> What this means for you If your requests require ZDR We recommend migrating affected traffic to another ZDR-eligible model before October 18, 2026 to avoid interruption.
> If you do not require ZDR No action is required for your Google model requests.
> Our current routing behavior will remain unchanged during the 30-day transition period ending October 18, 2026. > Read the ZDR documentation
> If you have questions or would like help identifying an alternative model, please contact us at support@openrouter.ai.
> Thanks for using OpenRouter!
> The OpenRouter Team
staticman2 3 days ago | parent
jdw64 3 days ago | parent
robotmay 3 days ago | parent
dmix 3 days ago | parent
Every time I try to generate one it's like a slot machine, where a different part will be messed up after fixing the first.
TomGarden 3 days ago | parent
ramoz 3 days ago | parent
DrProtic 3 days ago | parent
I told it to strip screenshots from our old basic explainer video to generate modern 3D video.
Pretty happy with the result. I told it to keep the audio and match the video and it did.
dmix 3 days ago | parent
I previously tried with Seedance 2.5, Flux 3, Kling 3, Gemini Omni without much luck.
ChrisClark 3 days ago | parent
sixdimensional 3 days ago | parent
jjcm 3 days ago | parent
Argon build: https://html.non.io/lcars-argon/
GPT 6.1 sol: https://html.non.io/lcars-gpt-6.1-sol/
Opus 5.5 (currently SOTA for this): https://html.non.io/lcars-opus-5.5/
Original designs: https://diffui.ai/app/canvas/5093e689-1e74-4f26-b632-2a4500f...
jjcm 3 days ago | parent

jadbox 3 days ago | parent
sergiotapia 3 days ago | parent
jjcm 3 days ago | parent
capnjngl 3 days ago | parent
bobviolier 3 days ago | parent
(Chrome, also incognito)
MaxikCZ 3 days ago | parent
jjcm 3 days ago | parent
FWIW, I have literally the exact same configuration (M3 air, google chrome). Here's a recording on mine where I'm seeing 60fps: https://non.io/video/video-3587018401.mp4
Gallows4574 3 days ago | parent
Edit: The argon built site pins 1.3 cpu cores. The Sol 6.1 site uses 0.18 cores.
dr_kiszonka 3 days ago | parent
niek_pas 3 days ago | parent
wireless6948 3 days ago | parent
daemonologist 3 days ago | parent
jjcm 3 days ago | parent

As soon as gpu acceleration is disabled, the webpage goes from 60fps across the three systems I tried to ~7-20fps when software rendering is forced.
I suspect if you go to chrome://gpu you'll find something different from what I have here: https://image.non.io/a47a1b03-1b87-4fd5-92a2-b39e62b1cfd9.we...

bobviolier 3 days ago | parent
So that all being said, a normal website should work totally fine on low power mode, and this should definitely be a negative on the Opus implementation.
jjcm 3 days ago | parent
I would disagree with this based on two things:
1. the prompt, which explicitly states to render the planets in the background in 3js (thus the gpu implementation).
2. the purpose of this, which is a test of its ability to convert an image design into a html/js/css implementation that matches it as closely as possible. I've talked about this before when it's come up[†]. The purpose is to be a good test, not a good design or website.
For reference, here's the full prompt used:
> Create a web page implementation from the following instructions: https://diffui.ai/build/Futuristic_Interior_UI_build.md?auth... dont reference any other folders that have similar builds. Focus on the flowing SVGs. Animate elements that make sense to be animated. For the starships that have planets in the background, ask for high quality images with the windows as a transparent background, and recreate the planets behind them in 3js. It should be one single page application that I can just open the index.html file to view.
[†] https://news.ycombinator.com/item?id=49997135
[‡] here's a copy of this since the diffui build instructions wont be accessible without an account: https://non.io/lcars-build-instructions
piperswe 2 days ago | parent
awkwardpotato 3 days ago | parent
jjcm 3 days ago | parent
Here's a vid of both opus and argon side by side, which might be more viewable on mobile: https://x.com/pwnies/status/2110058987462988152
jdthedisciple 3 days ago | parent
demibabs 3 days ago | parent
vessenes 3 days ago | parent
Panzer04 3 days ago | parent
jbrooks84 3 days ago | parent
jjcm 3 days ago | parent
IE for Argon, the third section doesn't have a top view of the ship with labels going to each section like what's in the design. Opus has it, and animated it as well. One failed to do as instructed, the other went an extra mile.
danpalmer 3 days ago | parent
jatins 3 days ago | parent
derac 3 days ago | parent
civvv 3 days ago | parent
lxgr 3 days ago | parent
Gemini Live vs. Gemini Lite vs. Gemini Pro vs. Gemini Flash vs. Nano Banana Lite (that one apparently has no Gemini prefix?)... Please, just pick a metaphor and stick with it without wildly mixing reasoning modes, model sizes, and input/output modalities in the model name!
tonyhart7 3 days ago | parent
jawiggins 3 days ago | parent
I wonder if any of the AI safety people will begin encouraging AI researchers to swap jobs to work at a failing lab in order to keep them all extremely competitive with one another.
FinnLobsien 3 days ago | parent
At this point a lot of stuff happens at the product level.
OpenAI and anthropic have distribution and data advantages now that are hard to replicate.
jawiggins 3 days ago | parent
reasonableklout 3 days ago | parent
Trusteando 3 days ago | parent
dyauspitr 3 days ago | parent
mridulmalpani 3 days ago | parent
https://arena.ai/leaderboard/agent/chat/pareto
For almost same intelligence (+15.56%, +15.18%), drastic difference in cost/task ($3.51 vs $0.41)
BrokenCogs 3 days ago | parent
yipinwong 3 days ago | parent
abeppu 3 days ago | parent
ianm218 3 days ago | parent
jonas21 3 days ago | parent
seizethecheese 3 days ago | parent
cloudbonsai 3 days ago | parent
seizethecheese 3 days ago | parent
tibbar 3 days ago | parent
wordpad 3 days ago | parent
dfdydx 3 days ago | parent
casey2 3 days ago | parent
From the graph it's a flat line, but looking at the point yields a negligible increase with no error bars (indeed if you look at fable 5.1 it's measured as lower than opus and argon). This just seems like bad data or blatant favoritism at worse.
serioussecurity 2 days ago | parent
scotty79 3 days ago | parent
vessenes 3 days ago | parent
cheema33 3 days ago | parent
For chat, yes. But switch to code on the same page, and the picture changes. OpenAI takes the lead.
Silagi 3 days ago | parent
cwoolfe 3 days ago | parent
npn 3 days ago | parent
It still thinks Charlie Kirk is alive, though.
peter_d_sherman 3 days ago | parent
Now that needed to be done for some time!
Regardless of if an AI helped or not, regardless of whether that was Google's or some other AI or not (though Argon does sound pretty cool!), regardless of whether an AI cut the time from months to weeks or not, refactoring Chrome -- decomposing it into individual clearly demarcated non-tightly coupled software parts with core webpage handling at the center -- that needed to be done for some time!
Now all of that being said, Gemini 4 Argon does sound pretty cool, and we congratulate both teams at Google -- the team that created Gemini 4 Argon, and the team that refactored Chrome with it!
But all of that being said, while the advancements made for Gemini 4 Argon are important and impressive (and they are!)... refactoring Chrome properly (IMHO) is slightly more important and impressive!
(You know, one man's humble opinion! That is, I am not the guy who is responsible for awarding performance-based bonuses at Google at the end of the year, so take everything I say with the proverbial "grain of salt"! :-) I am probably biased, one way or the other! :-) )
efficax 3 days ago | parent
mchusma 3 days ago | parent
ketzu 3 days ago | parent
Okay, so I'll get Pro to try it.
I subscribe.
No gemini 4.
The most generous reading I have is that it's a mistake. But I also downloaded the PC app, and now I really wonder why I did that, it seems to offer nothing beyond the web experience and also doesn't even know its a local app. (When asked about its capabilities it always responded with reasons pertaining to it being a web app.)
lp92 3 days ago | parent
ketzu 2 days ago | parent
However, my experience with the gemini, jules and antigravity apps was awful. So it is difficult to pin that on the model.
I wanted it to give me a proper comparisson for VPSes or server options and it took so much babysitting and it couldn't produce reliable pricing information or visulalisations.
llm_nerd 3 days ago | parent
EDIT: Okay, the AI plans page claims under pro - "Expanded access to Gemini 4 Argon in Google Antigravity." So maybe it is just a matter of it rolling out. Though Google has a long history of serious confusing and misinformation on those tier descriptions.
EDIT2: And they changed it again, and now it is explicitly excluded from antigravity for Pro users.
richrichardsson 3 days ago | parent
I'm not going to 5.5x my subscription cost without being able to try it out first. To be fair though, I'm not going to 5.5x my subscription cost anyway, as my current usage would not warrant that! But that doesn't change the validity of my prior point.
dcchambers 3 days ago | parent
Google...why. You keep getting so close but constantly fumble at the last moment. I can use Opus 5.5 and Sol/Astra on the $20 Anthropic and OpenAI plans.
You are already playing from behind. You need to GET YOUR MODELS INTO MORE PEOPLES HANDS by any means possible. Continuing to make it difficult to use your products DOES NOT HELP.
This model might be great but the majority aren't going to subscribe for $100/month just to try it.
WaltPurvis 3 days ago | parent
dcchambers 3 days ago | parent
Kuyawa 3 days ago | parent
Which one is it?
brainwad 3 days ago | parent
Zigurd 3 days ago | parent
qlte 2 days ago | parent
a11r 3 days ago | parent
bionhoward 3 days ago | parent
It feels so complicated and hard to know what we can use vs what hands them our codebases
SXX 3 days ago | parent
Start preparing Gemma 5 release.
Macuyiko 3 days ago | parent
koyote 3 days ago | parent
Since then they cut the price but the intelligence (of 6 and 6.1) has gone down to Sonnet 4 levels. I am back in a world where the model is lazy, cuts corners, ignores existing coding standards and context, makes stupid mistakes etc.
I am not sure how those models still rank so high in benchmarks when real-life usage is so obviously bad.
scrollop 3 days ago | parent
https://www.bridgebench.ai/nerf-bench
https://marginlab.ai/trackers/claude-code/ https://marginlab.ai/trackers/codex/
eyalitki 3 days ago | parent
arjie 3 days ago | parent
amai 3 days ago | parent
dandaka 3 days ago | parent
deniska 3 days ago | parent
karp773 3 days ago | parent
l0kihardt 3 days ago | parent
grim_io 3 days ago | parent
Related funny https://www.youtube.com/watch?v=DlTNN0gvkLM
Andrex 3 days ago | parent
I_am_tiberius 3 days ago | parent
the_real_cher 3 days ago | parent
Lucasoato 3 days ago | parent
_s_a_m_ 3 days ago | parent
They had gemini cli, what happened to that? Was fine
Lucasoato 3 days ago | parent
Is there anybody in Google having a look at how bad and complicated their payment system is? In all the other AI providers you just sign in, pay, get a key, done. In other clouds like AWS, you add a card, pay little to verify the card the first time, monthly bill, done. In Google it looks like you have to fight them every time for the very thing they should make as easy as possible: opening your wallet.
dynm 3 days ago | parent
deno 3 days ago | parent
I would also advise against buying Gemini if you have any other Google services, because you get banned across board if they don't like something. To use Google it's best to first migrate off of Google.
Otherwise great product, I really like and would recommend Gemini. The usage is also very generous, at least Flash models.
serbuvlad 3 days ago | parent
I recently had to verify my YouTube account with a phone number recently because it requires this in order to set a thumbnail.
Questions right off the bat:
1. Why do I need to verify to post a thumbnail that will take 1MB on their servers but not to post a video that will take 100MB on their servers and be public??
2. Why do I need to verify my phone number on YouTube when it's linked to my Google account which has a verified phone number and 2FA etc.?
In any case, it takes you to a CSS-less page that asks you to choose between getting an SMS or being called to get a code. I choose SMS and it doesn't work. It shows an error message with no description just "something went wrong". I try a few times and it keeps not working.
I then switch to the call, and guess what! I have tried "too many times" and will have to try again later. Call worked the next day, but geez, what a mess.
singingtoday 3 days ago | parent
algoth1 3 days ago | parent
guybedo 3 days ago | parent
i live in French Polynesia, a French territory, i'm a Google AI subscriber and i can't use Google AI Studio or antigravity cli because i'm in a geo restricted area ...
It seems Google has no issue laying out cables across the Pacific Ocean from/to Tahiti, they don't have an issue selling their services and plans there but i can't use AI Studio or antigravity cli because of geo restrictions ...
bluerooibos 3 days ago | parent
- Try in Gemini
- Try in Google AI Studio
- Try in Google Antigravity
Will non users of Google products even know what these three things even are?
34679 3 days ago | parent
I have AI Pro, but AI Studio tells me I can "unlock" Argon by upgrading to Ultra.
DriverDaily 3 days ago | parent
kccqzy 3 days ago | parent
What you did isn’t wrong, but is unfortunately very similar to what real scammers do. The heuristics behind these anti-abuse efforts are always going to have false positives.
Xenoamorphous 3 days ago | parent
codethief 3 days ago | parent
For the lazy:
https://www.osnews.com/story/19921/Full-Text-an-Epic-Bill-Ga...
steve1977 3 days ago | parent
throwaway919233 3 days ago | parent
kristofferR 3 days ago | parent
Ended up with Soniox instead, took minutes to get started.
0xbadcafebee 3 days ago | parent
mrshadowgoose 3 days ago | parent
They made using it so hard/unclear that myself and every other dev I knew gave up.
It's clear that they still haven't done any organizational self-reflection.
randerson 3 days ago | parent
They now ask for your mobile number during signup. And it wouldn't let me register any more accounts with my number. So frustrating.
mfkp 3 days ago | parent
"Unavailable · Gemini 4 Argon is currently available to Ultra plan subscribers."
talon8635 3 days ago | parent
That said, asking Gemini.google.com to walk you through the steps seems to suffice. In fact, one of AIs big perks for me is walking my through kafkaesque systems like Google’s to cut the shit and get to the result
rumblefrog 3 days ago | parent
radicality 3 days ago | parent
Truly crazy how much Gemini still hallucinates, especially things which its own Google documentation or just a basic web search away. I feel it’s mostly solved problem with chatgpt/claude , but for me, with Gemini it’s almost guaranteed it will just make stuff up
jasondigitized 3 days ago | parent
dieortin 3 days ago | parent
What’s so complicated about going to gemini.google.com ?
> Why isn't it called Gemini Desktop
There is a Gemini desktop app. Antigravity is for agentic stuff, similar to Codex.
tyingq 3 days ago | parent
RGS1811 3 days ago | parent
- Then I realized Gemini 3 was active.
- I tried switching models.
- I was presented with a $99/mo subscription offering.
- I scrolled down and clicked to get cheaper options.
- I chose the $19.99 "AI Pro" monthly option and paid.
- In chat I was able to use Argon. Cool. Seems pretty smart.
- I asked Argon if I could use it through opencode with my Google account.
- Argon said yes, but then told me I'd have to use the Gemini CLI as middleman.
- I told it I didn't know there was a CLI for Gemini; I'd just use that.
- It told me how to install gemini-cli.
- I authenticate via Google OAuth inside gemini-cli.
- Gemini-cli rejects my login, says the app is deprecated for subscription users, who must use agy.
- I install agy.
- In agy, I open the model selection menu.
- "Gemini 4 Argon is currently available to Ultra plan subscribers." Odd... Gemini 4 Argon is the model (included in my Pro plan) that told me to do this.
- I discover that Claude Opus 5.5 is included in the subscription. I switch to it and give it a debugging task.
- Within about 5 minutes: "Individual quota reached. Please upgrade your subscription to increase your limits."
- This is dumb. Google stole twenty bucks from me; I want my money back.
- I go to the Gemini web app to cancel my subscription. I paid on my phone, so I have to cancel on my phone.
- The Gemini iOS app has a "manage my subscription" page. I go there to manage my subscription.
- This "manage my subscription" page includes no way of cancelling.
- After a minute of confusion I go to the App Store > Subscriptions > Gemini > Cancel.
- My subscription will end at the end of the month (no refund).
- Then I have to find the complaint form so I can request a refund.
- But I did request one.
Anyway, "frontier intelligence" just wasted about an hour of my life.
JanTurnherr 3 days ago | parent
for me, a google model can be as good as they want, in the end, they are still google, probably one of the most bureaucracy riddled big companys out there. evrything i see from then gives me feeling that evrything has been decided by a committee that do care more about politics and not customer needs. the shit one has to go trough to get the gemini-cli running is a good example of that.
notatoad 3 days ago | parent
but they don't want to share their compute with us. giving those resources to their ad targeting algos is more profitable than renting them to us. so they make it as hard as possible. they tried as hard as they could not to release a new pro model at all, but now that fight has been lost they at least need to make sure we don't use it.
framapotari 3 days ago | parent
halyconWays 3 days ago | parent
fraywing 3 days ago | parent
tintor 3 days ago | parent
XCSme 3 days ago | parent
minraws 3 days ago | parent
joejohnson 3 days ago | parent
hollowturtle 3 days ago | parent
On safari the page doesn't scroll very well on the first section
dhruvrrp 3 days ago | parent
What about the Google One AI plans? Will they get it? That has a Pro AI plan as well.
kylecazar 3 days ago | parent
fusslo 3 days ago | parent
is it just 'Hire the right people'?
jacquesm 3 days ago | parent
IncreasePosts 3 days ago | parent
Perhaps one of their more successful chat clients, but that's all I can think of
jacquesm 3 days ago | parent
The really annoying ones are the ones they buy, and then shutter because they can't make enough money on them fast enough.
braj0 2 days ago | parent
I thought the nightlight that goes on when you walked under it was really neat...
jacquesm 2 days ago | parent
serioussecurity 3 days ago | parent
It's extremely inconsistent internally as well.
Look up the slime mold analogy for Google.
boelboel 3 days ago | parent
Eridrus 3 days ago | parent
Google did a very good job on things that required longer research times and compute scale, note that Transformers, BERT & Scaling Laws came out of Google (though the latter were also worked on at OpenAI).
Conversely, Google is horrible at product, and without OpenAI, it probably would have taken many years longer to take off. I know this because Google had demos of this internally, but absolutely no stomach to release it, and they didn't believe in the API use case at all.
Which is to say, I think if Google was smaller, we probably would have gotten more SaaS, not more breakthrough research.
no_carrier 3 days ago | parent
Eridrus 3 days ago | parent
ceejayoz 3 days ago | parent
What if the answer is "they don't"?
arjie 3 days ago | parent
estearum 3 days ago | parent
Eridrus 3 days ago | parent
It's also worth noting, Gemini 3.5 Pro never came out.
Having worked there (but only in a small part of it that eventually got absorbed into Gemini), it's some combination of:
* The eye of Sauron (management) can make specific spots (e.g. Gemini) push harder (and attract the motivated people at the company and be selective)
* They hire a lot better than average (Generally from the top 10%, hotter places in Google are more selective)
* They have a promo process that gives career motivated people a way to prove themselves (not always aligned with things being on the right track ofc, and not always non-political, but they definitely do something)
* Redundancy in teams causes them to compete (not necessarily productively)
Of course, there are other downsides not listed here (insane bureaucracy for launches, GDPR/BCID compliance, etc, etc), but a lot of what makes Google possible is the insane amounts of cash Search throws off.
ur-whale 2 days ago | parent
They don't.
If they did, neither OpenAI nor Anthropic would even exist, as the core of what they're all doing was invented by Google engineers and researchers.
hmokiguess 3 days ago | parent
astlouis44 3 days ago | parent
sva_ 3 days ago | parent
ariwilson 3 days ago | parent
It thinks a ton, ~24k output tokens a run vs ~3k for Sonnet. It missed a solution by thinking its way into a 10 min timeoout.
Something to look out for - if you're using pi, it doesn't have Argon in its catalog yet and reports cost at Kimi's rates, about a third of what OpenRouter actually bills.
millaker 1 day ago | parent
iharnoor 3 days ago | parent
FranciscoCarlos 3 days ago | parent
As of my knowledge cutoff, three of the top state-of-the-art large language models are Google's Gemini 2.5 Pro, OpenAI's o3 (and GPT-4.5), and Anthropic's Claude 3.7 Sonnet.
arbuge 3 days ago | parent
FranciscoCarlos 3 days ago | parent
zobzu 3 days ago | parent
I'm not quite sure what their strategy is, because it looks like the models released just have tweaks on the same original training data, but nothing more. Basically, they decide not to release them and it doesn't seem to be a much different when they finally to decide to release.
FranciscoCarlos 3 days ago | parent
parasti 3 days ago | parent
FranciscoCarlos 3 days ago | parent
akoboldfrying 3 days ago | parent
FranciscoCarlos 3 days ago | parent
piperswe 2 days ago | parent
FranciscoCarlos 2 days ago | parent
bender250 3 days ago | parent
And at least Flash 3.7/3.8 were both difficult to persuade that they have wrong knowledge cutoff.
I reported it as a bug to Google, but as all of my reporting to Google, no response ever. This is just stupid!
FranciscoCarlos 3 days ago | parent
jeffrallen 3 days ago | parent
akbarian 3 days ago | parent
svara 3 days ago | parent
This is a clear step change, I'm genuinely amazed.
Its answers are to-the-point, logically structured, clearly written. Like a really well made mini essay on your question.
It also really likes to build little simulations / models that you can tweak the parameters on. Amazing to explore how different assumptions affect economic scenarios, for example.
It's also great at picking (sourced) illustrations.
I'll be using this for everything that isn't coding from now on.
A_D_E_P_T 3 days ago | parent
artursapek 3 days ago | parent
informal007 3 days ago | parent
Google have strict limits on new model this time and are pretty conservative. As we know they spent lots of time on internal testing since release.
All the signs mean Gemini 4 argon is a pretty large model than previous.
bitexploder 3 days ago | parent
holaysuns 3 days ago | parent
glouwbug 3 days ago | parent
WillPostForFood 3 days ago | parent
taneq 3 days ago | parent
gazebo2 3 days ago | parent
becquerel 3 days ago | parent
selcuka 3 days ago | parent
staticman2 3 days ago | parent
selcuka 3 days ago | parent
Anthropic controls the full serving stack, so it can change precision, hardware, kernels and settings whenever it likes. Reducing the KV cache precision, for example, saves a lot of memory (and money). It may even be possible to quantise the model on-the-fly when loading it into memory. They don't necessarily have to upload a whole new model.
Even if they can't do the same on all platforms, we can't deterministically compare them anyway.
staticman2 3 days ago | parent
At any rate my point remains that this would require a conspiracy between 3 companies.
KerrAvon 3 days ago | parent
sdenton4 3 days ago | parent
HSO 3 days ago | parent
why? is it not so good on that? or is there something better performance, or better price for same performance?
A_D_E_P_T 3 days ago | parent
That said, I'm extremely impressed with Argon thus far. I take back everything bad I've ever said about their AI strategy. Argon is very good and very fast. It might be competitive at coding, but it's too early to say.
fonrex 3 days ago | parent
chrisweekly 3 days ago | parent
complex_fir_rea 3 days ago | parent
wnm 3 days ago | parent
sharken 3 days ago | parent
Anecdotally, I have had Opus 5.5 decline a reverse engineering effort into a Zigbee gateway that I own.
DeepSeek did not have any issues with this using Claude Code as harness.
chrisweekly 2 days ago | parent
etoxin 3 days ago | parent
charm137 3 days ago | parent
guyomes 3 days ago | parent
charm137 3 days ago | parent
Over the past two weeks, I have started using a locally modified version of deepseek-harness (modifications include disabling telemetry and querying a provider's model list dynamically through Openrouter, instead of relying on the pre-packaged pi-ai manifest that comes with the base code). So far, that has been the best experience - I really like the caching, tokens/sec stats that it provides. (EDIT: I don't know a lick of TypeScript but AI-driven modification of the harness is good enough for me to make these tweaks).
Sandboxing is a definite issue for me. As you perhaps know already, headless operation is often not an option in graphics/game programming which requires actual render-surface instantiations from windowing systems and then input-context handling (keyboard/mouse/gamepad) as well. So I run most development on a VM. But part of my test-suite and smoke-tests rely on runninng it directly on the host OS (which is not ideal). I'd love to hear suggestions to avoid this.
poglet 3 days ago | parent
charm137 3 days ago | parent
You can apply it to the RC2 branch so:
git clone --branch dsh-v0.2.0-rc.2 https://github.com/deepseek-ai/deepseek-harness.git
cd deepseek-harness
git apply /path/to/dsh-v0.2.0-rc.2-to-local.patch
I'd recommend asking the harness to modify itself though (or a cloned repo in another directory) rather than applying the above.
gpderetta 3 days ago | parent
VFIO/GPU passthrough maybe?
kccqzy 3 days ago | parent
Topfi 3 days ago | parent
Found this especially impressive because backpack material related research has been something I know models can still get caught up on and the models being decent at web research in coding nowadays does absolutely not apply to these task equally Recommending nylon canvas shell suppliers or waxed cotton when PVC coated cotton is explicitly request, that sort of thing. While not perfect in reading coding docs, models are far better there.
Like with front end and code “parsability”, feel like you can very clearly point at which labs use what training set, with many often sharing the same suppliers. Once I noticed that, I became very bullish on specific training sets over emergence as the source for current gains.
akoboldfrying 3 days ago | parent
julianz 3 days ago | parent
heyjamesknight 2 days ago | parent
jwpapi 3 days ago | parent
dgacmu 3 days ago | parent
"I'm interested in understanding the rate of VOC dissipation from fresh oil paint on a surface versus the ventilation rate in the room in ACH. I would prefer solid academic studies of this, followed by analytical evaluation, followed by references to non-quantitative sources. Tell me what's known about this."
that I had run in ChatGPT earlier this week. (Yes, we just had our bedroom repainted, and it's TERRIBLE and I hate it, why do you ask? :-).
I didn't try it first in Gemini Flash, but I did try it in whatever model is used for Gemini Live and the answers were terrible. The ChatGPT answer (I think on medium) was pretty good but it threw in extraneous formulae that weren't actually germane to the analysis. The Argon 4 query I just ran was honestly the best of the answers I've gotten -- it was clear and really well-structured from the perspective of "here are the three big phases that researchers break down paint drying into and what the differing effects of ACH are on those phases".
I'm totally going to give this one a try, after basically giving up on 3.8 flash for most things despite having a free $20 pro subscription (from buying a phone).
Edited to add:
Argon4 transcript: https://share.gemini.google/18Gr5liH1YWR
ChatGPT transcript: https://chatgpt.com/share/6acedc72-ff18-83ea-8909-104cdbc6ac...
bjoli 2 days ago | parent
drob518 3 days ago | parent
da_chicken 3 days ago | parent
scarmig 3 days ago | parent
bitexploder 3 days ago | parent
(Disclaimer: I work at teh Goog and spend... a lot of time with these models :)
scarmig 3 days ago | parent
drob518 2 days ago | parent
4dd3aa 3 days ago | parent
Wolfenstein98k 3 days ago | parent
I mean you'd have to crunch the numbers, but Anthropic would need one helluva advantage in efficiency before that would be cheaper to google than the full stack in house
pingou 3 days ago | parent
gigatexal 3 days ago | parent
sebmellen 3 days ago | parent
As an example, I recently had an OCT scan of my retina because I'm a “glaucoma suspect.” I'm a glaucoma suspect because I have an unusually high cup-to-disc ratio, which is a pattern typically seen in glaucomatous patients.
As part of this OCT scan, you get a report back on your RNFL, which is basically a report on the health and thickness of your optic nerve(s) and retina(s). (Dramatically oversimplifying, of course.)
My ophthalmologist struggled to explain my OCT scan results to me and instead sort of shrugged and said, "It's probably because you're a high myope, but we'll keep you coming in once a year.”
But my scans look horrifically bright red — meaning I'm in less than the first percentile of retinal thickness for my age. Obviously concerning enough to do my own research…
ChatGPT 6 Pro and Opus 5.5 have struggled to make any sense of the clinical implications of these scans. In contrast, Argon was the first model to:
1. explain how the OCT machine works
2. detail the physiological mechanism that causes the cupping and thinner RNFL layers in my scenario
3. sum it up into a clinical recommendation (similar to what my ophthalmologist recommended, with the addition of basic supplementation and lifestyle modification changes)
4. provide an interactive visualization of the topography of my eye vs a glaucomatic eye: https://optic-nerve-3d.netlify.app/
I'm blown away.
Alex3917 3 days ago | parent
sebmellen 3 days ago | parent
But, as a patient, it's hard to find comfort in that. I think that might be what drives the craziness in “non-traditional” approaches to treating disease. Could it be that people using fruititarian diets and essential oils for cancer are doing so because they don’t understand enough to bear a “wait and see” situation?
Argon explained the problem to me in such depth that I could be content with my basic treatment plan. ChatGPT went way off the deep end, suggesting things like high-dose niacinamide treatment (which is admittedly being evaluated in clinical trials, but comes with a host of other side effects).
piyh 3 days ago | parent
sebmellen 3 days ago | parent
disillusioned 3 days ago | parent
light_hue_1 3 days ago | parent
Explanations give you a mental model: when I move this parameter this the effect it has. This just shows you the obvious, make a thing bigger, it gets bigger on screen. That's not an explanation.
Models are quite horrible at explaining things. They produce local narrow views that don't take into account the mental model of the listener nor do they attempt to produce the kind of long-term knowledge gain that a teacher does. I taught for over a decade.
This is why models are extremely good for people who already know what they're doing. That narrow why is all you need, like, tell me the 3 sentences that describe the mechanism behind this paper, and I'll get the rest. But building the scaffolding onto which to hang a lot of knowledge?
Give it a try. Try to have a model teach you something new. Not like "how do I tie a knot" but like a new area of math where you're going to dedicate 3 months of your free time to learning it. The results are pretty horrible.
avilay 3 days ago | parent
arational 3 days ago | parent
apsurd 2 days ago | parent
imnotr0b0t 3 days ago | parent
booty 2 days ago | parent
bespoke micro-explainers
FWIW, I haven't seen the Gemini 4 explainers, but Codex and (particularly) Claude have been pretty decent at this for a while.
nl 3 days ago | parent
Thanks for sharing and I hope your eyes remain fine.
bonoboTP 3 days ago | parent
dt3ft 3 days ago | parent
scotty79 3 days ago | parent
clivedup 3 days ago | parent
"Just see a physio" misses that:
* I want the physio's advice during workouts
* I want the physio's advice during moments of pain
* I want the physio to explain things in more detail, but my 30-60 minute appt is not enough, and it's difficult/expensive to book them for longer.
convict 3 days ago | parent
scotty79 3 days ago | parent
lp92 3 days ago | parent
KajMagnus 3 days ago | parent
vanderZwan 3 days ago | parent
It's kind of infuriating to hear Dutch people cite these chatbots without bothering to check https://www.thuisarts.nl/.
Cthulhu_ 3 days ago | parent
vanderZwan 2 days ago | parent
I'm aware, both of my parents are retired GPs.
Back when they retired, about a decade ago, they already had spent a decade complaining that the a constant increase in excessive administrative work got in the way of the actual work of being a doctor that helps their patients. So much that they had joined the strike (remember when that was a big deal because it happened for the first time in Dutch history?)
Anyway, the situation got more complex since then but a lot of pressure is also still administration. Yes, now we have assistants taking on more complex tasks leaving the "important" things to the real doctors, but I think that the need for that is also is in large part due to doctors not getting enough time to be doctors.
And I feel like automation will help fight back at that about as much as IBM's 1967 prediction came true that their office machines would fight back at the "paperwork explosion". Which is to say: Jevons paradox said no.
clivedup 3 days ago | parent
Sometimes I don't know a topic well enough to even know the right terms, or sources. But an LLM can help me become familiar with relevant concepts, and then I can more easily find the authoritative sources.
Sometimes I don't know a topic well enough to know how far it is from my understanding. An LLM helps me quickly learn how closely I have the relevant foundational knowledge: if it's absolutely gobbledygook, then I realise I've probably bitten off more than I can chew; if I half sounds familiar, then I can more confidently begin independent exploring of authoritative sources.
vanderZwan 3 days ago | parent
exographicskip 2 days ago | parent
The problem with google'ing 2 years ago was a combination of SEO hijacking and sheer ignorance on the user's end.
Critical thinking is a necessary ingredient regardless of the tools being used
api 3 days ago | parent
vasco 3 days ago | parent
bonoboTP 2 days ago | parent
SkyBelow 3 days ago | parent
Part of it is using good judgment. Is the AI's claim reasonable if it came from another person? If some random person gave you a 2 page paper proving P=NP, would you even spend time to look at it, or would you simply toss it without caring to understand what error they made. Much like how scientists (and even the patent office) simply refuse to entertain any perpetual motion machines. Maybe if an expert in the field proposed it, and even that would depend upon how ("Hey, I found a source of free energy!" vs "Hey, I'm working through these equations and the energy term isn't balancing, can you help me find what energy source I'm missing?").
This does pose a problem. Those who are the best at understanding the limits of their knowledge and at teaching themselves need the AI's help the least but are in the position to be able to use AI with the best chance of not being misled. Those who lack these skills and would benefit the most from a personal educator, thus receving the biggest benefit in theory, are the ones most likely to fall victim to the errors made by the AI.
api 3 days ago | parent
sebmellen 3 days ago | parent
But you're right that you can't be 100% certain. Isn't that true for human-to-human explanations too?
BonerWiener 1 day ago | parent
Melatonic 3 days ago | parent
terribleperson 1 day ago | parent
adventured 3 days ago | parent
Melatonic 3 days ago | parent
walrus01 3 days ago | parent
lp92 3 days ago | parent
pjm331 3 days ago | parent
I've actually spent some effort trying to make them halfway decent placeholders by putting together a skill based on diataxis framework (https://diataxis.fr/) that at least got everything into the right location
just took a pass at rewriting them w/ argon and am very pleased, big improvement
mwigdahl 3 days ago | parent
edstarch 3 days ago | parent
AspireOne 2 days ago | parent
As a side note, I am kind of sad that basically all models nowadays are RLd to hell and back specifically for coding and deep reasoning, and as a result, they lack in creative writing, human-readable prose, and even general knowledge and abilities (for example, qwen 3.8 27b is a beast for coding, but reportedly falls off the cliff in anything else). Gemini 4 Argon seems to be an example of what you get when you DON'T do that - Google seems to be one of the only labs optimizing for general performance.
I also fear that models cannot be excellent in everything at the same time. I fear that there will always be a heavy tradeoff between what specific field the labs optimize for VS everything else. I don't know.
heyjamesknight 2 days ago | parent
hardbass 3 days ago | parent
transitivebs 2 days ago | parent
georyb 3 days ago | parent
dom96 3 days ago | parent
    Claude Opus 5.5   58.7%
    Gemini 4 Argon    47.1%
    Claude Fable 5.1  46.7%
Language info: https://killswitch-lang.org/
scirob 3 days ago | parent
https://dach.peerbench.ai/compare?models=google%2Fgemini-4-a...
dmd 3 days ago | parent

moecables 3 days ago | parent
simedw 3 days ago | parent
Gemini 3 Flash was around 0.403, 2.5 Pro was around 0.34.
ehsankia 3 days ago | parent
RedCardRef 3 days ago | parent
From what I saw online.
azan_ 3 days ago | parent
iamheretowin 3 days ago | parent
build this scene space station docking scene https://x.com/_satyam_ai/status/2110097633922662752?s=20
manlymuppet 3 days ago | parent
- Natively multi-modality
- Enormous context windows
- Reliably cheap prices
It's like they don't release a model until it passes the above checklist.
Most providers have some mixture of these three occasionally, but with Google, every model is consistent. This kind of consistency is really nice to have.
dudeinhawaii 3 days ago | parent
Outside of that, behavior is quite good, a bit slow, and definitely different than both GPTs and Claudes -- which is appreciated.
beardbandit 3 days ago | parent
antupis 3 days ago | parent
logicallee 3 days ago | parent
do you have to pay those cheap prices eventually or can you just accrue an unlimited amount of overdue charges?
godbox 3 days ago | parent
UnfitFootprint 3 days ago | parent
sunaookami 3 days ago | parent
saejox 3 days ago | parent
sva_ 3 days ago | parent
jadbox 1 day ago | parent
imagetic 3 days ago | parent
vinni2 3 days ago | parent
pamir35 3 days ago | parent
pamir35 3 days ago | parent
tezza 3 days ago | parent
Very fast.
Makes mistakes. Corrects the mistakes quickly with direction.
Google Argon 4: https://share.gemini.google/T9r6tr2dDaTE
I didn't have time to make it into a full blog post yet. Here is a previous one.
https://generative-ai.review/2026/07/kimi-k3-rush-test-vs-cl...
tezza 3 days ago | parent
Astra 6 is significantly better than Google Argon 4 and a lot better than Claude Fable
https://generative-ai.review/2026/10/catchup-openai-astra-6-...
(edited thanks to tekacs)
tekacs 3 days ago | parent
le-mark 3 days ago | parent
oblio 3 days ago | parent
catfood 3 days ago | parent
ssernikk 3 days ago | parent
aetherspawn 3 days ago | parent
OpenAI release any time now
vidarh 3 days ago | parent
If they don't want to make it available even for small tests for free, that's fine, but then don't put a button suggesting I can try it without qualifying it...
EDIT: It's actually worse: The page then shows "Look what you can do with Gemini 4" and a "Let's go" button that leads to a bunch of links to examples, all with enticing pictures. Except if I click on them I get a box stat strongly suggests it'll run with Gemini 4, except the dropdown shows "Flash" and if you click on it, it shows as Gemini 3.6 again, and if you run it, the results unsurprisingly end up looking nothing like their pictures.
I don't know if that page was built by humans or AI, but clearly nobody tested it properly.
fudged71 3 days ago | parent
nharada 3 days ago | parent
radicality 3 days ago | parent
I really can’t believe how bad the Gemini experience is. I have personal paid workspace account, and meant to have some better AI Google features I think.
So, I connected my Gmail to Gemini. 3.6 Flash kept telling me it doesn’t have any Gmail connnection, and then proceeded to hallucinate instructions for me to enable it, all bogus. At least 3.1 Pro realized that my Gmail is connected and then searched.
vidarh 3 days ago | parent
overfeed 3 days ago | parent
...or Gemini 4 is being gradually rolled out and is not available to everyone all at once.
plantain 3 days ago | parent
ninth_ant 3 days ago | parent
But you don’t create a broken or confusing experience for the people who haven’t been added to the rollout group yet.
overfeed 3 days ago | parent
It's an unfortunate downside to conflicting requirements for release-engineering and marketing urgency. In a perfect world, rollout would go from 0-100% instantly, coinciding with the release of marketing material.
In the real world, the trade-offs are either the marketing lands first for some/most people, or delaying marketing is until after rollout reaches, 100%, at which point you're scooped by tech blogs, Twitter AI influencers, and regular media, and immediately lose framing the release from the jump.
vidarh 3 days ago | parent
It is just sheer incompetence that this isn't near the top of their QA checklist.
Heck, even just a message saying it may not be available for all users yet would go a long way. Instead the way it currently works a lot of people will think they're testing Gemini 4 while they're in fact using Gemini 3.6 Flash and getting awful results.
overfeed 3 days ago | parent
Ah, that's so simple and elegant since the state is in one place -the page - and not in multiple sub-systems and products! Thank you for clearing that up.
vidarh 3 days ago | parent
ipiyer 3 days ago | parent
eggplantemoji69 3 days ago | parent
alexmr 3 days ago | parent
ssernikk 3 days ago | parent
JieJie 3 days ago | parent
gigatexal 3 days ago | parent
risphere 3 days ago | parent
stillpointlab 3 days ago | parent
I'm starting to feel the subscription fatigue and a small amount of FOMO. I just can't justify pro accounts for every frontier model now that it includes OpenAI, Anthropic, Meta and Google.
rrr_oh_man 3 days ago | parent
cubefox 3 days ago | parent
sashank_1509 3 days ago | parent
seer 3 days ago | parent
I’ve tried the various alternatives (opencode, pi.dev) but for “have several physical machines, each running an orchestrator and 5-10 agents, and each agent spawning its own subagents to do work in parallel, all of that on a tanky GitHub project boards” level of work only Claude was doing work dependably.
I can have a few orchestrator leads which I talk to and brainstorm, and let them file tickets, organize them and assemble teams of agents to work of the various problems. And all of that with just a smidge of custom tooling on top of Claude Code’s default.
Plus don’t have a budget to spin all of this on cloud runners so I made sure to do as much as I can with local work on several machines I own. Was quite easy to achieve with Claude.
Do you have something similar built on top of a open source harness, or is it from scratch?
jbellis 3 days ago | parent
lowbloodsugar 3 days ago | parent
claude: Help me, Obi-Wan Kenobi. You're my only hope.
me: who is obi-wan kenobi
claude: oh you have to log in again.
me: <logs in>
me: play the whole message
claude: what message?
seer 3 days ago | parent
But ultimately I find it a silver lining more than a problem. I am building and changing tooling so fast, and the models tooling itself is changing so fast, that by the time I establish a workflow, I either A) have solved the original problem so no longer needed, B) have built other tooling that distorts the picture, or C) the labs have released something new and cool that changes the equation drastically so your previous setup is gone anyway.
For example I built some procedure on how to split work between fable and opus and sonnet to optimise token usage, then opus 5.5 came along and made all of this obsolete.
Not per “token usage” mind you, opus is still expensive, but more “effort per task time finish” kind of metric. If I want to close things faster while still being relatively within budget, it is just easier to send all to opus - it will now just solve thigns quicker so you still use similar amount of tokens / money, but quicker, which is a trade I’ll make any day.
And every time “the system is working” I either just stumble onto the next resource constraint, or I feel uncomfortable and start refactoring to make things better and inevitably destabilise the whole “machine”
sashank_1509 3 days ago | parent
seer 3 days ago | parent
So that I'm not just relying on one or a few agents to accomplish a task. I work on the whole product and just drive the direction of tickets and their "what done looks like" requirements, and let the machine organize things on its own, usually 10-20 independent agents (each spawning their own subagents). I think i might have capacity to handle more, just don't have the subscription tokens to fuel it and the budget for the hardware to run it.
Haven't worked in BigCo so no idea how that compares to their tooling. I'm sure it works much more efficiently and on a bigger scale, just being curious about how it all plays out.
solenoid0937 3 days ago | parent
We won't know the answer to this until IPO and until each company reveals the economics of their models (training and serving).
fuzzer371 3 days ago | parent
syradar 3 days ago | parent
wslh 3 days ago | parent
[1] https://github.com/srw/sha256-19step-preimages-with-padding
[2] https://github.com/srw/sha256-20step-preimages-with-no-paddi...
lhk931122 3 days ago | parent
avinoth 3 days ago | parent
Google's years of research project into Indic scripts, image trainings, translation efforts & transliteration efforts is literally paying off. The AI adoption from non-English, non-Chinese population will only if you have these contextual localisations, which I think Gemini is poised to do well.
For example, you can ask for a shopping list for a marriage function in a town from Tamil nadu (the marriage custom varies by districts), and Gemini provides contextual and helpful answer (like what is the custom followed there, what is gifted traditionally, etc), whereas if you ask Claude/ChatGPT, it talks about marriage registeries or pretty generalised answers which is not relevant or useful.
rootsu 3 days ago | parent
Hugada 1 day ago | parent
Tepix 3 days ago | parent
casey2 3 days ago | parent
Still reading up on it here: https://ai.google.dev/gemini-api/docs/long-decode and needs lots of community testing to determine whether it's a "true" 1M token output window.
parasti 3 days ago | parent
makeramen 3 days ago | parent
racitin 3 days ago | parent
aashu_dwivedi 3 days ago | parent
SilverSlash 3 days ago | parent
MaxikCZ 3 days ago | parent
Like when Miller in The Expanse talk to phone AI (https://m.youtube.com/watch?v=SC3bpJmGnPo) to trace Anubis flight, notice how the phone doesnt even reply in words.
Imagine if the phone instead replied with: "Thats a great insight, Anubis really goes there", it would be a joke. We are only tolerating it now because everyone is doing it.
gertlabs 3 days ago | parent
Google's major releases have usually done pretty well on our benchmarks because they're good at hard problems and open-ended decision making (with a well specified prompt), which obviously doesn't always translate to user experience. In particular, older Google models struggled to work efficiently in a harness. They seem to have solved that with Argon.
We did see a new problem which I hope they can fix. This is the first near-frontier model we've caught in infinite reasoning loops in a long time. We also saw a few examples of it failing to properly delineate reasoning blocks, so it has a higher failure rate than its competitors.
My overall impression is that Argon is a near-frontier model for engineering design, code analysis, and chat. It definitely has the intelligence to be a competitive coding assistant product, but a good coding assistant needs to be polished, so I hope they can clean up the CoT bugs.
Data at https://gertlabs.com/rankings
phillc73 3 days ago | parent
Depends on where you draw the line for "near frontier model", but the current leading open-weights model, MiMo-v2.6, has exactly this problem. They released a fix on Hugging Face[1], but as of two days ago the model available via Xiaomi's own API still sticks in reasoning loops.
alfiedotwtf 2 days ago | parent
phillc73 2 days ago | parent
destring 3 days ago | parent
amelius 3 days ago | parent
brna-2 3 days ago | parent
Yep, it will generate what ever you ask for but if you want to have some sort of exploratory work, immersion, feeling of ownership and genuinely a connection with the things you are building - a part the build loop should belong to you.
Maybe this is an attachment of people who built things in other ways. Maybe the perceived value of applications will drop to near 0 and you will end up having all in one apps or voice wants like to a star trek replicator. Fun things are coming, but humanity will need to adjust hard - best case scenario.
simpaticoder 3 days ago | parent
helloguillecl 2 days ago | parent
ckx 3 days ago | parent
booty 2 days ago | parent
- Basic style/linter rules (so you don't get 200-line functions, etc) paired w/ instructing your agent how to use them goes a long way (e.g., a sane rubocop.yml in your repo, plus a note in AGENTS.md telling the agents how to run rubocop, or whatever makes sense for your language) - I have a code review skill that specifically calls out human-readability concerns such as making sure that identifier names represent their contents and intended use
The other key IME is that you need to make readability/refactoring passes outside of a particular pull request. When working on a specific branch the LLMs will be somewhat myopic, and do stuff that looks pretty good in isolation, but when you zoom out and look at the bigger picture it's kind of a mess - for example, often they'll duplicate some code that existed elsewhere.
The LLMs are also pretty good at generating Mermaid charts and tracing execution flows, which is a great way to understand code. It doesn't help them to produce more readable code but it helps me to understand code I'm unfamiliar with.
amelius 3 days ago | parent
sylware 3 days ago | parent
I don't want computer languages with complex syntax anywhere near me: that's why transpilers of those very languages to languages with a simpler syntax (usually plain and simple C or directly "human" assembly) are in my opinion so much important (we have a c++ to C transpiler and a microsoft rust to C transpiler, coded with the assistance of AI, and those should only improve from there).
For me, the current main issue of "AI" is their gatekeeping using the whatwg cartel web engines, yes, technical access to "AI" will have to be hardcore regulated if it becomes ubiquitous, and I said 'technical access', not AI itself, the difference is abysmal, it is an interop issue.
gertlabs 2 days ago | parent
port3000 3 days ago | parent
This seems to be such a Google thing. Anyone who has used Gemini for long enough has encountered these 'She loves me, She loves me not' spam loops
pjjpo 3 days ago | parent
spider-mario 2 days ago | parent
vessenes 2 days ago | parent
gertlabs 2 days ago | parent
miki123211 2 days ago | parent
Bobaso 2 days ago | parent
elohimus 3 days ago | parent
taventix 3 days ago | parent
taventix 3 days ago | parent
civvv 3 days ago | parent
oh_ok_lol 3 days ago | parent
Weryj 3 days ago | parent
lp92 3 days ago | parent
asdewqqwer 3 days ago | parent
Revanche1367 3 days ago | parent
Without going into details, for a small part of a larger task, I asked it to classify different content types of different files and formulate a structured mapping (e.g., in JSON) between content types and another set of files (deliberately left vague here but not to Argon) from my codebase. I even offered it a multi-part draft of a classification system to start with and told it that if it can find other classification systems from international standards, academia or industry more suitable to the task than my rough draft, we can discuss replacing my suggestion. There were other parts to the instructions too, written out like an article with bulleted lists, precise program-like wording, etc. Then, I sent the prompt and left for a while.
When I came back, it was nearly done with the implementation but the classification system it came up with was a mess. It even admitted to making up "bogus" classification standards when I pointed out some errors. It also kept leaving gaps multiple times when I referenced errors to fix in subsequent instructions (and not once apologized the entire time lol). So my first impression was subpar, not really comparable IMO with Opus >=5 or Sol >=6, and seemed to leave larger gaps than 3.8 flash typically does. The most irritating part to me was not only the fact that it was making up things, but that it ignored my instructions to discuss things with me before deciding to shift away from my draft; I don't recall any major LLM ignoring an instruction like that in at least a year.
leastangle 3 days ago | parent
ur-whale 2 days ago | parent
The others are quite bad as well in that regard, but on this particular metric, Google has always been top dog. Goes back to way before AI ever took off, BTW.
terminal-bloom 2 days ago | parent
nmacias 2 days ago | parent
DuncanCoffee 2 days ago | parent
State of affairs [1]:
> My whole project and career depended on the 3.1 pro workflow. Please, bring it back
[1] https://discuss.ai.google.dev/t/please-bring-gemini-3-1-pro-...
cjonas 2 days ago | parent
I asked for a QUICK healthcheck on the sync status of a bigquery integration. It literally spun for 25m before I killed it.
The task, which is CLEARLY outlined in the agent readmes just involved using the gcloud cli to initiate auth, then just run a few queries to check logs and timestamps.
Even 3.6 flash can get this right (most the time).
utopman 2 days ago | parent
chriddyp 2 days ago | parent
Excellent model. Same price and score as Opus 5.5 in our 23 question exam.
This size / class of model is now a bit overpowered for these short-horizon data analytics tasks. OpenAI 6.1-Sol, Haiku 5.5, GLM 5.3 Flash all achieve about the same results but for ~1/10th the cost.
In other words, we're getting to the stage where models are "good enough" for certain tasks like data analytics and competitiveness is going towards size & speed.
goryramsy 2 days ago | parent
Seems to be just deleting anything that a safety filter triggers on. I don't know if I like this more or less than what Anthropic does where they train the model to actively refuse.
Christine725 2 days ago | parent
blurbleblurble 1 day ago | parent