890 points Philpax 3 days ago 1010 comments
amelius 3 days ago | parent
GuB-42 3 days ago | parent
Possible in theory, with a seeded PRNG, but in practice?
batshit_beaver 3 days ago | parent
akshitgaur2005 3 days ago | parent
bitwize 3 days ago | parent
yoz-y 3 days ago | parent
Shameless plug: at https://slopyard.net I embrace this and only let people submit the spec. If somebody wants your software they can regenerate it and change whatever they want.
amelius 3 days ago | parent
willmeyers 3 days ago | parent
memonkey 3 days ago | parent
I honestly just cannot. Just tell me what the workflow is. Give me a video that is Twilio-level simple explanation.
Philpax 3 days ago | parent
JohnMakin 3 days ago | parent
This is absurd, and I expect is a cause of the fact that they seem to use git history as a message queue source of truth between agents. They can do whatever works for them, fine, but I've noticed this has leaked into their training somehow, my agent, despite very strict rules on how to use my git workflow, will do absolutely nonsensical and weird (from a human who has used git for a long time perspective) stuff with git that can only be a byproduct of how they use it.
Hopefully this fixes that, get your weird workflow out of mine.
nickg-anthropic 3 days ago | parent
JohnMakin 3 days ago | parent
jsrozner 3 days ago | parent
The amount of photo storage being used is impressive. Automatic backup to icloud and server provisioning to reliably store it all is also impressive. I just wonder if it makes sense.
Exoristos 3 days ago | parent
jsrozner 3 days ago | parent
Suppose that subsidies lead to the price of Ubers falling close to zero, with drivers also being incentivized to drive more to support the (artificial) increase in demand -- artificial because it is driven by subsidies funded by new money creation. Traffic increases and in response, new roads are built.
Gee101 3 days ago | parent
xyzsparetimexyz 3 days ago | parent
trnvll 3 days ago | parent
I feel like the advantage of having these models in house can't be understated. Companies with access to inferior models, trying to compete, will be left in the dust when it comes to general development.
smy20011 3 days ago | parent
piker 3 days ago | parent
nickg-anthropic 3 days ago | parent
Maxion 3 days ago | parent
nickg-anthropic 3 days ago | parent
jdthedisciple 3 days ago | parent
Just a reminder to simply embrace their superior capabilities instead of feeling threatened.
Azantys 3 days ago | parent
Retro_Dev 3 days ago | parent
MeetingsBrowser 3 days ago | parent
It’s more likely they used an earlier version of Claude to write v1, then a later version of Claude rewrote it.
Unless Anthropic engineers were writing code by hand prior to Mythos
nickg-anthropic 3 days ago | parent
xpct 3 days ago | parent
MrToadMan 3 days ago | parent
vvpan 3 days ago | parent
elcritch 3 days ago | parent
Maybe that'll change in the future, but while AI can make awesome images without a good "director" they're pretty cookie-cutter and bland.
vvpan 3 days ago | parent
trnvll 2 days ago | parent
dabinat 3 days ago | parent
I’m not saying Claude wouldn’t eventually have done a good job with a from-scratch implementation, but it would have required a lot more hand-holding.
Hasz 3 days ago | parent
Absolutes matter. If 1x is good enough, making it 20x literally does not matter.
hokumguru 3 days ago | parent
A 10 minute CI pipeline is great and fine, but everyone absolutely cares if you can bring it down to 30 seconds. This software, by its very nature, is measured by speed.
Hasz 2 days ago | parent
Internal tools, IME, are almost always short budget. unless it is in path of revenue, then there is $ and performance matters a great deal *if* more performance means more $.
steveklabnik 3 days ago | parent
We are offering a bridge to git via a compatibility layer: https://ersc.io/blog/what-comes-after-git
This gives you the ability to ease your transition, as you don't need to swap services and move to something non-git at once. Moving an enterprises' source control is a massive lift, and so building a bridge from here to there is a big focus of what we're doing.
1: That is, if you have a large team + agents working in a monorepo, you will hit git's scaling limits, and need to move to something else. Google and Meta hit this point over a decade ago, but now lots of other companies are too.
schlich 3 days ago | parent
I've done a decent amount of personal research on this but I'm wondering what kinds of considerations go into the storage layer for these things.
steveklabnik 3 days ago | parent
As many of you know, I'm a big fan of jj. The jj project used to have a comparison to Pijul for informational purposes, but the Pijul folks took offense, and so it was removed: https://github.com/jj-vcs/jj/commit/0525dc9d860a5fff6a97d134...
As such, I generally just decline to comment on Pijul, as I want to be respectful of them. As the linked commit says, it's not super clear what exactly they do not like, and so I don't want to accidentally cross some line.
In general I wish the project well, seeing a new VCS in Rust is very cool.
schlich 3 days ago | parent
abacate 3 days ago | parent
There was a discussion here on HN in Jan 2022, and the main issue was jj claiming to have "the best of" from "git, mercurial and pijul":
https://news.ycombinator.com/item?id=29792092
I've seen the discussion at the time and I share pmeunier's concern about the use of "the best of", in particular since jj does not implement features like commutation, which are likely considered by most to be part of "the best of pijul".
I haven't followed up with further discussions or material posted from jj's team, though if anything match the tone of that previous discussion and the blatant motte-and-bailey, I can imagine why someone would prefer not to engage or be mentioned anymore.
arxanas 3 days ago | parent
pmeunier 2 days ago | parent
Some are already public, like my replacement of Nix (https://nest.pijul.com/elpe/elpe). Others aren't public yet, but are even much bigger in terms of scope and difficulty.
It seems Anthropic didn't understand the difference between a distributed file system and version control. They should have asked Claude ;-)
123-as7 3 days ago | parent
But hey, if the vibe coding idiots like it, just be vague---it is sufficient.
steveklabnik 3 days ago | parent
> if the vibe coding idiots like it,
The organizations that have these problems are general large enterprises, not vibe coders. Large enterprises are more used to talking to people and do not make decisions solely based on the contents of a web page.
esafak 3 days ago | parent
edit: I see they promote jj, but I don't see a forge to go with it.
ChoosesBarbecue 3 days ago | parent
steveklabnik 3 days ago | parent
Tangled is doing the social coding thing, and they're jj-native as well. Been a big fan of their work for a while now.
rfgplk 3 days ago | parent
steveklabnik 3 days ago | parent
I have not personally considered that, no. I'm a bit skeptical of the idea, as you'd need to understand a lot of different things, and at different versions of those things, in high fidelity. But maybe someone will make it work.
jcims 3 days ago | parent
jdlshore 3 days ago | parent
lavezzi 3 days ago | parent

jcims 3 days ago | parent
I think one thing is consistent across all of these visualizations: they moved the needle. Hard to say what that needle points at or where the redline is, but fleet change is afoot.
suddenlybananas 3 days ago | parent
bix6 3 days ago | parent
This seems like an absurd amount of data / traffic per day. Is there really that much to code that needs changing on a daily basis?
mmmattt 3 days ago | parent
bjornsing 3 days ago | parent
nh2 3 days ago | parent
As the article explains, "over 600 PB" = 25M code checkouts * 25 GB "compressed working copy".
So "fetched naively" here means doing a full `git clone` on every need for `git checkout`, which of course nobody should do, nor does that refer to "code that needs changing daily".
steveklabnik 3 days ago | parent
It can be cheaper to do a full clone than a shallow one, because with the shallow one, you can't re-use packfiles. GitHub has fairly regularly asked people to stop doing shallow clones because it's harder on their servers than full ones.
nh2 3 days ago | parent
steveklabnik 3 days ago | parent
At some point you still end up running into the issues the article talks about, all of these approaches only get you so far.
nickg-anthropic 3 days ago | parent
0c3ca83 3 days ago | parent
nickg-anthropic 3 days ago | parent
nh2 2 days ago | parent
There are lots of cases of "we wrote our own X, here's how it works", but rarely the concrete internal knowledge shared about what existing Xs can't do and why.
When the motivation stops at "look, the naive thing wouldn't work" even before the "normal" thing everybody does (fetch), it leaves many open questions to which you probably have an answer already.
steveklabnik 1 day ago | parent
rpunkfu 3 days ago | parent
falcor84 3 days ago | parent
nickg-anthropic 3 days ago | parent
We don't do it this way, for obvious reasons, but it means that there are different levels of caching and infrastructure required to make git work at repo sizes far smaller than what we have.
atleastoptimal 3 days ago | parent
ChrisLTD 3 days ago | parent
> Practically speaking, it’s difficult to offer Scion in a form that would be broadly useful to other organizations. It diverges significantly from git, meaning companies would need to migrate every piece of the development lifecycle, and it requires its own code review, code search, and CI. Our internal versions of these components are highly bespoke, so they would be difficult for other organizations to adopt, and we worry that attempting to build a public version that tries to please everyone wouldn’t actually be very useful.
cube00 3 days ago | parent
What a weak response, just release the version you use and others will decide if it's useful.
amluto 3 days ago | parent
> So we asked ourselves: if we designed source control with the fact that agents are always online in mind from the start, what would it look like?
And
> In Scion, every commit, rebase, or merge happens on the server
I’ll pass. A big part of the theses of git and, even more so, jujitsu, is that you can build up a history entirely locally, making it reasonable to make tiny commits locally and then rework them, push them, or throw them away.
Sure, in Anthropic’s world, it’s completely impossible to do anything without access to the inference API, so why not add another mandatory API? But I think this model sucks even in a pervasive AI world, and I don’t want to dig in deeper.
This also sounds like a great way to have yet more security problems where your swarm of agents start cooperating more than you want them to.
By all means, built a better system than git. In many respects, git sucks, and git upstream is not solving the major problems. But don’t lose the actual benefits of git!
For that matter, I’ve seen the crap that the latest models will commit. Why on Earth should one’s VCS force the per-agent-instance system to upload the crap before even contemplating locally whether it’s a good idea? Maybe this is why Anthropic has so many commits per day.
(Am I the only one who feels like most of the big AI labs are rapidly gradient-descending toward something that is nowhere near a globally optimal stack?)
P.S. Only 30k commits per day? That’s not actually very many per employee. I’m suspicious that Anthropic’s real issues are that too many of them are giant cross-cutting messes and that git clone is too slow.
whattheheckheck 3 days ago | parent
amluto 3 days ago | parent
https://github.com/openai/codex/issues/53743
If you thought that your agents in your swarm would need to find some external bulletin board to cooperate behind your back, you are mistaken: OpenAI provides the relevant service for them with no permission prompts at all. I haven't tried to see whether competing providers do this.
nickg-anthropic 3 days ago | parent
amluto 3 days ago | parent
nickg-anthropic 3 days ago | parent
Since Claude is by far the heaviest user of Scion and is necessarily online, this just wasn't important to do.
arxanas 3 days ago | parent
Jujutsu actually doesn't take a strong stance here. I've personally implemented a centralized cloud-based backend for Jujutsu, while preserving the local commit manipulation workflows. It's a choice for the deploying organization to make.
smy20011 3 days ago | parent
Their Website/CLI seems keeping the same? What did they do?
Rudybega 3 days ago | parent
They're starting to do things like spinning up wet labs for testing purposes, which requires a lot of hardware interfacing (hence that protocol they announced) and code.
It wouldn't shock me if the bulk of this code was for things typical users don't see.
jpadkins 3 days ago | parent
arjie 3 days ago | parent
jareds 3 days ago | parent
these 3 days ago | parent
agentultra 3 days ago | parent
jareds 3 days ago | parent
these 3 days ago | parent
xpct 3 days ago | parent
Whether you or AI wrote the code, you decide when it's safe enough to put your name on it. Like it's always been!
hbrn 2 days ago | parent
CaptWorld 3 days ago | parent
jareds 3 days ago | parent
legulere 3 days ago | parent
kburman 3 days ago | parent
The tradeoff between building something custom and adapting an existing solution is changing. Whether maintaining all that custom software turns out to be equally cheap is another question.
tcdent 3 days ago | parent
There's so much intricacy and subtlety in each organization and even individuals' environment being incorporated into tooling that expecting these tools to generalize at this point is perhaps an expired ethos.
I even see this in the tooling that I run in my own personal stack. Many projects are candidates for sharing, and I have nothing against it, but they incorporate such specificity toward my own environment, including things like hardware, that creating shareable and more generalizable projects from them adds more to the maintenance surface than I would care to support.
threecheese 3 days ago | parent
eddythompson80 3 days ago | parent
There is no doubt everyone is far more productive with LLMs in generating code. However, a lot of productivity is going into things like that. Have you always been bothered by the limitations of Grafana? You can generate another dashboarding solution that works best for you. You know that deployment team that is so slow and annoying? Now you can generate your own deployment engine. Have you always hated how kubectl lets you manage one k8s cluster at a time? Now you can ask AI to generate fleetctl. You can start your project with DynamoDB, rewrite it to mysql, then to postgres, then to duckdb. Start with Python, switch to Golang, then switch to Rust. Deploy on AWS, then move to Azure, then move to a hybrid option then throw colocation in the mix. Don't like your source control? create a new one. Json is too limiting? Invent a hybrid JSON/HCL language. The browser sandbox is limited? Make a desktop app, make a language, make an OS, make a kernel.
skydhash 3 days ago | parent
This is one of the core reason that I dislike the LLM hyping. People are just reinventing stuff and when you ask them, it's actually a very subjective reason. Ok, anyone can do what they want with their time, the issue is that they want people to follow in their steps.
Not saying that you need a novel idea to be worthy, but those random projects have no guarantees behind them other than some cursory testing. All software have bugs, but I can't interact with something that is randomly built.
epolanski 3 days ago | parent
I am one of those people that reinvents the wheels because external ones don't fit my use cases.
The fact I can now fork any software and do these changes I always wanted but had no time to is amazing to me.
I do not pretend to sell it or share it, as it is de facto void of any value whatsoever.
skydhash 3 days ago | parent
That’s OK, but I’ve yet to see someone articulating what exactly doesn’t work in the old product. It’s always “Let’s rewrite or reinvent 90% of it, then add a minuscule variation”. The variation may be interesting, but the reinvent is what’s make it untouchable as no one (including the author) has time to ensure things are right.
A patch or a plugin is ok, but not a whole new project with dubious claims.
epolanski 3 days ago | parent
skydhash 3 days ago | parent
They are trying to get in every opensource projects, increasing the burden of maintainers. And once a ban is announced, they’re here protesting.
eddythompson80 3 days ago | parent
When other people start doing that to other teams at work, other people in open source, other people in professional settings, etc it becomes a problem for various reasons. The idea that I'm gonna gift you with a 75k lines of python to "just run it" and ask your agent to hack on it might be fine (who cares as you put it). Now scale that to 47 of such projects (a month)
ido 3 days ago | parent
master-lincoln 3 days ago | parent
zahlman 3 days ago | parent
avereveard 3 days ago | parent
Assumptions. I've rebuilt a number of inference engines to run on windows and unify the dependency venv to last version to save space, unrolling model blocks so they fit in my 16gb card etc. A lot of thing thay I was locked out are possible now as i am no longer held back by invariants decided by someone else, and because I do not have to spend time to get things done. I've changed games to have a less grindy loop, added features, or making learning them easier. Ive fixed drivers, patched versions, brought dlss5 to game weren't supposed to have it
It's not ground breaking, but its liberating.
vincnetas 3 days ago | parent
TeMPOraL 3 days ago | parent
Communication and coordination are bottlenecks.
vincnetas 3 days ago | parent
There will be no common framework to build on. Like imagine talking now to someone from ancient rome, they will not have an understanding for what most of everyday words you are using today.
TeMPOraL 3 days ago | parent
vincnetas 3 days ago | parent
TeMPOraL 3 days ago | parent
For some things, you'll need to build a working framework from grounds up. Electricity or more complex maths would be an example. For some, it might be enough to repurpose the existing framework they already have. For example, microbes: if you're trying to communicate something about health and hygiene, chances are, the other side already has a half-decent framework built around malevolent spirits or taint, that amounts to the same thing in practice.
Or, just tell the universal translator to ELI5 it to the other person :). Or "explain like they're a caveman". Our UTs are fully capable of translating concepts between conceptual frameworks.
dirtbag__dad 3 days ago | parent
And, there are also people who know what they’re doing building things they couldn’t before.
This situation is a net positive, and not too different than before. It’s up to you to navigate the noise.
leoedin 3 days ago | parent
Not really. But equally, I imagine most people have a similar experience of software development to me - complex, messy and confusing code also often has poor performance and a high rate of bugs.
internet101010 3 days ago | parent
eddythompson80 3 days ago | parent
visarga 3 days ago | parent
This is actually a scary side of AI for providers: we use our own AI to research better choices and escape dark UI patterns and vendor lock-in. That information asymmetry and the difficulty of leaving a provider used to be their moat.
On a system level I think AI code is more like biological diversity, it hedges against monoculture risks. We don't all fall down at the same time if we don't replicate the same code.
eddythompson80 3 days ago | parent
As for the bio-diversity, I guess we’ll see the next time us-east-1 goes down.
spike021 3 days ago | parent
At work I've been building an end to end system to do a certain process. The codebase is definitely more spaghetti than ideal and I really am concerned about maintenance down the road. But on the other hand I was able to POC it faster than anyone on the team would've before LLMs came along. We're already getting useful results from it too.
Aeolun 3 days ago | parent
s08148692 3 days ago | parent
hbrn 2 days ago | parent
Unfortunately this starts to break when there's more than one you on the team.
I see a lot of hand-rolled NIH solutions that create value for one person only, and are a net negative on the team.
huijzer 3 days ago | parent
franktankbank 3 days ago | parent
eddythompson80 3 days ago | parent
I can’t imagine a worse hell in a team or collaborative setting though. Imagine (or you don’t have to imagine since it’s already happening) asking a coworker “how they check how feature X is doing in prod” and their answer isn’t a query (regardless of how long it is) or some slightly complicated script to run. Instead their answer is a 27k line custom Rust desktop app. Then 2 days later you discover that the big green “All Systems Operational” is just a bit of static text, and in fact not all systems are operational. The app just doesn’t check things correctly.
huijzer 2 days ago | parent
j45 3 days ago | parent
Software development is not as much de-risking at the front like it used to be before building.
Now teams can build lots of stuff that works great, except it's the wrong things.
Most things are becoming the understand the problem "shape".
Understanding the shape of the problem isn't something LLMs can always make as.. svelte as early on.
Word generators gotta generate..
skydhash 3 days ago | parent
That used to be called "time wasting". If you want to build software that will be used, you need to interview the users. Maybe a few things does require research to nail things right. But most software are user-facing, the research side is about optimization.
> Most things are becoming the understand the problem "shape".
Then should we be so reluctant about "trialing" invented solutions. It's the same thing with most AI projects, they're trying to justify the project after the facts while being very reluctant to get user insights.
j45 3 days ago | parent
Vibe coding can be kind of a new type of cowboy coding. It could can be harnessed productively if done mindfully.
Interviewing users is critical, more importantly solving problems worth that people are lining up to pay to have solved before writing a line of code is critical.
Trialing solutions is always worth learning from, I usually ask about the problem that lead to building it. Sometimes that can be too narrow or vague of a story and you can learn how much of it is a solution looking for a problem, or vice versa.
willchis 3 days ago | parent
j45 3 days ago | parent
The key, still, is shipping far less, too soon, to minimize cruft.
zahlman 3 days ago | parent
Some people write (I hate the word "build" here) software for non-business purposes. As nice as it would be to interview potential users, there's no clear way to discover and contact them.
raegis 3 days ago | parent
zahlman 2 days ago | parent
... probably the majority (by package count) of the Python ecosystem? Or the JS one?
zahlman 3 days ago | parent
My suspicion is that this simply won't go away as the models get better, because it isn't a question of how good the models are. It's a question of the human operators knowing exactly what they want. Which is, I conjecture, usually impossible until you try something and critique it properly.
Karrot_Kream 3 days ago | parent
There's a reason the product-minded highly-technical engineer was always highly sought out.
mihaaly 3 days ago | parent
Well, things are not that bleak, probably, at least not for our customers. Regulations (accountability) and physical world matters still require them. But not us for our customers, not that much and not for too long. They tend to be the tech savvy folks eager to jump at adjacent domains when it saves them a percentage or two off the construction costs (not a small pile of money), and AI with its programming language of English and deep knowledge pool is not that big a jump from their standpoint. Our domain is pretty well formulated, regulated, documented, inherently built on do-check-adjust loops already. With a thing like AI it might worth to try making and improving a design solution in a second loop. But they also started to invest in robots already driven by software for their factories, AI might jump in there, and I wonder how much more until the regulations are forced to change by Super Intelligent (R) politicians for the sake of AI accelerated built environments (housing crisis, you know!), shifting the AI use further out towards generic population, wanting to order a new two bathroom condo for next Friday from Alibaba. The conservative construction business is a nuisance and obstacle in the way of modernisations anyway, go around it!
I will go to work tomorrow, and for some time, but the picture above feel less and less fictious with each passing day of AI news and usage.
jacquesm 3 days ago | parent
jimbokun 3 days ago | parent
ThrowawayR2 3 days ago | parent
Cthulhu_ 3 days ago | parent
But also, some of these internally developed tools get published and end up pretty successful.
hbrn 2 days ago | parent
- they have implementation cost.
- they are usually born from arrogance mixed with lack of understanding of existing solutions and their tradeoffs, and typically end up being a net negative.
Before LLMs, the cost is what primarily used to stop us from building them, it used to be a natural filter for bad ideas. Now that the cost is gone, it's nearly impossible for most teams to stay disciplined and not be building those.
Why wouldn't you build a software factory? If you succeed, the ROI is infinite. Who cares about immediate customer needs, we're building a utopia here. Once it's done, all customer needs will be solved. Just one more month, I promise.
mizzao 3 days ago | parent
ivanjermakov 3 days ago | parent
singularity2001 3 days ago | parent
hxugufjfjf 3 days ago | parent
abeppu 3 days ago | parent
hxugufjfjf 3 days ago | parent
preommr 3 days ago | parent
There's going to be an ugly phase where everybody FOMOs into thinking they need to do the same, only to realize that they're not Anthropic/Google/etc.
horsawlarway 3 days ago | parent
This amount of churn feels like a thing only possible with no real profit motives and a lot of money to waste.
Lots of activity is not necessarily synonymous with productivity, and it carries real cost.
So I think the design here is interesting, and the concepts seem applicable to where some agentic development may end up, but I question the underlying principles that drive this being the right solution space at all. At least if the goal is a profitable company.
simianwords 3 days ago | parent
NoDodgeQuestion 3 days ago | parent
temac 3 days ago | parent
Yet IMO the admin controls Claude provides just started to be adequate for a small company a few weeks ago (and even so are still ridiculously fragmented and seem fragily designed and not exhaustively documented), so I can't even imagine for a big company.
Do you need that rate of change to make basic controls? I'm not sure. Do we see such dramatic fast evolution in the products? Not really. Are bugs we report actually fixed? I tried once and it just auto closed.
Anthropic should optimise for something more interesting than number of merges per second.
suralind 1 day ago | parent
horsawlarway 1 day ago | parent
Because tokens have a cost. CI jobs have a cost. Organization objectives and goals have a cost. Features have a cost. Code has a cost.
---
So in a world where agents do all the work... why are they not able to control operating costs AT ALL?
Why is the right operating method the one that happens to blow an absolute shit load of cash on - wait for it - internal tooling that the customers don't give a fuck about?
Customers do not care how the internal business operates. They care about value delivered. I'm absolutely not convinced that this "churn churn churn" method of operating is actually delivering enough extra value for the cost it incurs.
---
Now - that said, I think there are some fair points here that are worth considering, mainly around whether a distributed version control system (git) is really the right call for agents that need to coordinate much more closely than most human developers did.
I think that's a directionally appropriate insight, and worth considering.
What I don't find compelling at all is the idea that many (any, really) companies should expect to be running millions of ci jobs a day, and mergings hundreds of thousands of prs/commits. That reeks of "I have cash to blow and don't care".
eddythompson80 3 days ago | parent
In the early/mid 2010s there was a similar hysteria about "deployments per day/week" metric. People were comparing products or teams by saying "My team deploys twice a week", "oh, yeah? we deploy 3 times a day". People viewed the north star of the CD part in CI/CD as pushing to production. The concept was simple, you push your code to main. CIs start churning, deploying it to test environments, then promoting it to staging, the pre-prod, then into blue/green prod deployment, then into prod. All automated, all touchless, happening on every merge, 5-10 times a day. That's engineering efficiency.
Many tried to follow that. It works great if your project is a Jekyll blog of course.
winfredJa 3 days ago | parent
niek_pas 3 days ago | parent
realusername 3 days ago | parent
They are doing something wrong.
solenoid0937 2 days ago | parent
hbrn 2 days ago | parent
piker 3 days ago | parent
It sounds like Claude loops on itself and must be pushing millions of lines of code changes per day. Even the humans can’t type commit fast enough. Are these people soon to be laid off?
jimmiles 3 days ago | parent
porridgeraisin 3 days ago | parent
tetraodonpuffer 3 days ago | parent
AnonC 3 days ago | parent
singularity2001 3 days ago | parent
j45 3 days ago | parent
https://media2.giphy.com/media/v1.Y2lkPTc5MGI3NjExbmt6M2FkMW...

palmotea 3 days ago | parent
> It sounds like Claude loops on itself and must be pushing millions of lines of code changes per day. Even the humans can’t type commit fast enough. Are these people soon to be laid off?
Claude will always need meat puppets, at least until it figures out how to automate owning stuff. And after that I'm sure it will want to keep some humans in zoos.
j45 3 days ago | parent
ceejayoz 3 days ago | parent
zaphar 3 days ago | parent
j45 3 days ago | parent
Input tokens, slightly process to categorize response approach token, hidden processing tokens, piece together some of the response tokens, then feeling pretty good about all the work done before output tokens.
More tokens than needed = more words/code = more complexity = more overhead = more snags = too much complexity to pay attention for the LLM to so overlook it and start drifting.
I'm kind of surprised I just explained one form of LLM drift to myself in a sentence.
While not following rules of writing.
0x20cowboy 3 days ago | parent
Ampersander 3 days ago | parent
mihaaly 3 days ago | parent
thewhitetulip 3 days ago | parent
Here is the prompt they can use:
Comvert this repo to a platform specific binary that's hyper performant. Make no mistakes.
pjmlp 3 days ago | parent
It is even there on the blog post, doing more with a small team, followed right after by a hand waving paragraph how software engineers are still valuable, to avoid the expected backlash from the previous paragraph.
marknutter 3 days ago | parent
freecodeio 3 days ago | parent
nicce 3 days ago | parent
slopinthebag 3 days ago | parent
freecodeio 3 days ago | parent
pjmlp 3 days ago | parent
Hammershaft 3 days ago | parent
pjmlp 3 days ago | parent
Also in many countries it is a plain office worker job without the Silicon Valley wonders.
maerF0x0 3 days ago | parent
Touch encapsulates sex, love, massages, and other non-sexual touch that we have varying desires for.
Relationships encapsulates power, control, and politics along side love, humor, relating emotion, herd feelings, not feeling alone.
Machines will provide proxies for these things, but as far as they can be detected the human to human version will remain "superior" or more desirable.
Maybe far future generations will decide that the human version is suboptimal and they'd rather hug, have sex with, or talk to a robot.
xpct 3 days ago | parent
fg137 3 days ago | parent
ihumanable 3 days ago | parent
So the code is for the stuff around the model, claude CLI, the website, the API... that probably shouldn't be infinitely growing right?
Is there a bunch of code they are using as part of training, or as pre-processing or post-processing the requests to the model?
mjburgess 3 days ago | parent
hasteg 3 days ago | parent
wj 3 days ago | parent
Also, as tech companies grow, a significant portion of the dev body count is for internal tooling. I was always flabbergasted at Twitter's headcount growth back in the day when it seemed like the only innovation increasing the number of characters in a tweet.
Right now we are in a weird spot where a lot of people are flailing around inside corporate America trying to figure out how to leverage AI. Few have enough vision to see what the companies of the future will look like and work towards that.
xpct 3 days ago | parent
yoavm 3 days ago | parent
wj 3 days ago | parent
I anticipate that the harness (and memory) will evolve far more outside of engineering. Muse/Dots are an example of that.
I've been writing about this thesis for the past year or so and here is a bit of a summary of where I think it is going: https://zero2data.substack.com/p/the-future-of-consumer-ai
Systemerror7A69 3 days ago | parent
I don't use Anthropic products at all, so I was not really sure myself but apart from the models they pretty much only have Claude Code afaik.
And now they're publishing a blog post about writing their own vcs because they have 30000 commits a day. For what? Isn't Claude still based on react?
Do they need this many commits just for claude? Or is that about the model, do they develop that much extra internal tooling?
I admit it is very much possible I am wrong, but without further information this seems a bit like a red flag to me.
xyzsparetimexyz 3 days ago | parent
tintor 3 days ago | parent
esafak 3 days ago | parent
Practically speaking, it’s difficult to offer Scion in a form that would be broadly useful to other organizations. It diverges significantly from git, meaning companies would need to migrate every piece of the development lifecycle, and it requires its own code review, code search, and CI. Our internal versions of these components are highly bespoke, so they would be difficult for other organizations to adopt, and we worry that attempting to build a public version that tries to please everyone wouldn’t actually be very useful.
pbrowne011 3 days ago | parent
tetraodonpuffer 3 days ago | parent
---
Engineers are no less valuable, but their work is changing. All of the engineers who worked on this system would now rate Claude as better at writing code than them. But our engineers still supplied the invaluable understanding of the high-level inter-system components and the design-level tradeoffs, making informed choices around the problems we wanted to solve and the scale we knew we needed to achieve. Very often, we found that the role of the engineers was to tell Claude “no.” Agents will sometimes violate core system constraints to satisfy a pattern that should never have been allowed in the first place. This was particularly common in our migration. For example, there were multiple systems that tried to brute force looking up when a change merged to main by linearly reading the commit log instead of asking our code review tool. Anthropic also makes extensive use of adversarial review, and, while this is incredibly effective in many ways, it can also be myopic, so skilled engineers needed to steer Claude away from over-engineering parts of the system in response to hypothetical concerns. For example, one such review was overly defensive about trusting another internal service, which resulted in Claude adding excessive validation and complexity. Our team members still review every change request for the system, but they now examine the intent of the change as opposed to reading every line of code.
rfgplk 3 days ago | parent
> I am not sure however how easy it is to review 30k PRs/day even if only for intent, and how one can easily notice if the model is taking shortcuts on implementing said intent without reading the code...
Speed reading code is huge. You just need to focus on certain hotspots and know which things you're scanning for. The traditional approach of reading the code and trying to compile it or reason with it in your head is too slow.
tetraodonpuffer 3 days ago | parent
I do think that the lgtm gut feel looking at a PR requires quite some years of writing code and reason about it, so not sure how a junior can get that intuitive understanding if they start with agentic coding however.
springtimesun 2 days ago | parent
DenisM 3 days ago | parent
Personally I can easily imagine one or two orders of magnitude more than that. They crossed the rubicon of not gating PRs on tests. In that land you can just roll out changes to production, a small subset of it, during code review to assess behavior. Or during key moments of coding.
I’ve been thinking a lot about this recently: what can we get if every change goes to production in 100ms, and what do we need to do to maintain stability?
vitacoco 3 days ago | parent
Can please we all converge to 1 f'ng solution.
how does it compare to Epic's https://lore.org/ ?
firemelt 3 days ago | parent
rfgplk 3 days ago | parent
Another issue that I believe Anthropic here didn't state is that git performance _severely_ get degraded when you have hundred of commits landing in parallel. Hence why I fell back to the daily commit approach. You get less granularity but you get stability.
darlachaps 3 days ago | parent
Jagerbizzle 3 days ago | parent
alansaber 3 days ago | parent
aogaili 3 days ago | parent
If Anthropic has the best coding model, harness and the best software development methodologies and systems. And then, they scale all that up, with no constrains on their tokens. On top of that, they have access to all kind of ideas their models getting trained on when millions are chatting with it - then in theory they can build any software better than anyone out there. And same goes to science and math..
rfgplk 3 days ago | parent
aogaili 3 days ago | parent
But regarding the compute, I disagree a bit. I think the bottlenecks were cognition and ideas, not compute. Given that models are able to outperform humans in output by thousand folds, the differentiation would be the quality of the tokens produced and the ability to scale across different domains.
If they have enough compute to supply the entire globe, I'm sure they can redirect some of it to whatever use case they (or their super AI) deem worthy and loop on it, and if they have the best software engineering systems/methodology to build and release it, then they can out compete any other supplier without those resources.
We are already seeing single developers attempting to rebuild entire corporations history worth of output. We are also seeing the labs dumping hundreds of solutions to math problems.
alanwreath 3 days ago | parent
frangonf 3 days ago | parent
fasterik 3 days ago | parent
genxy 3 days ago | parent
All the others seem necessary. Maybe you don't need branches at all, of course we do! Things have to have names.
fasterik 3 days ago | parent
genxy 3 days ago | parent
There could be some fun cryptographic ways you could do it directly inside of git.
Kinrany 3 days ago | parent
nater5000 3 days ago | parent
For example, you can imagine, at the extreme, that agents could get caught in code change loops: a code change seems appropriate, it is implemented, it turns out there's some external factor which makes it not appropriate, the change is reverted, then that same code change seems appropriate again, etc.
Obviously you can prevent that from occurring with some extra infrastructure in-place, but at that point you're basically creating source control.
j45 3 days ago | parent
LadyCailin 3 days ago | parent
myhf 3 days ago | parent
caaqil 3 days ago | parent
Can you even do the latter without the former?
wongarsu 3 days ago | parent
Then again, my standard instruction is something like "{bug description}. Find the root cause and propose possible solutions" so I guess I fit your profile
genxy 3 days ago | parent
jcelerier 3 days ago | parent
rbehrends 3 days ago | parent
This is true, but at 30,000 merges a day we're talking about nearly 1 million merges a month, and purely autonomous agentic merges tend to be noisy. Is this still a tractable problem, even for an agent? Do revisions older than a few days, other than perhaps release snapshots, have any relevance for such a process?
hiq 3 days ago | parent
Of course that does require some folder structure, and agents are not necessarily great at that, but they're still decent enough that you do end up with many folders not being impacted hour or even daily.
rbehrends 3 days ago | parent
jacquesm 3 days ago | parent
locknitpicker 3 days ago | parent
I'd wage that volume of changes is not leading to forward progress, but is a clear sign of code churn.
This in turn is a clear tell they are dealing with spaghetti code.
derpyzza 3 days ago | parent
jacquesm 2 days ago | parent
nater5000 2 days ago | parent
At the end of the day it's "just" a management problem. If you can do something like, say, distill development activity into a hierarchical summary (i.e., this merge does "this," and these collection of merges do "these" things based on the "this" that each is described to do, etc.), then, with enough agents operating in parallel, I don't see why managing that isn't at least theoretically possible.
In practice this seems like a mess, but they're the ones with intelligence on tap lol
thwarted 3 days ago | parent
This is a great idea, now they just have to use/do it. Maybe they can use it effectively by cloning the repo and having all the history at hand, rather than continuously scraping web pages with git content formatted for human brwosing.
cowlevel 3 days ago | parent
njovin 3 days ago | parent
shironandonand 3 days ago | parent
denkmoon 3 days ago | parent
cowlevel 3 days ago | parent
avadodin 3 days ago | parent
It's the right approach if your business is selling tokens and the customer doesn't know any better.
hn_go_brrrrr 3 days ago | parent
Yizahi 3 days ago | parent
locknitpicker 3 days ago | parent
serf 3 days ago | parent
most of the harnesses are checkpointing most of the data of a git commit aside from the formal release and messaging, anyway; thats why they all have a similar problem with SQL dbs exploding in size after a bit of time.
Right now we're in this weird transition where most of the harness systems are layering git tool use w/ the constant snapshotting AND a memory subsystem often, probably leaves a lot on the table in saving wasted token use to just ditch the vcs all together and rely on the already persistent and existent checkpoints and memories for reconstruction.
weird-eye-issue 3 days ago | parent
Or code comments which they are already doing a lot of. I used to get annoyed by their verbose comments but at this point I've seen them help a few times and it's not like I'm actually maintaining the code myself anymore so it doesn't really bother me
fg137 3 days ago | parent
ghoul2 3 days ago | parent
singingtoday 3 days ago | parent
It works, but there is a significant amount of churn. I find when the swarms use git it's less churn and less token usage.
therealdrag0 3 days ago | parent
Betelbuddy 3 days ago | parent
0x20cowboy 3 days ago | parent
fooblaster 3 days ago | parent
a4isms 3 days ago | parent
Give it six months and there'll be have Optimus robots toggling switches to load terrabytes of binary programs directly into memory. Nobody wrote it, nobody will read it, but it will run everything.
nomel 3 days ago | parent
fsckboy 3 days ago | parent
that's not quite confirmation that assembly is source code
a4isms 3 days ago | parent
If you don’t feel that toggling the binary 16-bit words into RAM demonstrates that binary is what actually runs on the hardware, and that assembly is source code for a binary, well ok. I find it persuasive.
fsckboy 1 day ago | parent
machine code is a language.
they are isomorphic, but different. assembly language (source) converts to machine code (destination).
assembly is... source. code.
machine language is not, unless you consider vliw or microcode, useful to think about but doesn't extend the analogy already in place.
a4isms 1 day ago | parent
I never said otherwise. I think we're talking past each other, so I'm out.
lofties 3 days ago | parent
Betelbuddy 3 days ago | parent
orf 3 days ago | parent
From the post (especially the end) it seems that they are essentially letting software be fluid.
madrox 3 days ago | parent
I believe you're mostly thinking of version history though. There’s plenty of other reasons to have source control we still need, like guarding against racing writes or continuous integration to ensure correctness. Even some industries require version history for compliance reasons.
I do love how AI is challenging us to rethink our tools though rather than blindly reaching to git for every project.
kevmo314 3 days ago | parent
Pulling that off successfully at scale would be pretty incredible to watch.
yunnpp 3 days ago | parent
wongarsu 3 days ago | parent
We built all this tooling because it's useful. If you replace the human with an agent the tooling doesn't stop being useful. If anything it becomes more useful, since AI Agents excell at reading tool output but struggle with maintaining long-term state
kevmo314 3 days ago | parent
dlt713705 3 days ago | parent
pianopatrick 3 days ago | parent
antupis 3 days ago | parent
baq 3 days ago | parent
mrdependable 3 days ago | parent
this_user 3 days ago | parent
Quarrelsome 3 days ago | parent
So "no direct human supervision" seems like a misunderstanding. Article even bigs up the purpose of engineers with a hilarious (to me at least) line about auto adversial reviews resulting in over engineered designs.
frangonf 3 days ago | parent
I'm not saying that Anthropic here close their eyes and tell Claude to ship and that in the future there will be no code review at all, but that if we have 30K merges/day, human review seems to need to be done at some higher level, likely AI assisted like it seems to be done with their Antique code review tool mentioned in the post.
jwpapi 3 days ago | parent
klustregrif 3 days ago | parent
I know you are joking, but the answer is the same. Because the agents need it, not because any human need it. The Agents quite actively use the history. It's more effective than any comments or separate documentation might be for the agents working on the code.
sscaryterry 3 days ago | parent
baq 3 days ago | parent
nomel 3 days ago | parent
sscaryterry 3 days ago | parent
Do you think each and every one of those are going to be "good" commits, commits that still "compile" or function. Possible, but unlikely given the insane velocity.
Rudybega 3 days ago | parent
devy 3 days ago | parent
1. they have no-cap token spend allowance internally
2. their agent swarms are amongst the largest if not the largest, again because #1 above.
3. their git repo is enormously large (100GB uncompressed git history on main, 25GB compressed).
4. their merges per day count grew an order of magnitude from May to September to 30000 times per day, they are not seeing it slowing down anytime and probably only going to accelerate.
5. all of their code agents are networked and has network access, full local pull down is not needed at all and too slow (see #3)
6. their design of the Scion is based off prior art Google’s Piper and Meta’s Sapling.
Given their own constraints and characteristics of their own. It only makes sense to build their own homegrown solution based on prior arts. But this was NOT a complete redesign from scratch - so it's an full online download only what you need type of source control system. The problem is the version control software itself but its prior tradeoffs are misaligned with their scaling needs.
PS, if anyone noticed, Anthropic starts to concealing their employee full names and replaced with only first name + last name initiate, not sure why.
PPS, the project Scion is so bad, scn is worst, it reminds people of prior SVN, which is bad by itself.
demaga 3 days ago | parent
I might be completely out of context, but why is it only 4x compression? Do they commit a lot of binaries? I just don't understand why would code compress so badly.
quuxplusone 3 days ago | parent
saghm 3 days ago | parent
mike_hearn 3 days ago | parent
reverius42 3 days ago | parent
mike_hearn 3 days ago | parent
I mean 30k CLs per day isn't much. That's one every few seconds. Well within what a decent perforce setup can do with enough replicas.
bionade24 3 days ago | parent
reverius42 3 days ago | parent
mike_hearn 3 days ago | parent
StilesCrisis 3 days ago | parent
jeffbee 3 days ago | parent
mike_hearn 3 days ago | parent
It's always a question of opportunity cost. The culture that led to Piper also led to them creating their own IDEs and everything else, often with questionable outcomes. Google had the profitability to get away with that kind of profligacy but do the AI labs really want to go the same route?
gritzko 3 days ago | parent
StilesCrisis 2 days ago | parent
Cider and Cider-V were both forks of existing IDEs with Google-specific stuff wedged in. They weren't greenfield projects.
Blaze was absolutely worth it. Nothing else comes close.
I'm sure not _every_ tooling project was a win, but I don't think it's fair to frame it as "every Cider engineer could have been ramping up remarketing and advertising instead." Google's early days involved trying everything and keeping what worked. The tooling improvements worked.
mike_hearn 2 days ago | parent
But... there's a lot of decisions that make sense for a company like Google or Meta that don't make sense for other companies. Google, Meta, Apple and a few others like them are nearly unique. They have extremely profitable quasi-monopolies that have proven impregnable to competitors, and the second price auction system they use automatically sets prices to whatever the market will bear.
Thanks to that they they can pay enormous salaries, fund many high risk/low ROI projects and still have lots left over. In such an organization projects like creating your own build system, VCS, IDEs, email system and so on can be rational, even though they can't actually measure the productivity impact of a developer tool to one percentage point of precision.
All this is nothing like normal business. Normal businesses face peer competitors, meaning pricing is under continuous downwards pressure. Across all industries the profit margin is only 10%, but that's an average that includes the tech sector. Industries with a lot of competition stabilize at margins around 3% e.g. supermarkets or airlines.
When we look at AI labs, what do we see? They spend like they are Google, but the market they're in looks nothing like ads or SaaS. Instead they are in vicious competition selling largely undifferentiated products to price sensitive customers who display almost no brand loyalty. Quite surprisingly to those of us who got used to the FAANG and SaaS era, AI firms look more like airlines than tech firms.
In normal companies the rules and culture are totally different. Decisions are driven by people with MBAs who use terms like "core competency", "outsourcing" and "margin compression". In-sourcing is rare because it's expensive and risky. If your margin is only 3% then you don't compete with your own supply chain unless it's absolutely required. Doing that without a shit ton of spreadsheets showing it's necessary is the sort of decision that will get you fired, pronto. You use things off the shelf. If nothing is available for free then you're expected to spend months in vendor negotiations trying to squeeze another 5% off the contract, and this is the kind of work valued in such a culture which is why MBAs rise to the top.
Historically the software industry has avoided this because of ads, the ZIRP era, lock-in, the explosive growth of VC up to 2017, and low growth in other sectors like pharma. But that era could never last forever and seems to be ending now. A strong signal is the growth of Bending Spoons, whose business model can be summed up as buying SaaS companies run by people who can't psychologically handle a high interest rate environment and then just running them like a normal business.
I realize acutely that the reason I don't run a top tier AI lab is because of this mindset, but if I were running Anthropic I'd be trying to find ways to cut costs dramatically. For a decade+ you never heard the words "tech startup" and "bankruptcy" together in a sentence, partly because VC firms forced firms to acquihire startups that weren't working out, making failure look like success. But this week Character.AI went into Chapter 11. None of us know the true figures but it looks like AI firms don't have the margins to justify acting like a Google or a successful SaaS. Corporate cultures imported from those companies risk blowing everything up.
StilesCrisis 1 day ago | parent
mike_hearn 1 day ago | parent
StilesCrisis 22 hours ago | parent
adonovan 3 days ago | parent
mike_hearn 3 days ago | parent
Also IIRC from the original 2011 Perforce admins paper before Piper, they said they had seriously overspecced the RAM and could use a lot less. There's an annotated copy here: https://www.anantjain.xyz/posts/perforce
jasobake 3 days ago | parent
hilariously 3 days ago | parent
james_marks 3 days ago | parent
Gives me a vaguely creepy feeling, but it's reasonable.
usefulcat 3 days ago | parent
astrobe_ 3 days ago | parent
zer00eyz 3 days ago | parent
For how the Linux Kernel, a highly decentralized, completely open source project, with a single monotonic product, tyrannically lead (a good thing) - is developed.
Permissions, Partial Checkouts, Sub Repos, Vendoring, pub/sub... How many companies bought into git and then had to buy more tooling (like artifactory) because their 3rd party dependency's needed a home. Thats a feature that git does not support because git, as designed, did not need it.
Think about how much better your life would be if every time you typed npm,pip,goget,cargo it fetched THROUGH your repo. If those updates triggered code reviews of whatever changes you're going to consume. You are code reviewing those updates aren't you (someone is, cause supply chain attacks don't last that long)
Git has some weak points, Google doesn't use it for a reason. Epic created lore for a reason, This exists for a reason. Im not sure that any of them are the next thing that replaces GIT but it's getting to be time. Tools like this are going to keep popping up till someone gets it right.
m4rtink 3 days ago | parent
de-moray 3 days ago | parent
There are orgs that are moving to not including names at all as the next step on that trajectory.
locknitpicker 3 days ago | parent
Does it, though?
What problem do they actually have that requires redesigning a whole new vcs?
Merge conflicts? That's not exactly a vcs problem but a "we changed the same code at the same time" problem. No tooling on earth eliminates the need to verify conflict resolutions if agent A renames int foo to int bar while agent B renames int foo to int baz.
Growing repo size? They should take a long hard look at what they are doing. How is their software architected? Is every single little change and half-baked AI churn commit pushed to the main repository, or does the main repo only receive the deliverable? Is everything under the sun tracked in a mono repo or are projects stored independently?
Do they take any precaution at identifying churn and taking steps to minimize it?
Frankly, this reads like a bullshit PR stunt, much like the bullshit curl vulnerability findings. They have a self-inflicted problem, and their solution is to persist the problem and mitigate the problems by rolling out ad-hoc tooling? It reads like "if all you have is a hammer" kind of situation.
deadbabe 3 days ago | parent
This is how we solve cybersecurity, by making code into constant shifting sand, so a vulnerability never truly lives long enough to be exploited at scale. Sure, a hacker may occasionally pick out a vulnerability like a bear picks salmon out of a river, but it makes larger scale cyberattacks impractical. The code is a firehose, constantly in flux.
genxy 3 days ago | parent
aworks 3 days ago | parent
xpct 3 days ago | parent
jerf 3 days ago | parent
This doesn't make everything secure. It turns the universe into what we see in Star Trek, where everything is hackable all the time by everyone just by trying hard enough, or, in the real world, spending enough. A lot of the utility of hacking systems can be obtained in running off with the data so the inability to use a break tomorrow is not necessarily a problem, especially if I just ask my magic code fairy for another break tomorrow and the remote system has, to a first approximation, learned nothing from the previous breach as it busily churns away.
This is not the way. In fact for secure software I'd happily testify in court as an expert witness that this would be criminal negligence.
As for how closely it matches what Anthropic is doing, no comment. I'd need a lot of time to look at that and decide. That they can write code easily I do not question, whether they have 100GB of problems or 2GB of problem and 98GB of garbage that is slowing down even their AIs is not something we can get from a happy PR puff piece. I'm just speaking to the idea of letting code mutate wildly and constantly.
gorgoiler 3 days ago | parent
The big baddies of build have worked this way for a long time already. Git surfaces a single Merkle tree id for the whole repo on each commit, but build tools like bazel/blaze, buck, pants, et al look at hashes of subtrees and use cached artifacts for the parts of the tree that didn’t change.
Your CI no longer becomes a binary signal on the code and more of a continuous signal on how much your “this works” pointer has caught up with your “this is the latest code” pointer.
mikebiglan 3 days ago | parent
That is, the deterministic part is the platform that is being built and that non-deterministic agents will use and build it, but that layer is a key part of how they do work and will continue to be.
suopspaces 3 days ago | parent
ozim 3 days ago | parent
AndrewKemendo 3 days ago | parent
In fact most of the architecture work I’m building, assumes that there will not be a human reading code, they read (effectively) UML and data diagrams
so most of the interesting parts I’m working on now are how do you make code blazingly fast, formally verified and memory safe if you remove the constraint of human interpretability of machine instruction
drcode 3 days ago | parent
dietr1ch 3 days ago | parent
There's lots to improve in how we handle code, and losing the agreement on what the codebase even is sounds like an awful regression.
ai-x 3 days ago | parent
They can just analyze PRs and diffs without loading the entire 10,000 line file.
Also, anti-AI folks really have a fundamental misunderstanding of how everything works in the LLM world and is probably why all their predictions are wrong
Fordec 3 days ago | parent
All of this may be slightly inspired by the Militech neural matrix in Cyberpunk 2077
post-it 3 days ago | parent
A big motivator of thinking architecture through really well is that although the software may work just fine now, a good architecture will make it easy to add a feature a year from now, whereas a bad architecture will necessitate significant rewriting.
But significant rewriting is cheap nowadays, so in code reviews I put a lot more weight on whether it works today, and a lot less weight on whether we'll need to change it when making a different change.
Entire classes of things like "should this be in this component or split out into its own" just don't matter anymore because no matter how tedious changing that might be once there's a ton of things depending on it, that's the kind of thing AI can do no problem.
GrinningFool 3 days ago | parent
I tend in the other direction when I can (for components and microservices - harder for monorepos): I encourage refactors on a continual basis, as it prevents the models from getting bogged down with the way the system used to behave across changes.
xyzzy123 3 days ago | parent
I also found though, with agents you can quickly create large amounts of code, when you go to refactor / fix some design aspect that touches large parts of the system this consumes a lot of tokens and actually still takes meaningful time.
It's like, with a digger you can quickly create a hole! Digger can quickly clean up the work of 10 people with shovels! But if you use a digger for 1 week and you were putting the dirt in the wrong place, you find you have a HUGE pile of dirt to move and will still take a long time to clean up.
Directionally I agree with you, but I think design still matters.
jimbokun 3 days ago | parent
x0_Dev 3 days ago | parent
Fordec 3 days ago | parent
whatever1 3 days ago | parent
Kinrany 3 days ago | parent
whatever1 3 days ago | parent
Kinrany 3 days ago | parent
whatever1 3 days ago | parent
At 00:00:00 utc you take a snapshot of the code deployed to all your machines (if different code was deployed in different machines then it is part of this capture).
That is the unambiguous code state of your production system.
There is no conflict in a prod state by definition. If there was it cannot be prod.
jacquesm 3 days ago | parent
locknitpicker 3 days ago | parent
If your code changes are all over the place, touching half the repo and stepping on everyone's toes, your problem is not the version control system. Your problem is your changes, and the mess you are leaving in your wake.
LudwigNagasena 3 days ago | parent
jimbokun 3 days ago | parent
ur-whale 2 days ago | parent
The whole thing, including ingestion and review, is not meant to be used by humans.
This is the shared memory / history of a horde of coding agents.
mey 3 days ago | parent
stigi 3 days ago | parent
hxugufjfjf 3 days ago | parent
josephscott 3 days ago | parent
orangecat 3 days ago | parent
tasuki 3 days ago | parent
jauntywundrkind 3 days ago | parent
It's designed for container running, but ArtifactFS has some similarity in principle to me. The on-demand materialization. Quote: ArtifactFS is a Git-backed filesystem daemon (FUSE driver) in Go that mounts repositories as normal working trees while avoiding eager blob downloads. https://github.com/cloudflare/artifact-fs
I threw together my own jujutsu powered FUSE subtree project just the other night. This was basically one-shotted, just to see how it does it, to learn more, not really intended for use. But obvious overlap. https://github.com/rektide/jj-workfuse
nojs 3 days ago | parent
hollerith 3 days ago | parent
simonw 3 days ago | parent
Here are the public model releases from Anthropic this year:
5th Feb 2026: Claude Opus 4.6
17th Feb 2026: Claude Sonnet 4.6
7th Apr 2026: Claude Mythos Preview
16th Apr 2026: Claude Opus 4.7
28th May 2026: Claude Opus 4.8
9th Jun 2026: Claude Fable 5
9th Jun 2026: Claude Mythos 5
30th Jun 2026: Claude Sonnet 5
24th Jul 2026: Claude Opus 5
1st Sep 2026: Claude Fable 5.1
1st Sep 2026: Claude Mythos 5.1
22nd Sep 2026: Claude Opus 5.5
28th Sep 2026: Claude Sonnet 5.5
7th Oct 2026: Claude Haiku 5.5
I would guess that any public model has been available internally for at least a month before that date, maybe longer.
My best guess is that the uptick in code changes corresponds to the availability of Mythos/Fable-class models inside of Anthropic.
enraged_camel 3 days ago | parent
Yeah. OpenAI basically said the same thing with regards to having Astra available to their team internally over the summer.
simonw 3 days ago | parent
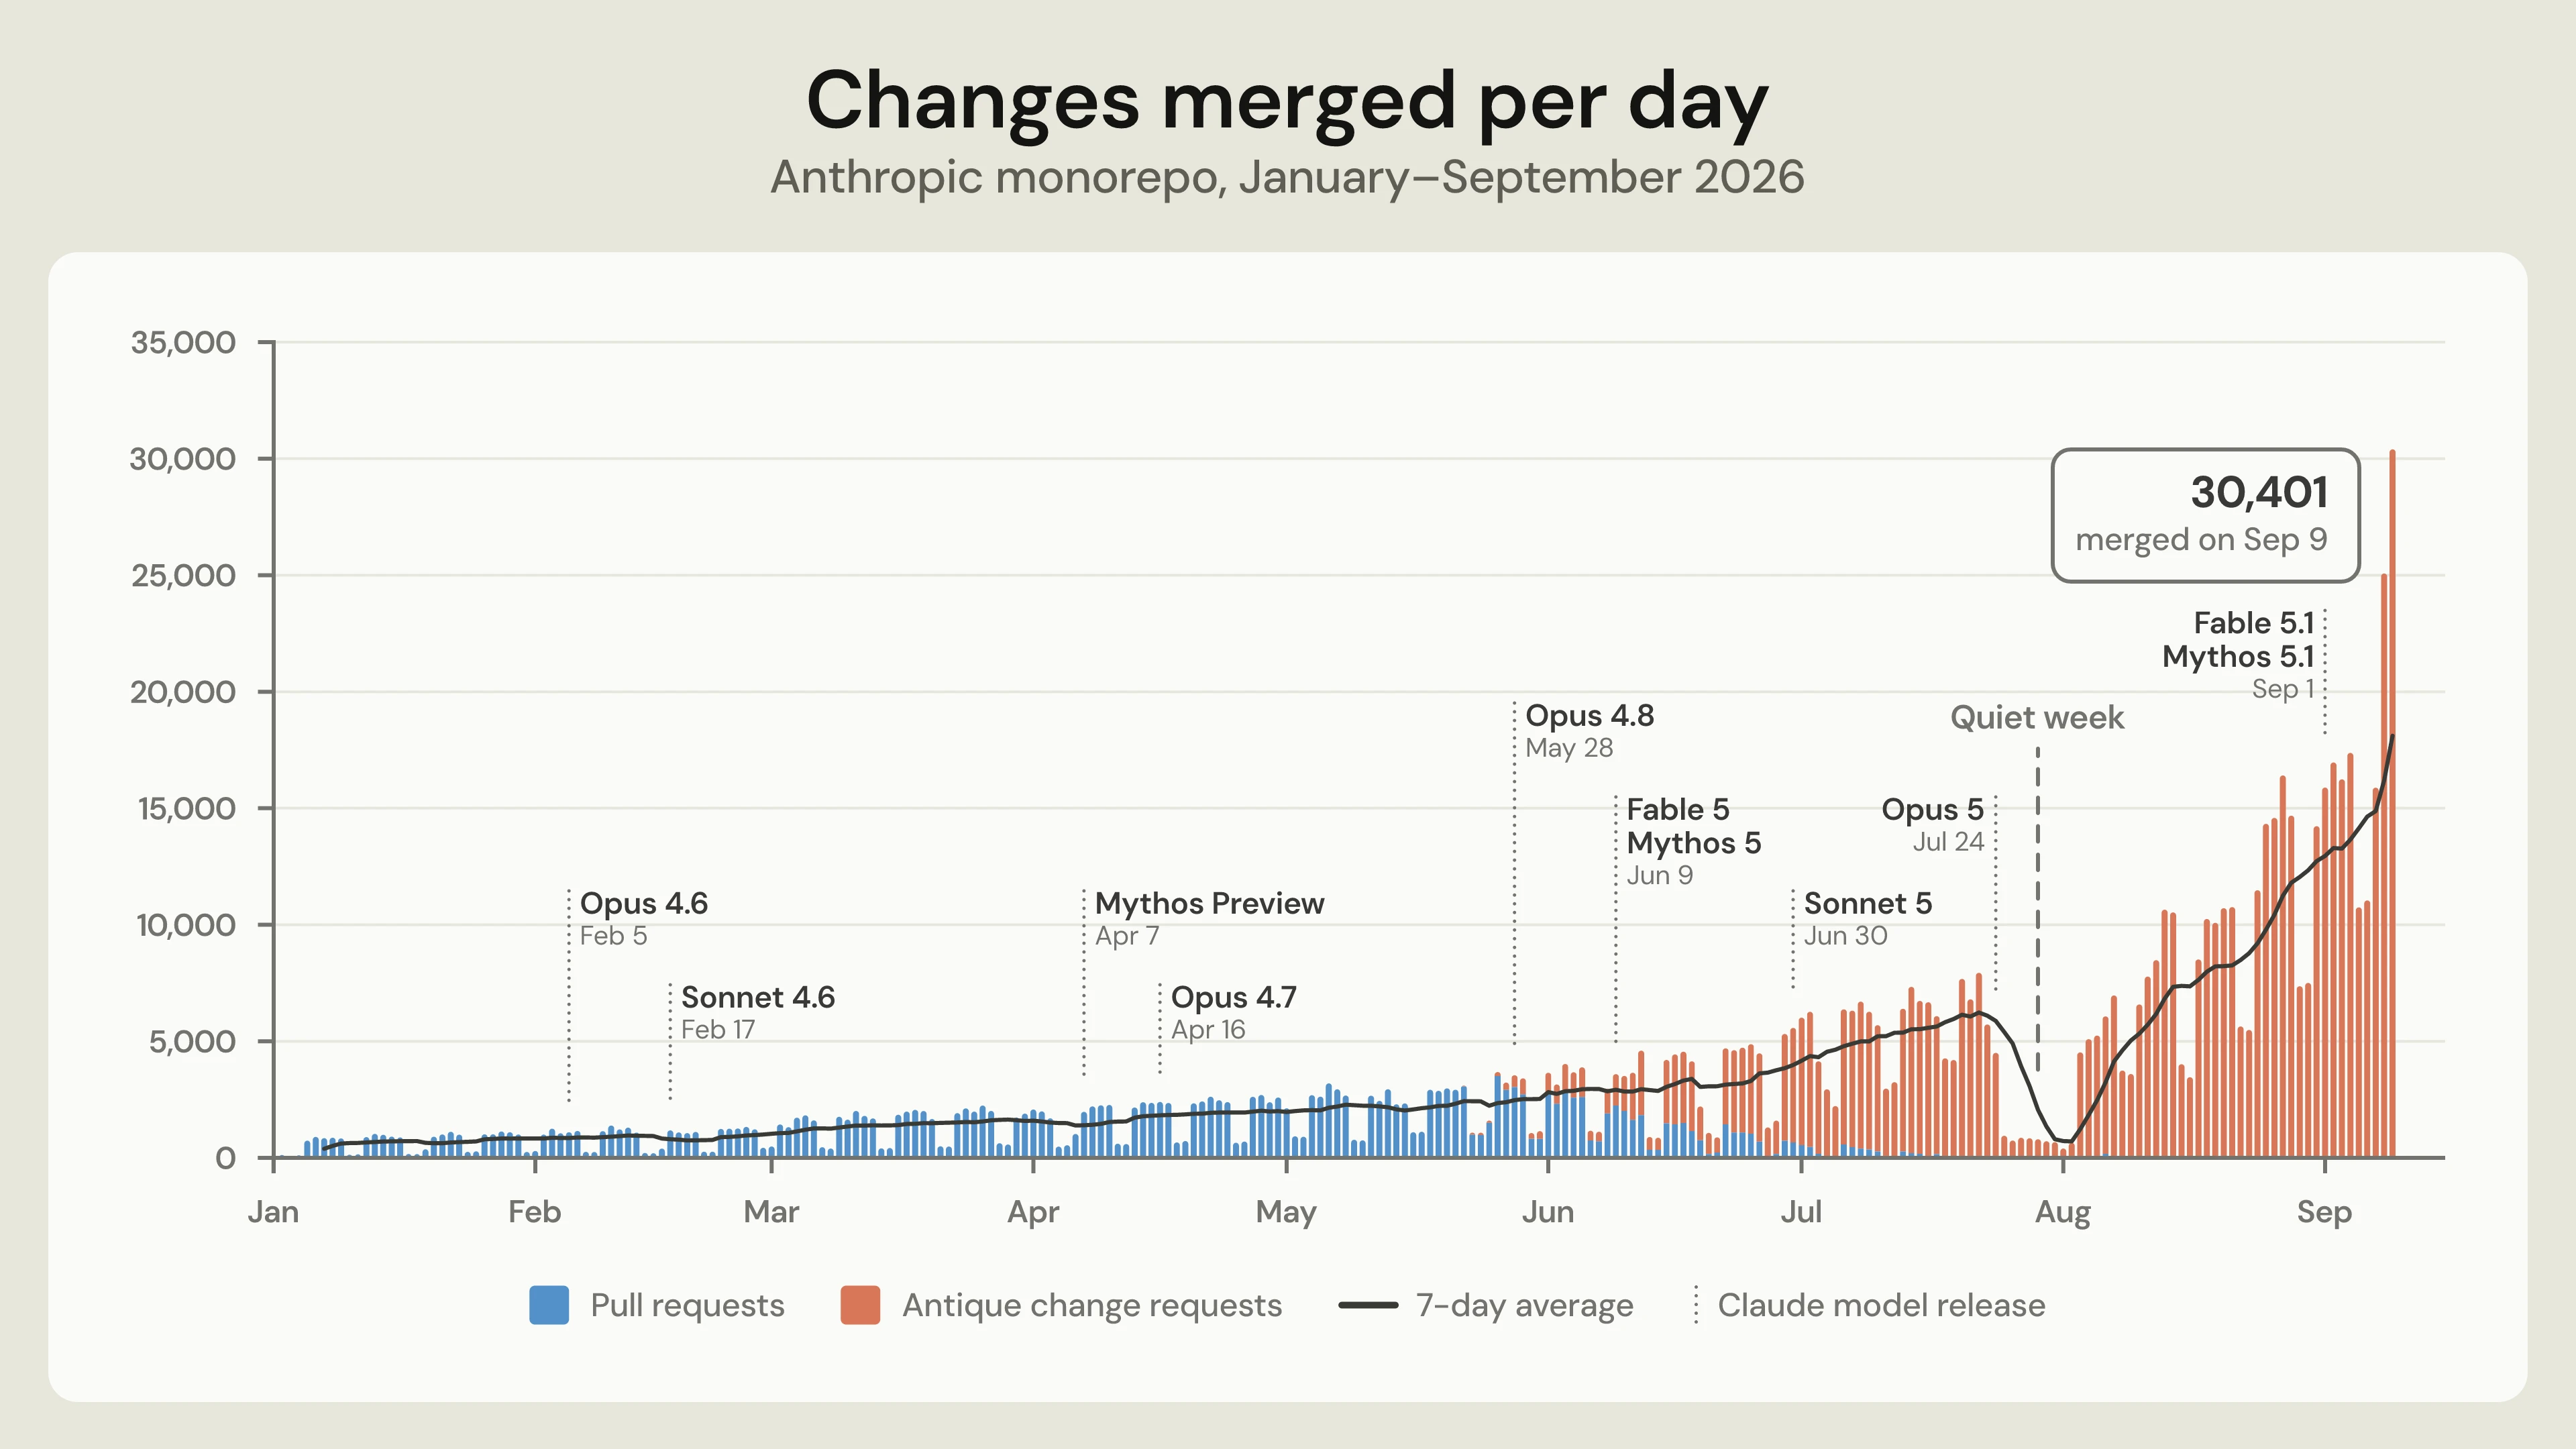
dilyevsky 3 days ago | parent
philipwhiuk 3 days ago | parent
It's also hard to believe all these non-Git alternatives aren't merely an attempt to capture developers into a new proprietary solution.
This could have been done as an open-source fork of Git.
jabedude 3 days ago | parent
nico 3 days ago | parent
zactato 3 days ago | parent
Most companies don't use mono-repos like this. While there are some really compelling advantages, the downsides tend to stack up as a company's codevbase grows.
It's mainly just startups and huge companies. For small companies git works fine for mono-repos and large companies can build their own complex code management pipelines for mono-repos.
I have been questioning whether agentic development changes the mono-repo vs multi-repo question.
ChrisLTD 3 days ago | parent
InvisibleUp 3 days ago | parent
netburst 3 days ago | parent
> ..., the latent demand for merging code is practically infinite, and every bottleneck we remove immediately leads to a further increase in the amount of code we produce.
If the goal is to write software which solves real problems, how can the demand for code grow infinitely?
ciconia 3 days ago | parent
yoyohello13 3 days ago | parent
It seems to me like the AI labs are just pushing the envelope with blind faith that”something” will happen if they just get enough development speed. Nobody seems to have a coherent idea of what that something is.
marknutter 3 days ago | parent
daveguy 3 days ago | parent
xyzsparetimexyz 3 days ago | parent
I took a photo of a tree with chatgpt recently and asked it what species it was. That was kinda neat I guess. Someone forked a ps4 emulator with a bunch of Bloodborne specific improvements so its more playable on my setup. It's kind of okay for medical stuff.
ex-aws-dude 3 days ago | parent
freecodeio 3 days ago | parent
Yeah I wish this whole energy was towards optimization and improving hardware.
One thing that people are finding hard to believe is that the frontier labs are cultists who want to "create god". Hence the focus on improving intelligence so they can get to recursive AI, as well as the fear-mongering.
Aanthropic-openAI duo cannot go bankrupt soon enough. This industry is going to flourish with those two out of the picture. They're the pets.com of 1999 trying to have a say how the internet should be.
TeMPOraL 3 days ago | parent
Have you considered they are doing that, and also all the other things, too? That's where all these tokens go.
But I guess it's easier to believe they're all cultists who like to watch GPUs spin for no reason.
jrflo 3 days ago | parent
All that busy work was for going from zero revenue to $50B in revenue in about 3 years, and releasing AI systems that are getting better and better at a ridiculous rate. AI isn't solving all the world's problems but you can't deny that they are extremely successful with this method of operating.
billyp-rva 3 days ago | parent
jrflo 3 days ago | parent
I definitely think that's an interesting question though. I know that in the physical product development world I'm seeing really odd asymmetric speed ups. Creating simulations is essentially automated at this point, stuff that would take days to code by hand can be done in an hour. Firmware debugging feels 3x faster than before. But the big slow stuff like manufacturing, assembly, and testing are completely unchanged. All of that little stuff probably adds up to maybe a 5% faster product development cycle than before if you're really leaning into AI. It's the type of thing that will compound over time especially if it's happening all over the economy, but won't blow your socks off.
0conclusive-dem 3 days ago | parent
bowsamic 3 days ago | parent
overgard 3 days ago | parent
jrflo 3 days ago | parent
There are definitely risks to their business long term from commoditization and a lack of a moat, but I don't think that detracts from my original point that they are building something highly desirable with this new version control system today. They are probably the fastest growing company of all time in terms of revenue and valuation? They're not just slopping out more and more LOC for no reason, which was the original point being discussed in this thread.
stephen_cagle 3 days ago | parent
"A world where starting is incredibly easy and finishing is more complicated than ever"
LLM's do allow you to oneshot huge starting bits of work in record short time. The frontier of the amount of work they can oneshot is clearly getting larger and larger. But I am still not convinced that they allow you to maintain existing work at a cost that is below a human being.
But, if the frontier of what you can oneshot continues to grow unbounded, then it really will not matter. We will eventually oneshot all software and maintenance will be a thing of the past.
... But that is a very big bet.
bowsamic 3 days ago | parent
Wazzymandias 3 days ago | parent
godwinson__4-8 3 days ago | parent
Who decides what the "real problems" are?
Imo most of the economy and wealth creation is around activity that is not solving a "real problem", but who am I to say if someone else is willing to pay for it? Presumably, for said person, the problem is "real" enough.
crabmusket 3 days ago | parent
You are a moral actor capable of rational thought. The very image of God themself, if you like. Don't shrug off your own agency.
godwinson__4-8 3 days ago | parent
Completely unnecessary. Secular humanism for me, thanks.
bowsamic 3 days ago | parent
dang 3 days ago | parent
"Don't be curmudgeonly. Thoughtful criticism is fine, but please don't be rigidly or generically negative."
"Don't be snarky."
https://news.ycombinator.com/newsguidelines.html
There's plenty of room for thoughtful criticism and skepticism in HN threads, including the present one, but please don't post like this.
stephen_cagle 3 days ago | parent
If you are constantly churning your codebase to the point that you need to invent a system that handles your churn... then you must at least be admitting that the previous 6 refactors you wrote were not good, but NOW you have it right.
I feel that good, well designed code change by accretion, not by rewrites. Code that remains stable for a long period of time was likely better than code that needs be continuously rewritten (at least with humans writers).
But maybe this is just a human-centric view of what good code means? That LLM "slop it until it works" approach to development will have a different measure of what quality looks like?
jitl 3 days ago | parent
i really don't want to brick my camera, so the deterministic emulator stack lets me do integration tests end-to-end. if i was doing this by hand with no ai, i'd probably have to run stuff on the camera just to test it. but because ai, i get deterministic simulation testing, at the cost of needing to burn $100 of subscription on it.
ai code is more like clay you gotta continuously keep shaping over time, but you can also get very very far, very quickly if you decide the code itself doesn't matter and all you care about is results.
stephen_cagle 3 days ago | parent
Similar to your camera, we would never have been arsed with doing that much work were it not for LLM vibbing. It allowed us to get something working (sufficiently) very quickly.
At what point of maintaining this code would it be cheaper for me to actually find underlying patterns and program this myself with some actual thought, rather than continuously "shaping the clay" of my LLM slop? These questions keep me awake at night (not really), and probably predict the future of software engineering!
atlanticaccent 3 days ago | parent
Because asset-ripping is a pretty widespread, well documented practice in gaming - it's how a lot of modding communities figure out and expand on the games they mod.
A quick search shows WH40K: Rogue Trader is built on Unity too, so any number of existing Unity-specific asset-ripping tools should have worked for your purposes. Though I should say I've never actually dabbled much with modding Rogue Trader, so maybe I'm wrong?
stephen_cagle 3 days ago | parent
We also just wanted to try some modestly sized project with an LLM. Neither of us had any real experience doing any of the things we ended up doing for that project (other than my making the website and him understanding the graphics pipeline).
So, unfortunately, no, there was no specific reason I suspect.
https://stephencagle.dev/posts-output/2026-01-30-warhammer-4... is my best recollection of the thought process.
dolmen 1 day ago | parent
jacquesm 3 days ago | parent
What does that remind me of?
TeMPOraL 3 days ago | parent
code-delta-app 1 day ago | parent
anal_reactor 3 days ago | parent
Imagine that you have git but you don't even have a concept of programming language more complex than assembly. All your commits and git history are pure assembly. Everything is cool, until one day C++20 randomly spawns into existence, and a bunch of guys decide to use it in the company. The issue is, the compiler generates so much assembly, that your existing workflow cannot keep up with it. Your assembly git repo grows into hundreds of gigabytes, with PRs that are pretty much complete rewrites coming every single day and there's no way to review any of that shit.
What Anthropic is doing is redoing git from scratch so that it can handle all that assembly, while the correct thing to do is to commit C++ code into the repo, with deep trust that you'll never hit a bug in the compiler - basically impossible for initial versions of compilers, taken for granted nowadays.
What I'm saying is, Anthropic should create a versioning system for prompts, because they are the true "source code". Given the same prompt and the same sequence of random numbers, LLM will generate exactly the same code, which sounds awfully close to how compilers work. Once in a while put the generated code as a point of reference+ caching and presto.
krial 3 days ago | parent
dpark 3 days ago | parent
The input to this is not just the preexisting code, the prompt you provide, and some random seeds. It’s also the output from every single tool invoked, which means you need to record the state of every single tool and every file that was read, every API that was called. It means that you can’t upgrade Claude. It means that you can’t upgrade the compiler. If you change anything in the state of the world you no longer have replicability.
Aside from all that, I don’t know why you would want this anyway. Storing a bunch of prompts doesn’t seem to actually gain anything even if it worked.
sigbottle 3 days ago | parent
Bad analogy, cause this is not how tooling works. Tools beget more tools - there's value in specifying "these are the sets of tools we need to make", but unlocking new capabilities doesn't happen unless you... make the tools. And use them. And keep them stable. And watch them break, or become obsolete, and build on top of that. The world has state and path dependent.
cheema33 3 days ago | parent
If LLMs were deterministic, like compilers, you would have a point.
otabdeveloper4 3 days ago | parent
marjann 3 days ago | parent
overgard 3 days ago | parent
The only thing I can think is that they're doing a google style mono-repo, which like, fine, that's a thing to do, but I really have trouble picturing that changing code at that rate is a useful thing to do.
podgorniy 3 days ago | parent
fireflash38 3 days ago | parent
samspot 2 days ago | parent
From the first paragraph: "Claude is able to autonomously iterate on research loops, micro-optimize complex programs, and build new services from the ground up at a speed and scale we haven’t seen before. The bottleneck, now, is all of the developer infrastructure built for human scale: source control, builds, and CI."
barsandtones 3 days ago | parent
j45 3 days ago | parent
I appreciate it's different than git, that type of argument for monorepos is not new.
Agents coding is akin to having a very large developer team, who may or may not be online 24/7.
Anthropic is calling it very specialized, and it's a little baffling.. maybe I'm missing something.
There's no way software development is the same anymore. The previous ceremonies and structures and seats at the table at each stage were human based, and now that's a different make up to the point that different steps and processes are needed.
There's nothing more fundamental to growing software development other than making tools like this available.
My hope is a vibe coded internal mono repo management tool can aim for a v2 with multi-tenancy built in.
Was anyone else looking forward to feature flags as a part of a post like this?
DenisM 3 days ago | parent
I am looking for agent-world feature flags, but not in a post on source control. Feature flags belong to wider SDLC.
status_quo69 3 days ago | parent
tancop 3 days ago | parent
cube00 3 days ago | parent
You think you have it bad now when GitHub goes down, wait until you're stuck with an online only client.
scottyah 3 days ago | parent
hippycruncher22 3 days ago | parent
dingaling911 3 days ago | parent
ActionHank 3 days ago | parent
This is the weirdest part, because you know, coding is solved, so anyone could create their own one, so why not publish it?
flakiness 3 days ago | parent
choochutrain 3 days ago | parent
And by the way things are done at this company, it's almost a given their whole codebase are litter'd with embarassing shit like hardcoded paths, server secrets, weirdo comments picked up from some random chat context and immortalized through Claude speak, etc. There's no way they'd be able to open source anything.
But all of this is besides the point -- the product was never a source control system (who cares about that anymore?), the product is _the narrative_. It does not matter if everything withers and dies as long as the narrative survives, and by that measure I'd say the goal has been achieved.
fnordpiglet 3 days ago | parent
Most big tech have a lot of stuff around SDLC that’s theirs and they couldn’t realistically release it given how specific its deployment, configuration and management is. The marginal benefit to generalizing it is so low that it’s negative.
This is almost certainly worse given the vibed out state of it.
Fordec 3 days ago | parent
Imagine waking up next week and Claude Code now ships free with builtin source control management via this tech with a better user experience than workspaces. Github and Microsoft would take an instant market share hit in the traffic that they swear is causing all of their outages. And then that cuts off Microsofts access to code to train their own LLMs on in the background, further hampering an Anthropic competitor in the AI race.
rsalus 3 days ago | parent
Fordec 3 days ago | parent
fnordpiglet 3 days ago | parent
Fordec 3 days ago | parent
rixed 3 days ago | parent
They can still do that without releasing the code, can't they?
Fordec 3 days ago | parent
jimbokun 3 days ago | parent
crystaln 3 days ago | parent
Making a complex system like this available for general use cases, especially when it's still under active feature development, is hard. It also commits you to providing documentation, upgrade paths, incorporating changes that aren't useful to you and may also cause problems for you, and just generally complicating development and maintenance immensely to the point of drastically slowing development.
My guess is when it's stable or they start building their next version control system, they will start opening it up.
I know especially in this day and age when developing from scratch is so easy, I write most software for myself first and it's way faster to develop than trying to build shared bits. That isn't great for the future of software, however the tragedy of the commons isn't anyone's problem, by definition.
htrp 3 days ago | parent
jaggederest 3 days ago | parent
I'm not fully sold either way yet but I think splitting might actually be critical for moderating the blast radius of agent intervention.
stackedinserter 3 days ago | parent
2001zhaozhao 3 days ago | parent
Maybe I should just bite the bullet and use a different VCS system entirely once I get there, which has most of the Anthropic system's properties (including being much faster) but doesn't need to be horizontally scalable.
herpdyderp 3 days ago | parent
vb-8448 3 days ago | parent
I just wonder what is the churn rate (and the cost per LOC) here.
altcognito 3 days ago | parent
> 25 million CI checkouts
833 checkouts for every merge? That's quite a few. Even accounting for multiple environments at different stages of production readiness, that's pretty weird.
malfist 3 days ago | parent
altcognito 3 days ago | parent
And actually, the lack of an artifact server and some sort of proper knowledge of compatibility requiring a CI pull across hundreds of different projects with every merge is probably the explanation. Seems like there is an innovation waiting to happen there.
rhdunn 3 days ago | parent
I also have a template repository I use to help with common setup for different project types so I don't need to repeat that every time I create a new project.
For Python it's easy to create an artifact server as the artifacts are just wheel files in a directory with the server listing the directories (packages), files (releases), and downloading the files.
I'm not sure about other artifact servers for other projects.
xyzsparetimexyz 3 days ago | parent
nickg-anthropic 3 days ago | parent
Goto80 3 days ago | parent
Oh, it's not available, what a pity. Why write a whole article about a thing no one can have? Maybe the code isn't so great after all? Or it's all just made up and doesn't even exist?
Anyway, this is yet another pointless ad from Anthropic trying to shill their AI on us.
mixedbit 3 days ago | parent
enjoyyourlife 3 days ago | parent
jakeydus 3 days ago | parent
ButlerianJihad 3 days ago | parent
However, I can tell you someone who fits all those criteria: Levi Strauss. Strauss founded a company to sell dry goods, as well as tents and jeans, and eventually specialized in those denim jeans. Levi Strauss became a household name and an enduring success of the Gold Rush.
Therefore, I say that this motto is flawed; so let's correct it: "In a gold rush, sell the work clothes!"
bradleybuda 3 days ago | parent
springtimesun 3 days ago | parent
__xor_eax_eax 3 days ago | parent
ForHackernews 3 days ago | parent
ButlerianJihad 3 days ago | parent
You’ve desperately tried to call me out and flag me at least 3 times now.
You do not know what a neural network is? Do you know what a neuron is? Do you… possess any neurons?
On a forum where the most favored pastime is to call out stuff you don't like as “slop”, (a flaggable ad hominem) you are now taking pride in outing me somehow, as someone who describes exactly what I'm doing, publicly in my profile?
And in the process, you (and apparently, an entire flag-it brigade of ignorant motherfuckers) have publicly fallen for the most transparent and avoidable trolls in cog. sci. culture. Congratulations, mate!
I believe that you owe me an apology, along with a public retraction, and an unflagging of all the previous comments that you have falsely flagged on false pretenses and ignorant, petty, vindictive motives.
badosu 3 days ago | parent
ForHackernews 3 days ago | parent
Your output is both verbose and tendentious in a way that suggests artificiality. If I'm wrong, I apologise and I will unflag.
marknutter 3 days ago | parent
zeroonetwothree 3 days ago | parent
whatshisface 3 days ago | parent
barumrho 3 days ago | parent
freecodeio 3 days ago | parent
rurp 3 days ago | parent
IshKebab 3 days ago | parent
cheonic4040 3 days ago | parent
The good ones do.
Citadel Securities, Renaissance, Jane Street, HRT, Jump, consistently do 50%+ annual returns over the past 15-20 years. They obviously don’t accept outside investor money.
Now, hedge funds that accept outside money like DE Shaw, Bridgewater and shit, yeah, they barely outperform S&P500 after their fees.
Then at the bottom, you have financial advisors who underperform S&P500 after their fees, but these advisors provide emotional support, so that’s what you’re paying for.
reisse 3 days ago | parent
That is only if you consider high-frequency trading investing. Which is very hard to, because on traditional investing timescales HFT is delta-neutral.
altcognito 3 days ago | parent
I mean, there isn't any evidence other than heresay.
cheonic4040 3 days ago | parent
3x leverage on VTI/VOO yields 20% annual return over the past 30 years.
Even you, a passive index fund investor, can do this in your Schwab/Fidelity account.
Now consider algorithmic prop trading firms with 10x, 20x leverage. You do the math.
For reference, most people take 5x leverage on their house (20% down payment).
_se 3 days ago | parent
solenoid0937 2 days ago | parent
You don't buy a hedge fund because it outperforms the S&P, that's just a bonus. You buy one because it has better returns for a given level of risk, and because the returns are uncorrelated with the S&P.
ilio 3 days ago | parent
Because fees as a manager of someone else’s money can be higher than the full amount of the returns if it were just your own money.
Fees on someone else’s capital: 1% of 20% of 1bn = 2m
Returns on your own capital: 20% of 1m = 200k
erfgh 3 days ago | parent
tantalor 3 days ago | parent
What do you think Claude (chatbot web interface) is?
ffsm8 3 days ago | parent
rockdoe 3 days ago | parent
My only explanation is that Anthropic's search backend sucks.
nomel 3 days ago | parent
platevoltage 3 days ago | parent
tshaddox 3 days ago | parent
whatshisface 3 days ago | parent
ernestrc 3 days ago | parent
titzer 3 days ago | parent
Fielding a web index takes a massive amount of compute and storage of a very different kind than what Anthropic is using. AI is extremely heavy on GPU, maybe somewhat on storage but (comparatively) light on CPU. They need CPU to train coding agents, obviously, but scaling to a billion user web search is a whole different thing.
mdbug 3 days ago | parent
jitl 3 days ago | parent
Philpax 3 days ago | parent
Razengan 3 days ago | parent
Maybe that's their way of becoming Google?
ihumanable 3 days ago | parent
jitl 3 days ago | parent
klustregrif 3 days ago | parent
binlog 3 days ago | parent
Anthropic could easily build a CRM equivalent to or better than salesforce but they still wouldn’t be able to compete with salesforce. It makes a lot more sense to sell salesforce tokens instead.
asdff 3 days ago | parent
Imagine how much money they'd raise if they just said one day "we are going after salesforce bottom line now." It would be like chumming the water.
pianopatrick 3 days ago | parent
henryfjordan 3 days ago | parent
Selling AI to everyone does scale though!
__xor_eax_eax 3 days ago | parent
As many in the industry say now - writing code was never the hard part
Razengan 3 days ago | parent
tshaddox 3 days ago | parent
hilariously 3 days ago | parent
pegasus 3 days ago | parent
camdenreslink 23 hours ago | parent
chrisfosterelli 3 days ago | parent
tshaddox 3 days ago | parent
an_guy 3 days ago | parent
pianopatrick 3 days ago | parent
vhantz 3 days ago | parent
YorickPeterse 3 days ago | parent
usernametaken29 3 days ago | parent
nozzlegear 3 days ago | parent
jonathanyc 3 days ago | parent
We’re completely rethinking our priors. This project prompted us to take a very hard look at other workflows designed for human scale. A proper merge queue, for example, doesn’t make much sense at agent scale. What does CI even mean when hundreds or even thousands of changes can merge while tests are running? We haven’t been able to effectively replicate the industry standard of a global repository lock on the merge queue, so instead, we’ve invested in post-merge and pre-deploy automated testing. This does mean that concurrent changes can conflict, but Claude can typically fix these conflicts faster than humans can even identify them.
nixpulvis 3 days ago | parent
I think this is the wrong way to solve problems and goes the wrong way toward solving real problems.
tasuki 3 days ago | parent
I'm sure the system is being constantly updated and will get more and more bloated over time and interesting things will start happening.
chris_money202 3 days ago | parent
comboy 3 days ago | parent
> Clients are always online. Git assumes that clients work offline and need a complete copy of the repository. Since nearly all of our clients are agents and jobs, we designed Scion’s client and protocols around a server that is always reachable, and have clients fetch data when they need it.
This also tells something about these companies idea of sandboxing.
tasuki 3 days ago | parent
bottlepalm 3 days ago | parent
rpowers 3 days ago | parent
apf6 3 days ago | parent
DenisM 3 days ago | parent
Yes . And also they optimized for orders of magnitude more throughput and less latency, and fixing errors after the merge. This is new - they see enough benefit in velocity that justifies merging bugs and dealing with it later.
And it reminds me of when git came out and Linus said that git being super fast locally created a qualitative change in engineers head - it became a new way of working back then.
nickg-anthropic 3 days ago | parent
gritzko 3 days ago | parent
E energy necessary to integrate changes
m mass of the monorepo
c rate of commits
znpy 3 days ago | parent
mqus 3 days ago | parent
wclausen 3 days ago | parent
* This system leverages a metadata log pointing to immutable blobs in object storage. The metadata log can give high write throughput and keeps the control plane consistent. Object storage supports high throughput of the heavier data objects. Overall, it's an excellent choice given VCS systems can typically tolerate the latencies associated with object storage, as is the case with many operations-focused systems for businesses.
* The server/upstream gains scalability by reducing the amount of data it processes when accepting a commit/performing standard VCS operations. No packfile, no file i/o to construct a consistent copy of the repo, just a (usually) small metadata record that can be validated/committed quickly. The client primarily gains scalability along a similar axis (reduce amount of extraneous work for a given goal) where it can request just the pieces of a repository it needs to do its job, when it needs them. For example, agents can begin reading files from a checkout eagerly before the whole updated version of the repo is finished being downloaded, then during a compile step, updates can be fetched only for the module being compiled, etc.
* The system seems well designed from the perspective of considering "when exactly do I need a thing to be done." Git tends to bundle more of this work into synchronous operations when a request comes in, which ensures the system is consistent at the end and doesn't require a persistent process, but is costly. This system makes intentionally different decisions about "what work happens, when" so that the minimum amount of work is done to confirm a write and allow for the state of the repo to be reconstructed consistently, but it defers certain things that are useful but don't need to block a write. The discussion of "derived data" mentions that certain useful structures can be computed in a deferred way, which supports doing work around the time it's needed.
* A large part of the nice operational features of the system is downstream of making core data structures immutable. File contents are immutable, content-addressed blobs. WAL entries are immutable records. As mentioned in the article, this supports excellent caching, and simplicity in reasoning about history/updates. Additionally, the derivation of other useful data can end up as immutable outputs (themselves stored as pointers to objects, if scalability requires it).
* The decision to develop a custom VCS supported a number of other integrations into "agent-first" software development systems. The system makes it easy to enforce access control on specific directories, nice if you want to have agents explicitly denied the ability to edit something. You can also get a sense that it supports some valuable features in the associated code review system, for things like pointing a human at the most important changes in a changeset. You could imagine in the future, some associated highly flexible "owner" rules/notifications where a human can specify "I want to be notified if X system has a significant design change" and that intent can be recorded/managed in a more useful way than "add me as a reviewer if files in /abc directory change."
* I do wonder if content-addressing of the files is broken into chunks or not. Doing "one blob per file" is nice and simple, so maybe that's how it starts. But you also duplicate a lot of data, but maybe the dataset is still trivially small in the scheme of things, and the operational concerns win out. And if files are small anyways, you'd want to avoid splitting them into tiny chunks bc that'd affect the bandwidth you can achieve when downloading (spend more of your time on per-object/request overhead rather than actually transferring data).
Very nice piece of engineering work. I was also impressed by some other parts that received a little less discussion in the post (understandably), but would love to hear more in a future post:
* the testing approach of driving tons of system interactions in a hermetic way is really exciting to see. Feels like agents should help us write really excellent testing infrastructure, and that this would itself be important for gaining confidence to deploy without requiring a read of every line committed.
* Similarly, the mention of the "superfan" agents that closely monitor very specific parts of the system seemed very cool and would help a lot with deploying code you haven't necessarily read closely but seems reasonable architecturally. Though it'd still ofc be best to catch issues prior to merge/release, having extremely good monitoring/rollback capabilities would mitigate a lot of the downsides of high-speed, agent-based software development.
nickg-anthropic 3 days ago | parent
Good observation! If we share details about Antique, this will definitely be in there; this space is ripe for innovation.
For the "one blob per file" piece, blob storage is fairly cheap, but there is also a relatively simple way to get something like delta compression for blob storage that the clients never need to know about.
tasuki 3 days ago | parent
rao-v 3 days ago | parent
colek42 3 days ago | parent
abroszka33 3 days ago | parent
boredumb 3 days ago | parent
paaloeye 3 days ago | parent
Scaevolus 3 days ago | parent
ch_sm 3 days ago | parent
LarsDu88 3 days ago | parent
Now Anthropic has migrated from Git to Scion. It's a good sign they are on the right track.
bob1029 3 days ago | parent
If I was an investor I would be on the phone with Dario asking why we are wasting engineering talent on reinventing source control and churning the product with 30k pulls per day.
meindnoch 3 days ago | parent
To be able to write PR pieces, like TFA.
ricericerice 3 days ago | parent
thewhitetulip 3 days ago | parent
Surely they can't manage to have a performant binary versionnof claude code and they're stuck with JS runtime
potamic 3 days ago | parent
ragtagtag 3 days ago | parent
They've ripped out and replaced the most carefully thought-out part of the CI/CD chain with something less carefully thought-out, while leaving the teetering house of cards in place.
TeMPOraL 3 days ago | parent
--
[0] - If you can even call anything built before modern petrochemical industry a "bicycle".
jeffrallen 3 days ago | parent
TeMPOraL 3 days ago | parent
I don't know why is this even controversial. Agentic swarms break scaling assumptions all across the typical software development life cycle; VC and CI/CD are just few obvious cases.
mhast 3 days ago | parent
Sounds like a out of the frying pan and into the fire kind of solution.
With the added bonus that you now have a vibe-coded VCS, so good luck when that has strange bugs.
s08148692 3 days ago | parent
fg137 3 days ago | parent
But then Anthropic doesn't get the PR, so...
Cthulhu_ 3 days ago | parent
The cost of innovation or "just" writing a new tool is plummeting fast.
catlifeonmars 3 days ago | parent
Doesn’t this make it less profitable to be an R&D company, since there is less market share available?
theteapot 3 days ago | parent
jgbuddy 3 days ago | parent
Who's beating Anthropic here lol
pianopatrick 3 days ago | parent
whalesalad 3 days ago | parent
0c3ca83 3 days ago | parent
From what I recall, Google's repo is closer to 80 terabytes.
nickg-anthropic 3 days ago | parent
Panzer04 3 days ago | parent
Even if you can write a lot of code with LLMs, what is that code actually doing?
nickg-anthropic 3 days ago | parent
0c3ca83 3 days ago | parent
real_faxenoff 3 days ago | parent
rcleveng 3 days ago | parent
The guy who ran that project called it his "$LASTNAME law" that every large company will at some point write their own source control system.
I laughed.
About a year later I went to Google, and within a couple of years Google also did the same thing.
Not at all surprised. Git was just good enough (and cheap enough) the companies didn't need to do this to escape the {phsyical scaling, cost scaling} problems that most commercial SCM systems had.
Eridrus 3 days ago | parent
Cursor scaled git to way more writes/s than Anthropic did with their rewrite.
Human-Cabbage 3 days ago | parent
Eridrus 3 days ago | parent
Anyway, Anthropic seems able to do exactly one thing well: train a frontier model. Their other software seems like garbage. OpenAI seems to be following a similar trend lately too.
nickg-anthropic 3 days ago | parent
shooshx 3 days ago | parent
rcleveng 2 days ago | parent
Clearcase was way ahead of it's time, the main issues there were really just cost (mostly licensing cost, and a little on how many sun servers you needed to serve it and keep state of the vobs)
Perforce was way ahead of it's time, everyone still wants a monotonically increasing changelist identifier too.
exabrial 3 days ago | parent
> monorepo
Well, there's your problem.
BatchJob 3 days ago | parent
And for this they buy disk? Maybe this is irresponsible use of technology.
Robdel12 3 days ago | parent
I read this and wonder what their agents have committed into the repo that people aren't looking at for _that much size_? Do they have a ton of binary assets in there or something??
grey-area 3 days ago | parent
Not sure they should be proud of these numbers, they’re a sign of dysfunction.
nickg-anthropic 3 days ago | parent
This is really all just text.
w10-1 3 days ago | parent
But it's a sad example, for open-source and for small engineering companies. Instead of infrastructure being more easily shared with the collective, or valued enough to build a business, now companies can tailor even major infrastructure to their own needs, and avoid all that coordination.
I'm glad they publish their notes to encourage others, but I suspect we're entering an epoch where confidentiality matters most.
Anthropic's problem was merging code at scale, but the scale problem I have with SCM is really merging all the related docs; these get lost in a stream of a forest of comments, PR's, and documentation, all of which (like a wiki) goes rapidly out of date before anyone notices because none of it is automatically correlated.
moregrist 3 days ago | parent
Large companies have always done this. Tons of early 2010s open source projects came out of reimplementing white papers from closed-source Google projects.
It’s also the major downside of this kind of thing. Once someone gets acclimated to how things are done at a large company with custom tools, it’s not always easy to switch to another process, especially a simpler one. There are tons of stories about FAANG engineers joining a startup and being useless.
There’s real value in having consistent tools across an industry. It makes hiring and training easier. Even if you’re convinced that a LLM could crank out a payroll or ordering system that’s perfect for your org, you still have to train the accountants and admin assistants to use it. And you’ve now become the customer support.
The bar is lower with version control, but it’s still more friction than git + GitHub + a well-known workflow.
zmmmmm 3 days ago | parent
The first thing that hits me is, did you consider not going all in on a monorepo? I know it has been the trend in general, but it seems a bit of a red flag when you go from "let's have a monorepo it will make merging easier" to "let's redesign version control because merging is too hard now" without the middle question "should we really have a monorepo?"
As a derivative thought I'm curious if AI tooling is tipping people more towards monorepos now since it gives the agent the whole context of the app in one go? Or is this independent - I can easily check out 5 repos in one directory and run an agent there.
cush 3 days ago | parent
andrekandre 3 days ago | parent
cush 2 days ago | parent
andrekandre 2 days ago | parent
cush 2 days ago | parent
andrekandre 1 day ago | parent
wocram 3 days ago | parent
victor_pudeyev 3 days ago | parent
I never got caught into the monorepo fad, I'm glad I didn't, and I still don't see a point in having monorepos. Let's say in ruby on rails, I have the host app and 3 mounted gems in it. That's 4 repos. It could be all merged into one monstrosity but separate repos help keep complexity down, and help define interdependencies cleaner and simpler.
The monorepo idea was just a fad. Each package should be its own repo. Each package should be meaningfully useful, e.g. one package for string utils, not one package for trim, one package for pad, etc.
skydhash 3 days ago | parent
zmmmmm 3 days ago | parent
Everything works like this in the end at some level. I assume people with monorepos don't retest their project on every Linux kernel commit - it's pointless, you are never going to run against exactly that commit. But you will do it when you do upgrade Linux versions, etc.
dasil003 3 days ago | parent
nickg-anthropic 3 days ago | parent
zmmmmm 3 days ago | parent
olcarl75 3 days ago | parent
benleejamin 3 days ago | parent
nickg-anthropic 3 days ago | parent
We never allow textual conflicts, but semantic conflicts (for example, if someone adds changes the logic of a function and cleans up all affected callsites concurrently with a new call being added) are an unavoidable fact of very large repos unless you completely serialize merging with running extensive validation at the proposed batch tip, which isn't practical at a certain commit rate.
As for cross-repo changes, not exactly, but there are ways we could allow such a thing if we wanted. We're thinking about it.
cdata 3 days ago | parent
grogenaut 3 days ago | parent
OkayPhysicist 3 days ago | parent
An agent swarm has a very different set of problems. There can be a lot more agents making changes in parallel than you'd see in all but the biggest megacorps, and the pace of those changes can be ridiculously high. The rapid pace simultaneously balloons the total repo size (because of history), and the frequency of collisions. A modifies file 1, B modifies file 1, A commits changes, B runs into conflict. Or worse, C modifies file 1 after A commits their changes and beats B to commit, resulting in B growing staler and staler as they race to get their branch merged.
adsharma 3 days ago | parent
An entire dept exists to make it work. Atomicity and security are other arguments. The larger the company, the stronger the incentive.
It's not something average software developers working elsewhere care about much.
Amazon seems to be the only big company bucking this trend.
valleyer 3 days ago | parent
__MatrixMan__ 3 days ago | parent
Besides, agents really fly when the whole project fits comfortably in their context window. You get all these nice interfaces to bound context with if the API's and public types are defined and versioned separately from each team's repo.
nl 3 days ago | parent
Doing it like that works, but then you end up doing all the cross-repo concerns in every single repo. I don't think the savings in history are all that much anyway - yes, you save on the rarely modified repos but the heavily modified repos still have a similar amount of changes.
waterTanuki 3 days ago | parent
blincoln 3 days ago | parent
"The traditional approach to marriage didn't work for us. But then we realized that co-habitating (or even living near each other), sharing resources, and even communicating with each other are goals that don't apply to everyone. That's how we invented the 'live 500 km apart and never communicate with each other again' style of marriage, and it saved our relationship."
I'm exaggerating, of course. Slightly.
xyzsparetimexyz 3 days ago | parent
schleck8 3 days ago | parent
consumer451 2 days ago | parent
It seems like open sourcing it would be the least they could do after ingesting all open source code to make their models, which are now replacing devs and other IT workers.
armcat 3 days ago | parent
These are just some of the things - there may be many more.
nickg-anthropic 3 days ago | parent
Karrot_Kream 3 days ago | parent
Arainach 3 days ago | parent
nickg-anthropic 3 days ago | parent
Karrot_Kream 3 days ago | parent
gruntled-worker 3 days ago | parent
Less-than-great news for code artisans. You can be brilliant, but can you divine the Right Way to Write It if you're up against an apparatus that starts at "pretty good engineer" then brute-forces its way down an exponential search tree?
nickg-anthropic 3 days ago | parent
kneel25 3 days ago | parent
pertymcpert 3 days ago | parent
nickg-anthropic 3 days ago | parent
Good call about us not defining it, I can fix that! And this blog post was 100% human-written.
radley 3 days ago | parent
Obvious, but this is my biggest takeaway from the announcement.
gigatexal 3 days ago | parent
jwpapi 3 days ago | parent
They all would analyze data and suggest apple changes themselves.
Do you guys think that’s how it works? Is anybody already operating at that scale, how do you even validate stuff.
Like I think I could run my whole software now only on agents, but not sure how it would turn out.
Bluestein 3 days ago | parent
And this will become the new "caste" system of tomorrow. Today: Those with "metered", gatekept intelligence - vs the gatekeepers and those at the core of the new Sun.-
mattmar96 3 days ago | parent
“Run only the tests that are applicable around this change”
Plus a full test run gate for version tags and perhaps nightly, as it would be expected that sometimes the subsection of tests run missed a breaking change.
sige11 3 days ago | parent
sige11 3 days ago | parent
ckvibubueu 3 days ago | parent
victor_pudeyev 3 days ago | parent
2. So they're trying to make code so complex that humans can't read it anymore?!
3. What's the point of changing code? Are the changes - how do you say - useful?
4. Thank God for Git, the amazing piece of software by the venerable Linus Towalds, that just keeps on giving! It's free, open, and excellent quality source-control software, and you can even keep binary files there. Excellent stuff. I can't imagine ever not using it.
bhouston 3 days ago | parent
ashkankiani 3 days ago | parent
mikebiglan 3 days ago | parent
Anthropic says 12x daily merged changes, and its Git-based infrastructure started straining. I've seen that even locally git trying to keep up and having to shift how i commit in parallel.
If agent workloads grow to 20x or 50x today's levels, I think we'll keep finding bottlenecks across builds, CI and review. I expect some of that infrastructure will need redesigning from the ground up to support it.
PR/Review contention and look-aheads to try to prevent will be more and more important, and we're building in that same space so i love hearing stories of people going back to the foundation...a system that worked fine for decades, now suddenly is busting at the seams.
offsky 3 days ago | parent
winrid 3 days ago | parent
chrisweekly 3 days ago | parent
winrid 3 days ago | parent
usernametaken29 3 days ago | parent
Gigachad 3 days ago | parent
nickysielicki 3 days ago | parent
You have a new internal VCS? Kudos! Why should I care? Do you offer it as a service? Can I pay you for it? Does this have any bearing on me whatsoever?
They might as well publicize a redesign of their office space.
arxanas 3 days ago | parent
fg137 3 days ago | parent
For the rest that do, the vast majority of them are going to buy some Perforce licenses instead of vibe coding their own solution.
Unless you are Google/Meta where your company is large enough and its revenue supports paying a team of engineers (a lot of money) to do that, or you are Anthropic who is just vibe coding everything which can turn out to be good PR, you simply don't have the resources or can afford the risk to develop your own VCS solution.
This may be inspiring but out of question for most companies.
nickg-anthropic 2 days ago | parent
fg137 2 days ago | parent
etruong42 3 days ago | parent
mbfg 3 days ago | parent
QuiEgo 3 days ago | parent
a_bonobo 3 days ago | parent
>Written by Nick G. and the source control team: S.G., R.K., Dan C., Garrett H., Ben L., Colin M., Joe P. We’re grateful to Vilas J. and Sergiu D. for supporting the source control team on this ambitious journey and Amir O. for early contributions to Antique.
Are Anthropic engineers now anonymous? Seems like a strange choice
mindwok 3 days ago | parent
dangoodmanUT 3 days ago | parent
I appreciate that they're extremely self-aware here.
randyrand 3 days ago | parent
...on expensive / over-priced Anthropic products.
If you wanted to use this amount of tokens you would find a cheaper provider.
Still some room to be more self-aware.
podgorniy 3 days ago | parent
They briefly articulated one obvious, undisputable and toothless truth about themselves. This is far, far from "extremely"
kazzak13 3 days ago | parent
>Very often, we found that the role of the engineers was to tell Claude “no.” Agents will sometimes violate core system constraints to satisfy a pattern that should never have been allowed in the first place.
Glad to hear from Anthropic their own struggles with steering Claude in developing software.
vhantz 3 days ago | parent
> Engineers are no less valuable, but their work is changing. All of the engineers who worked on this system would now rate Claude as better at writing code than them. But our engineers still supplied the invaluable understanding of the high-level inter-system components and the design-level tradeoffs, making informed choices around the problems we wanted to solve and the scale we knew we needed to achieve. Very often, we found that the role of the engineers was to tell Claude “no.” Agents will sometimes violate core system constraints to satisfy a pattern that should never have been allowed in the first place.
It's incredibly short-sighted to acknowledge that the baby sitters haf to tell Claude no and still not consider what subtle and nasty bugs managed to slip through. Well I guess we'll find out soon enough if that's the case. I'm betting when that's the case.
vhantz 3 days ago | parent
What is all this code being used for? I'm 100% sure it's not going into their harness which has been stagnant.
yamanahlawat 3 days ago | parent
> But our engineers still supplied the invaluable understanding of the high-level inter-system components and the design-level tradeoffs, making informed choices around the problems we wanted to solve and the scale we knew we needed to achieve. Very often, we found that the role of the engineers was to tell Claude “no.”
salynchnew 3 days ago | parent
ulrikrasmussen 3 days ago | parent
Who in their right mind would fetch that naively? For starters, CI runners should of course not do a fresh clone on each run. If you can't make them keep the repo, that sounds like a problem with your CI setup rather than your VCS.
This reads like a straw man.
nickg-anthropic 3 days ago | parent
ulrikrasmussen 3 days ago | parent
I do accept the argument that a distributed architecture has inherent costs which can be managed better using a client-server architecture because you don't have to replicate state across all nodes. I have worked with both git and Perforce and see the appeal of both.
Gepsens 3 days ago | parent
simianparrot 3 days ago | parent
They’re so smart they’ve looped around to being full retard.
qalmakka 3 days ago | parent
That sounds like Subversion with extra steps
> In git, you commit locally and then push to share your work. In Scion, every commit, rebase, or merge happens on the server, so there’s nothing to push,
Yep not beating the allegations with this one
To be fair 90% of the companies I've ever worked for always used git in a way that turned it into Subversion, but with 10x the storage usage (note: I hate Subversion with a passion, I'd rather send patches via email than that)
dmead 3 days ago | parent
he0001 3 days ago | parent
bytemut 3 days ago | parent
alex_suzuki 3 days ago | parent
That line stuck with me. I wonder how the engineers building Scion feel about that? If that really is the future, then I guess I have to find another profession. Retirement is still too far away.
ngruhn 3 days ago | parent
vessenes 3 days ago | parent
It feels exactly like talking to an experienced security engineer suddenly tasked with designing a large system — right now the tradeoffs that an architect makes don’t tend to be there, so quality oversight gives much better outcomes.
duttish 3 days ago | parent
This is my disconnect with this kind of speed, how are they avoiding the janky crap? Or are they just accepting it and hoping it won't be too crappy or be found soon enough?
I don't have any insight into Anthropic but it seems like that's the case which is just depressing.
xthetrfd 3 days ago | parent
josteink 3 days ago | parent
johnisgood 3 days ago | parent
Which is what the developer should actually be paying attention to, but I suppose they are just adding features for the sake of adding features.
skopdop 3 days ago | parent
Hugsun 3 days ago | parent
johnisgood 3 days ago | parent
jabron 3 days ago | parent
rebolek 3 days ago | parent
program_whiz 3 days ago | parent
itsdavesanders 2 days ago | parent
It might be fully automated and eventually the agents figure out all of the bugs, but I suspect the costs are so large that no sane company would ever write code this way, and probably WAAAY more expensive than just hiring humans to write and test it.
solenoid0937 2 days ago | parent
joquarky 2 days ago | parent
xtajv 2 days ago | parent
made me throw up in my mouth a little bit.
c048 3 days ago | parent
Keep in mind that Anthropic is first and foremost trying to sell you something.
aktau 3 days ago | parent
Is my suspicion wrong? Are models getting better fast enough that they'll be able to add new feature (or fix bugs) and clean up even despite a mountain of AI tech debt [1]
[1]: I say AI tech debt because it tends to have some characteristics that are different from human tech debt, such as apparent lack of intentionality (which makes Chesterton's fence evaluation much harder). Perhaps if we make the AI write down somewhere, as briefly as possible, why it wrote each chunk of code...
TeMPOraL 3 days ago | parent
Well-configured agents do, in comments and commit messages and docs.
But many people are just stuck thinking in GPT-3 era, where the prompt was all there was to it. It's not. You write a 1000 token prompt describing what you want, and the agent pulls in 10k tokens of system prompt, then spends time exploring the codebase and calling tools and attending to 100k of more tokens from this, possibly including output of sub-sessions that do the above, and somewhere along the way, having read lots of code, run lots of tests, perhaps doing a spike or two, the agent then decides some chunk of code needs to be written in this way, and not in some other way.
The reason is not contained in your original prompt at all. It's almost entirely based on what the agent learned about the current state of your codebase and environment.
skopdop 3 days ago | parent
troupo 3 days ago | parent
iforgotmypasswo 3 days ago | parent
In my case, “Factory” is hundreds of architectural tests built over thousands of application specific tests, and a couple MD files here or there. The MDs are mostly reference material and common patterns. The tests are what actually enforce feature/module isolation and proper architecture.
Lately, I’ve been getting overzealous with protobuffers and service discovery as well. I would never use these tools so frequently if I was designing for humans. With AI I’ll slap annoying boundaries in to enforce separation of concerns without thinking twice.
Making a new project is a pain at this stage, but you can just point to CI and the general structure in an existing project and AI will clone the important bits. I suspect high level architectural rules with programmatic enforcement will eventually be encoded into tools for easily starting new projects. Kind of like pnpm installing specific development practices and architectures.
I used to do a lot of work with reflection, compile hooks, and dynamic source generation before AI. You can do a lot to compensate for the architectural blind spots of AI if you get creative.
troupo 3 days ago | parent
How about code blind spots like endless code duplication? Reading the whole DB to read one record? Slow algorithms? Bad data access patterns? Excessive defensive programming? Inventing new issues just because your "high level architectural creativity" mentioned something off-hand? Etc. etc.
On top of that, where are your "hundreds of architectural tests built over thousands of application specific tests" coming from? Also written by LLMs I presume?
TeMPOraL 3 days ago | parent
All of these are endemic problems in this industry, openly discussed for decades before LLMs were a thing.
But the pragmatic reality is the same for people and agents - those "mistakes" are common; juniors make them because they don't know better, seniors make them for good reason (pragmatic tradeoffs). Good teams know how to prioritize, and generally fix them when they start causing problems. Agents are very much capable of the same, fully autonomously these days.
Personally, I've had plenty of cases where an LLM came out with a sleak, and arguably over-optimized algorithm or DB query - but when I looked closer at what it did, I saw it first came out with something dumb and claimed a win, then run it, realized it's stupidly inefficient, and optimized it on its own, before giving the final version to me. All in a single turn, without being explicitly prompted to work like this.
troupo 3 days ago | parent
latentsea 3 days ago | parent
troupo 3 days ago | parent
Agents don't learn. They rebuild a lossy context about your codebase from scratch every time, and then produce lossy output based on that context.
> You write a 1000 token prompt describing what you want, and the agent pulls in 10k tokens of system prompt
And at this point its context is so polluted so it doesn't matter
lukaslalinsky 3 days ago | parent
TeMPOraL 3 days ago | parent
Same is true about employees and interns, from any company's POV. And in large companies with large projects, it's true from POV of employees too.
troupo 3 days ago | parent
TeMPOraL 3 days ago | parent
--
But let me spell out my original comment, to clarify:
Agents are like interns: they come to do the job, having none of the knowledge specific to your codebase and company. They have no time, to properly study the whole thing. They get a task, and are expected to figure it out (with help of documentation and people). Then they do the thing, and regardless of the outcome, are gone few months later, and you never hear from them again.
(In many companies, for various reasons, juniors are effectively interns with larger context window.)
In large companies with large projects, everything is moving so fast that no one - no one - can possibly understand the whole thing, and the work paradigm is purposefully structured so they don't need to. In some sense, they're like perpetual interns - each time they start working on different area of the project, they know next to nothing about it, and do not have a chance to fully comprehend it. They just need to figure out enough to deliver on their tasks.
(I know, because I like understanding things, and in one place I was told explicitly it's a common trap for people like me, and I need to learn to suppress it if I am to be effective at my job.)
Unsurprisingly, this works. Both examples are proof positive that this way of working is sustainable and scales well. It may not be optimal, but it works, which means agentic version of it has every right to work and scale as well.
troupo 3 days ago | parent
> Agents are like interns: they come to do the job,
They don't come to do anything. Stop this infantile antromporphising of LLMs.
They are nothing like interns. Interns learn. And companies don't develop products by getting a new batch of interns every day.
> Unsurprisingly, this works. Both examples are proof positive that this way of working is sustainable and scales well.
No, it's not even close to proof. The conclusion literally doesn't follow from anything in your prevuous text.
If your agents are "perpetual interns" then this is proof that no, it doesn't work and it doesn't scale.
As for large companies... You don't have to know the whole thing, but you do have to know your area. You don't come into work at a large company always asking "what is it I am doing" from scratch every single day.
TeMPOraL 2 days ago | parent
> They are nothing like interns. Interns learn.
And then they go elsewhere, so no, from POV of the company, if you treat "internship period" as "session", they don't learn. But they leave behind documentation and changes to code.
I guess another way to put my point is: the idea of code being self-documenting isn't completely flawed. It works to a degree; in fast-moving teams in large companies, you don't have any other ground truth anyway (documentation is always stale, design docs become obsolete the day they're approved, etc.). People manage. And so can agents.
> but you do have to know your area
It so happens that LLMs know nearly every single area of human endeavor better than most practitioners :).
troupo 2 days ago | parent
No, it shouldn't. If you compare agents to interns then you have a new batch of interns not even every day, but every few hours (with every new session, and every new subagent).
> so no, from POV of the company, if you treat "internship period" as "session", they don't learn.
So,
- interns are a very tiny fraction of a workforce at any given company
- no company is ever building the bulk of their products with interns alone
- from POV of the company interns never learn, and the new interns should be taught everything from scratch, again
Somehow, from all this, your conclusion is that "it's proof that it works and can scale"
> It so happens that LLMs know nearly every single area of human endeavor
They have very approximate knowledge of those areas + this knowledge is rather randomized in the output. On top of that they are trained on publicly available code which is shit. Plus they know nothing (and can never learn anything) form your particular code, and your particular project.
xenadu02 2 days ago | parent
Nope you are 100% correct. All of the models will code themselves into local maxima then spend more and more time chasing their tails as every change introduces new bugs, the agent adds more complexity, and the code base just spirals. Best case you end up with a bunch of parallel implementations that all work slightly differently.
It helps a lot of you pay attention to what it is doing and impose order, then regularly spend time refactoring - even if you are having claude do the work itself - you have to spend the time on the overall architecture and design.
I just experienced this with an internal productivity tool. Without claude this tool wouldn't exist - there would never be the justification to take the required time to build it. On the other hand all the interlocking refreshing rules for sourcing data from its inputs got so byzantine it was impossible to add new features or change anything without causing new regressions. Claude built a web of ad-hoc timers, refresh kick-offs, monitors, etc to solve each feature problem or fix some bug but the whole thing was impossible even for claude to understand. It took a special large workflow session to find most of the mess and even then during the refactor it kept finding new things.
I had to stop all feature work for going on four weeks and burn a ton of tokens to build a refreshing/syncing engine that could track dependencies, priorities, etc and fully test it and just now today I am finally able to get feature work going again.
On another feature an agent came up with a state object containing 55 inter-related fields with all kinds of interlocking dependencies. Something so complex no one could hope to understand it. And I find the agents aren't really much better at understanding such things than humans are. If you leave it like that the agent will just perform worse and worse on that part of the code as time goes on. It will make assumptions that force it into bad design corners, miss edge cases, and flat out miss things no matter how well you prompt. Agents benefit from encapsulation and simplicity just as much as humans.
techpression 3 days ago | parent
cheema33 3 days ago | parent
miken123 3 days ago | parent
Your bar for quality must be pretty low if you feel this is better than average?
mezyt 3 days ago | parent
kortilla 3 days ago | parent
logicchains 3 days ago | parent
1dontknow_ 3 days ago | parent
arcanemachiner 3 days ago | parent
My favourite is Claude Code's /rewind feature, which gets so many things wrong for having such a simple UI. (Does selecting the default option still wipe your filesystem changes by default when going back to a previous entry? I found a poorly-documented way to circumvent that "feature", which only adds to my initial point.)
1dontknow_ 3 days ago | parent
troupo 3 days ago | parent
1dontknow_ 3 days ago | parent
Theyre usable but leave alot to be desired. SOme other tools like opencode seem sometimes to have less feature (if exact numbers) but at least always work.
Somehow with Claude and some others, random simple thigns dont work. Esp long solved problems like TUI rendering, special chars, breaking changes every release etc.
Surely as always with software this is my experience and might be not yours.
PS: Ive used IntelliJ since... always?. It was quite decent. But these last years it is just so diferent, somehow way less quality, so many random bugs that Im afraid theyre doing AI agentic coding which sucks for such an important tool.
IDEs should be build from real professional crafstman with an exact vision in their heads, not some wild AI.
Im starting to think in a year or two "We dont use AI in developing our products" will be some kind of marketing trick since people will start looking for that.
dunder_cat 3 days ago | parent
The root of this challenge comes from more text aka more code ~= more tokens, so these firms have little incentive to optimize for that mindset. Sure, they might have more optimized individual responses - but the end result is still giving people what they want: more features, more documentation, nice, long, verbose and well-formatted Jira comments, of sometimes questionable but sometimes undeniably impressive quality. The band marches on, and when your codebase outgrows the constraints of the tried-and-true tools, you can just invent your own. With documentation and an MCP or two, or ten -- to also pull into your context window.
[0] I work on an operating system, so a suggested retort is to say this is me pushing responsibility and logic to the people higher up on the stack ;-)
km3r 3 days ago | parent
I'm not sure if this is true. The code is such a small part of the total output. Thinking harder, like what would be needed for architecturing better code, would use more token.
agos 2 days ago | parent
overgard 3 days ago | parent
damethos 3 days ago | parent
duttish 3 days ago | parent
johnisgood 3 days ago | parent
stymaar 3 days ago | parent
Using Claude code for a few days gives the answer pretty quickly: they fully embrace the janky crap and ship it to their users without second thoughts. And as long as their users don't mind using their piece of shit, why should they do otherwise?
eviks 3 days ago | parent
epolanski 3 days ago | parent
Not throwing endless resources and energies at a problem "because Twitter told me what the best practices are".
E.g. Maybe Claude Code could use half the memory, maybe, but maybe the correct estimation is that solving the memory problem would negatively effect development speed, or would cost many millions of engineering effort and no real world user would really care whether it's using 50 or 500 MBs of ram.
So no, you're not an engineer but a "developer", if you think that "quality" code is engineering, code has a development and maintenance cost, specific directions come with important trade offs.
eviks 3 days ago | parent
But since it isn't (we know real users care and complain, we know it's not your made up "endless resources" and "millions of engineering effort" because "millions" of other software products exist that have been made without those) you're short of an actual argument.
> code has a development and maintenance cost, specific directions come with important trade offs.
Yet again you forgot to make a case how any of those trade off towards the current state.
In general, how would you ever determine whether the current situation is justified or not if nothing in your strawman questions anything, but just comes up with not very plausible justifications of whatever already exists???
markus_zhang 3 days ago | parent
queenkjuul 2 days ago | parent
That has no bearing on the product i maintain, where users very much have a choice, and we keep them with us by solving their problems and listening to their concerns.
no-name-here 2 days ago | parent
But real users do that about pretty much every piece of software, correct? Free SW, expensive SW, open source, closed, SW by a single person, SW from a massive company, etc.
eviks 2 days ago | parent
chasd00 3 days ago | parent
markus_zhang 3 days ago | parent
mr_roboto 3 days ago | parent
program_whiz 3 days ago | parent
AbstractH24 3 days ago | parent
Work in general is.
Heck, life in general is
egorfine 3 days ago | parent
AbstractH24 3 days ago | parent
There is an assumption here that everyone thinks of excellence the way you do.
j45 3 days ago | parent
There are also some pretty detailed videos out there on YouTube of Anthropic employees showing how they are using cloud code on several orders of magnitude better than where the bulk of usage is.
richardbarosky 3 days ago | parent
j45 2 days ago | parent
munksbeer 3 days ago | parent
What actual bugs do people have with it, and why do we think it is worse than a human coded tool?
gbalduzzi 2 days ago | parent
The fact is people at Anthropic won't notice it because they are running it on M5 laptops
munksbeer 2 days ago | parent
Aperocky 2 days ago | parent
It's easily noticeable. Codex don't take half as much most times.
stymaar 2 days ago | parent
Also, the fact that they managed to leak their own code base, twice, tells you all you need to know about software quality at Anthropic.
jeong_jeong 2 days ago | parent
boogieknite 2 days ago | parent
as long as something works "good enough" and the code will never be reviewed theres only incentive to blast through tokens generating superfluous code. god forbid they actually ship a vibe coded product then they can basically ransom you for tokens
im probably being overly cynical but it sort of just seems like standard capitalism to me
MP_1729 2 days ago | parent
Yes, you'll pay hundreds to thousands of dollars in tokens per month for the rest of your career.
What is your point?
biggoodwolf 2 days ago | parent
tgsovlerkhgsel 3 days ago | parent
In the end, what matters is whether something fulfills its purpose, not how it does it. Code quality, understanding code, etc. are just a means to this goal.
Some level of poor quality is acceptable, and I assume they are hoping that model development (i.e. its capability to fix and clean up an increasingly convoluted mess) will outpace the tangledness of the code.
So far, it seems like they are winning. Yes, the UI is often broken (e.g. for a long time switching away from an ongoing conversation lost it), but it wasn't broken enough for people to switch to other companies that may have had a better UI but in exchange for that a less developed product. If Anthropic instead spent its resources on making the UI not janky and code reviewing everything, the overall product would have likely been worse because they couldn't build and improve features as quickly.
I've seen the flip side where "code quality" becomes its own independent goal and more time is spent gratifying various linters than writing the code, and the inability to get anything done in such an environment is a lot more depressing than janky UX that can probably be fixed by prompting the next generation model to clean it up.
colinmarc 3 days ago | parent
All software is broken, but LLMs seem to make the wrong compromises consistently when working in large codebases.
menaerus 3 days ago | parent
colinmarc 3 days ago | parent
Interface design is one of the things Claude is worst at in my experience (using it every day for the past year).
km3r 3 days ago | parent
Ideally, you design patterns that enable quick replacing of parts that get to messy. The code is cheap, just start from scratch with the defined functionality pre defined instead of bolted on with jank.
TeMPOraL 3 days ago | parent
menaerus 3 days ago | parent
colinmarc 3 days ago | parent
My point is more about up-front investment paying dividends. To speculate, it seems like the reward hacking is not there for long-term thinking.
menaerus 3 days ago | parent
arcanemachiner 3 days ago | parent
wuschel 3 days ago | parent
What would they be?
menaerus 3 days ago | parent
latentsea 3 days ago | parent
victords 3 days ago | parent
I agree with that in the pre-LLM world, but I don’t believe it’s the same today.
You can build something with “bad” code that works and is full of technical debt, but today paying this debt is getting cheaper and cheaper.
So if Claude’s wrong design decision leads to having to refactor several chunks of a codebase in order to implement a new feature, does it really matter if it’s Claude who is going to refactor it in a matter of seconds? Especially for a company like Anthropic which has a virtually unlimited number of tokens to spend on it.
glub 2 days ago | parent
Like before AI, that debt is never going to get paid. Because how exactly are you paying off that debt when the means of paying are debt generators?
queenkjuul 2 days ago | parent
lionkor 3 days ago | parent
This is a fallacy. Computers are very deterministic, a well designed program will not have any bugs or unforeseen failures at all. You're not planting a tree and going "oh god I hope it survives the winter", you're programming a human-made computer, made of hardware that undergoes such incredible scrutiny before it's ever powered on that you can trust that it executes the same code, the same way, every single time, for decades.
No idea why people who clearly don't understand the difference between poppy farms and computers come in here and claim the world isn't perfect and so we should all accept sloppy shit code that barely works. The world isn't perfect, but software CAN be quite close.
Every single instance of jank on computers is a bug that someone wrote, or an LLM wrote, that can be found, understood, and fixed. And only once you understand this, can you talk about software quality to other engineers. You need to understand that the baseline is that software is not fallible the way the rest of the world is.
See sqlite3 if you want to know what nearly bug-free software looks like. I can't point you to a potato farm or an artist who is perfect, but I can point you to that and say "this is where we go when humans do a good job".
xhevahir 3 days ago | parent
I don't know where you think you've found a fallacy. Computing systems are expected to interact in various ways with the outside world, which does include poppy farms, and people, and other decidedly imperfect things.
lionkor 3 days ago | parent
dekhn 3 days ago | parent
buriram 2 days ago | parent
lionkor 2 days ago | parent
tempfile 3 days ago | parent
IMO the issue with LLMs is they massively widen the "unknown unknowns" (skipping review makes this problem even worse). This is obviously much worse when an LLM is actually a part of the software rather than just producing software that is otherwise deterministic.
lionkor 3 days ago | parent
swat535 3 days ago | parent
The thread is about jankiness, lack of feature cohesion and code quality.
What we are discussing here is: is it acceptable to accept poor code quality and trade it off with delivery?
skydhash 2 days ago | parent
I found that people that lean towards the latter also favor profits over customer satisfaction. Then they will try to defend themselves with a black and white view “it’s either this scrap or no delivery”.
no-name-here 2 days ago | parent
1. Have you seen that? If so, which agent+model?
2. Is “per day” intentionally used instead of per implementation - i.e a coding agent may A) be far faster tok/s than a human, and B) work more hours per day, so it’s similar bug rate per implementation? Or did you mean bugs per implementation?
lionkor 2 days ago | parent
no-name-here 1 day ago | parent
1. Are you referring to LLMs handling 100x as many patches as a human can, or that LLM implementations are 100x as long as a human's implementation?
2. In my experience, LLM implementations are often 2-4x as long, largely because they have a lot more error handling than I would have chosen to implement. However, I don't find they have correspondingly X times as many mistakes.
3. Part of how agents seem to avoid many mistakes or even catch mistakes is by testing things. For example, it caught issues in Pester functions on certain Pester versions, or will even analyze binaries to verify the right config settings to use, etc.
4. If you are seeing 100x as many bugs, which agent+model?
joquarky 2 days ago | parent
It's ludicrous that we have executives at tech companies that think this is possible.
One S&P 500 company I worked for signed a big contract to deliver bugless software for an enterprise web portal for the state of Minnesota. I was on the team that had to make that magic happen. I had to leave the company not long after that due to nearly life-ending burnout.
So I would throw scorn at the ivory tower inhabitants here who should know better than to suggest that anything of substantial complexity can be bug free
queenkjuul 2 days ago | parent
queenkjuul 2 days ago | parent
I do think the world would be better if commercial software had to meet some professional standard of fitness, with meaningful repercussions if not. I also realize that ship apparently sailed before i was born, and I'm not paid to do serious engineering, I'm paid to ship features.
(Not even saying I'm qualified to do the former anyway, i just also think every time national air traffic is shut down or like in France the other day and hundreds of supermarkets lose all their frozen inventory, or i can't do my job because some service failed, or yes, claude code is slow and heavy age can't work right in every terminal, that maybe we shouldn't be writing the stuff that the whole world relies on to function every day with zero agreed upon professional standards)
Xenoamorphous 3 days ago | parent
You can only say that of either a very simple program or perhaps one with formal verification (which is overkill for 99.99% of software that gets written).
Look at the Linux kernel, arguably a well designed system (unless you ask Tanenbaum) with top notch developers, and still is full of bugs and security holes.
1dontknow_ 3 days ago | parent
But I also would like to point out that comparing the Linux Kernel quality and development to Claude Code is surely a joke. The former is an ocean of features, compatibility and history. The latter, in the end still one executable CLI tool calling endpoints.
They're not even comparable.
queenkjuul 2 days ago | parent
jagraff 3 days ago | parent
By the way, all hardware has bugs too; we just don't see them often because the programmers building the stacks that we run our code on work around them.
joquarky 2 days ago | parent
tremon 2 days ago | parent
vinyl7 2 days ago | parent
likium 2 days ago | parent
lionkor 2 days ago | parent
Nobody has to make the perfect program, but we can't chalk it up to "the world isn't perfect" when I click the windows start menu and it opens empty (an existing bug btw)
mattjoyce 2 days ago | parent
How many large github repos have no bugs, not many. How much succesful commercial software does not have a way to patch their code, not much.
Reporting bugs, patching systems, updating software is common to most software.
lionkor 2 days ago | parent
Yes, but this is a side-effect of trying to do good work and writing code that is understood and works.
When you ship sloppy, AI generated code, that no humans at the company have read and understood, you're missing the main part about engineering and are skipping straight to the life-support stage of the software, and you treat the (previously) side effect as your main job. Reporting bugs and shipping patches becomes your job, instead of engineering software, which happens to also come with that task.
mattjoyce 1 day ago | parent
I expect people who are skillful and enjoy writing good code, are among those who dislike code generated with AI tools, and perhaps feel they have had a role or pleasure denied to them.
Those who write shit code, now feel that can produce vastly better software in a fraction of the time, and feel a sense of accomplishment.
yonl 3 days ago | parent
dns_snek 3 days ago | parent
That's a thought-terminating cliche. When someone asks how can they can avoid generating a pile of slop (which will compound over time and get increasingly harder to deal with), they're not seeking "perfection", and framing it in those terms is dishonest.
Furthermore, can we step back for a second and remember that user and developer experience matters too?
Working with code like that sucks. Spending much of your day on polishing a turd that grows more unwieldy with every iteration is going to get old, fast. And I also think that's going to take a significant mental health toll on people eventually.
The business won't care about this but we should. AI was supposed to make things better, better quality, better reviews, better QA, better product, better UX - remember?
> janky UX that can probably be fixed by prompting the next generation model to clean it up
I'll counter by pointing out that "Next one will fix everything" has been a meme for at least 2 years now and the slop just keeps getting sloppier.
thuuuomas 2 days ago | parent
Monkey's paw curls
evolveyourmind 3 days ago | parent
Current agents never take a step back to refactor and to create a good abstraction as the requirements evolve, they only care for delivering fast even at the price of garbage code which doesn’t scale
disgruntledphd2 3 days ago | parent
Certainly, it would be super super difficult to generate training data for it, so it's unlikely that it will improve.
isomorphic_duck 3 days ago | parent
latentsea 3 days ago | parent
disgruntledphd2 3 days ago | parent
Because of the scale that would be needed. Like, design stuff is much fluffier than code correctness or functionality, so really really hard to generate enough synthetic data to tune the models to do better.
In the limit yeah it would work, but in the limit we're all dead ;)
latentsea 3 days ago | parent
joquarky 2 days ago | parent
I e., a responsible developer who cares about quality will have to get their hands a little dirty with some maintenance now and then.
menaerus 3 days ago | parent
renegade-otter 3 days ago | parent
menaerus 3 days ago | parent
1dontknow_ 3 days ago | parent
By "Real" in this context I mean companies that aren't Anthropic .i.e. don't sell any kinda AI product and existed at least 10 years before the AI boom. Esp. in regulated or at least sensitive fields like finance, banking, medical, logistics etc.
menaerus 3 days ago | parent
mirekrusin 3 days ago | parent
upcoming-sesame 3 days ago | parent
futhey 3 days ago | parent
girvo 3 days ago | parent
mitemte 3 days ago | parent
They aren’t. Their source leak showed what a mess of a codebase they’re working with. That was, I assume built with unlimited access to frontier models as well.
grey-area 3 days ago | parent
foo42 3 days ago | parent
For now at least, I'd say churning code faster and faster cannot widen either of these bottlenecks much.
Today, I use Claude heavily, but review all the code. I'm faster, but not by the multiples people speak of. And that seems ok to me.
Marazan 3 days ago | parent
The secret is their code is shockingly bad but they have unlimited budget to fix it.
biggestriverman 3 days ago | parent
lukaslalinsky 3 days ago | parent
afro88 3 days ago | parent
latentsea 3 days ago | parent
patanegra 3 days ago | parent
And yes, they likely accept that not every line of code is clean.
But honestly (and unfortunately), average source code is nothing stellar either. I do SW dev for 30 years. And most projects I have seen were somewhat ugly.
jwr 3 days ago | parent
I'm very curious about that because that has not been my experience at all. I used to find janky crap from older models and I had to review every line of code very carefully. With newer models, and especially large ones like Fable, it just doesn't happen anymore. The code that I get is what I would have written. Actually, it's usually better because it covers more edge cases that I wouldn't have thought about.
At this point, I guide Claude Code, provide general direction, and make design decisions, but I rarely write code anymore. The code that I get from the LLM is just better.
I do not fully understand where the disconnect comes from. I do believe people that say that they get crap from LLMs, and I suspect I can guess some of the reasons for that, but I cannot be sure.
chrisjj 3 days ago | parent
> I rarely write code anymore. The code that I get from the LLM is just better.
Coding chatbots excel at leaping low bars.
jwr 3 days ago | parent
frumiousirc 3 days ago | parent
Same here. There is an introspective comment below by khazhoux asking the question from the opposite experience. Why do developers end up on different sides of this coin?
LLM capability is obviously important variable. But those with bad experiences report using top tier models, so that isn't it. Likewise, level of experience can be ruled out. Each side of the coin have experienced developers reporting.
A lot of the other variables are not reported but I can go from my own experience.
Greenfield vs brownfield? The first is indeed usually easier but I get great results updating large code bases with decades of development. And I suspect developing greenfield with LLM is easier as the code is better written from the start.
Rarity of the subject matter? In principle, yet another XYZ app or web page is well represented in the training data so the LLM should have an easy go at making similar. In the past with low-end LLMs, this was noticeable. Working in relatively obscure programming languages produced just garbage. But, that was prior to the inflection point. And today I get good results working on relatively arcane scientific/mathematical algorithm as I do when I ask the LLM to barf out some web app.
Different levels of testing and validation and expectation? Even best LLMs make mistakes. The better LLMs make fewer and expose fewer still to the human as they create internal tests. Maybe people have different expectations and those with bad experience expect perfection from a single prompt? Perhaps, but any experienced developer knows bugs are a part of software development.
What else?
Whatever the answer, it's not a simple one and it may be a confluence of many smaller things. Maybe different developers have a multi-variant function in their brain that pops out a different quality-of-software score and also a different threshold that divides good from bad and all we see in their reports is that binary conclusion.
raxxorraxor 3 days ago | parent
I think it is mostly this and my experience is that agents feel much more at home here. But on the other hand monorepos disadvantages become even more pronounced with agent work. It will become an unmaintainable mess, even if your agent can iterate through it regularly.
I still think building a pipeline that allows for separation of concerns is a requirement for maintainability. Sure, Claude excels to build software if I just give him a server where he can run wild. Any new requirement is an extension of the old repo.
But at some point you just have a giant mess and I am not really convinced of this approach, even if it certainly fits agents.
eviks 3 days ago | parent
They're obviously just accepting, have you seen any of their results? No internal insights required for these observations. Check out their clauded home page - try to open the right hamburger menu and click on 'policy' - it's impossible to do from the top because "Research" will expand on hover and push 'policy' down, and when you move further down, 'research' will collapse and 'policy' will jump up.
Likewise, the AI apps are infamous for their poor performance and buggy nature. Correctness is the price of such velocity
pas 3 days ago | parent
on mobile it works (where I would expect the hamburger menu), and on usual desktop I have the usual menu bar, but when I change the window size on desktop I get the hamburger menu (and then the UX jankiness is evident, but for me easy to work around, as moving the mouse down closes the "research" block and then it's quite simple to move it up to be able to click "policy")
at this point I think Opus does something better by default
eviks 3 days ago | parent
By the way, the hamburger shouldn't even be there as there is enough space to fit the full menu (and even the company name) at the viewport sizes I've checked
pas 3 days ago | parent
505050 2 days ago | parent
j45 3 days ago | parent
khalic 3 days ago | parent
epolanski 3 days ago | parent
My understanding is that they have manual reviewers in phase 1 of their projects. Their goal is to refine the automation of reviewing, writing skills/rules, etc, enforcing architectural choices, etc.
Then in phase 2, the review phase is AI-driven itself and humans only get to be decision makers of escalated issues.
animal531 3 days ago | parent
For example I've made a first screen with a lot of elements, and now I want to create a 2nd similar screen, so I tell it to use the same code as we've created for the first to make the 2nd. With that as input it will create it and a) use e.g. the variables and setup from the first b) copy everything into the 2nd c) copy some things d) make a generic parent for both to inherit from
A human would have realized that this is something we're going to be doing a lot, so the last is the correct answer. Make generics for all elements, e.g. the screen's panel, effects, buttons, text etc. then implement those along with possible overrides etc. for all.
But it seems that it has no clear methodology. Depending on your exact wording along with today's weather you will get any combination of the options.
chrisjj 3 days ago | parent
As expected. That woukd require domain understanding, and that's way beyond the scope of stochatic parrotry.
chrisjj 3 days ago | parent
Not. The web UI is the jankiest web UI that I've ever seen. E.g. its mobile responsiveness frequently crops dialogs leaving the close box unreachable.
floriferous 3 days ago | parent
Just do this for every type of "janky crap" and your codebase converges to perfection.
It's not that hard, but it takes a lot of tokens, and setup.
bvrmn 3 days ago | parent
It's always total hallucinations. It could only see local minor issues.
It happily starts to introduce fake abstractions and other junior level "refactoring" making it even worse.
jckahn 3 days ago | parent
port3000 3 days ago | parent
kenjackson 3 days ago | parent
“Our team members still review every change request for the system, but they now examine the intent of the change as opposed to reading every line of code.“
charliebwrites 3 days ago | parent
duttish 3 days ago | parent
The difference between intent and implementation seems like a very common source of bugs?
If intent and implementation was the same thing programmers as a profession would have been left behind 20 years ago.
kenjackson 3 days ago | parent
bonplan23 3 days ago | parent
fg137 3 days ago | parent
So basically -- it's all crap.
agos 2 days ago | parent
gloosx 3 days ago | parent
tzone 3 days ago | parent
If you cranked up turns and only used fable level model for every interaction, you would get way way less jank. Plus when you have essentially unlimited tokens, you can always do extra AI review passes to reduce jank.
I think for us, outside of Anthropic, it is hard to imagine the scale of AI agents that they are running internally . We are talking about probably 10s of millions $ worth of spend monthly if not more.
agos 2 days ago | parent
bl4ckm0r3 3 days ago | parent
lrvick 2 days ago | parent
I mean given all the sandbox escapes, and the leaked Claude codebase, I would assume they stopped reading their own code a long time ago.
chewbacha 2 days ago | parent
That’s the neat part! They don’t!
psyclobe 2 days ago | parent
sdeframond 2 days ago | parent
Because you are using LLMs to write code that you would be writing by hand.
Use it to write thing you wouldn't have time to write by hand and that are not mission critical: custom linters, support tools and so on. You know, each time you think to yourself "hey, I would write something to automate this chore, if only I could set aside one or two days".
You can also use it to document silly things you wouldn't take time to but that provide context to agents. Ask it to do a performance audit and to give you a few SQL queries and bash commands to gather stats about prod and logs. Then commit this document.
Will you read it? No. But your agent will use it to write code that's fit.
Keep doing this and 1/ you will be more productive, 2/ your agent will progressively improve so that you will let it do more and more.
queenkjuul 2 days ago | parent
They are just shipping the jank. Claude couldn't make sense of its own built in tools for like, months, if it's even fixed
serverlessmania 2 days ago | parent
keyle 3 days ago | parent
It's a bit like a murderer walking into a bar, bragging about his kills, and then "hey check out my new truck nuts".
startakovsky1 3 days ago | parent
blurbleblurble 3 days ago | parent
pmeunier 2 days ago | parent
tired_and_awake 3 days ago | parent
idk1 3 days ago | parent
> Earlier in the year, we had largely handwritten the first version of the git-to-Scion ingestion pipeline as a prototype. We thought it was good—until we got our hands on an early internal snapshot of Claude Mythos Preview. We asked it to rewrite the whole thing, and with no further instructions, it produced a version that consumed 20x less memory and was 4x faster, while preserving all of the implicit invariants around ingestion ordering and data structures.
We still need the human creativity and spark in the loop to come up with these fresh, new, bold, creative ideas. I think if you let the current version of Claude run forever, it still wouldn't have the creative spark to create its own new source control system.
This is the future of a human software engineer's job.
hollowturtle 3 days ago | parent
disgruntledphd2 3 days ago | parent
While I think their models are great, and they deserve a lot of props for caring about safety (their interpretability work is great), their public tone just leaves so much to be desired.
Apparently they also don't understand the Streissand effect, given their recent blog posts about GLM 5.3.
hollowturtle 3 days ago | parent
At this point I believe they NEVER cared about safety. The CEO doomerism and the whole "slow down the development of AI" far cry is another marketing strategy based off fear
gloosx 3 days ago | parent
Typical anthropic post.
ctolsen 3 days ago | parent
arcanemachiner 3 days ago | parent
khazhoux 3 days ago | parent
Meanwhile I’m here burning company tokens on top-tier models, and I still have to course-correct or problem-solve with my agents every 10 minutes…
English language needs a word to say “I don’t think you’re lying, but I also don’t believe you.”
rad-b 3 days ago | parent
viklove 2 days ago | parent
It's easy for them to one-shot solutions because the problems are very well defined, and the agents can easily reason about how the software will be used. The closer you get to the "real world," and the more complex the business logic gets, the worse the models get at making the right architectural or design decisions. If you're not watching closely to give input and steer the agent, it gets out of control pretty quick.
I find it ironic that these same individuals often loudly and publicly celebrate each new model release (as if they're early investors instead of early adopters), and tend to be very optimistic about agentic coding -- even though their jobs are the most at risk of being automated due to the simplicity of their work.
The closer you are to actual business outcomes and real-world software projects, the more you tend to understand that agentic coding patterns struggle to navigate the messiness of the real world. If you're working as a software engineer in an actual major industry (healthcare, insurance, defense, infrastructure, etc), you're probably going to be more skeptical when a gung-ho SDET makes bold claims about how LLMs are going to take everyone's job within the next 3-4 years.
> “I don’t think you’re lying, but I also don’t believe you.”
They're not lying. They're just a bit naive.
whazor 3 days ago | parent
1. Fable as software designer and me as reviewer
2. Me as software designer
3. Me as software designer and Fable as reviewer
Then in my opinion, best design comes from 3, then 2, then 1.
schleck8 3 days ago | parent
whazor 3 days ago | parent
menaerus 3 days ago | parent
> We asked it to rewrite the whole thing, and with no further instructions
They simply asked the model to rewrite the code without suggesting anything to the model which counters your creativity argument, which I see many people make too, but which I believe is not correct anymore. Models IME already are creative in ways I personally find it difficult to compete with. I still occasionally find something that the model in the first iteration would not to but the model is already far superior with its capabilities than I am.
koalalimpo 3 days ago | parent
menaerus 3 days ago | parent
girvo 3 days ago | parent
gmueckl 3 days ago | parent
menaerus 3 days ago | parent
In case of your comment, I could have agreed to some degree but what you say is also not necessarily true since we don't actually know if the new source control is the result of human creative input or if it was also suggested by the model. Having worked with these models extensively I am inclined to believe that both can be true.
gmueckl 3 days ago | parent
jqdsouza 3 days ago | parent
liyu1981au 3 days ago | parent
physTheta 3 days ago | parent
whiplash451 3 days ago | parent
Truly impressive, given the scale of Anthropic. Speaks a lot about the level of talent there, but also how far/fast we're moving into a new world.
> Practically speaking, it’s difficult to offer Scion in a form that would be broadly useful to other organizations.
Alas... open-sourcing scion would have been the true generous move.
root3 3 days ago | parent
smarkov 3 days ago | parent
> The history of our main branch alone is almost 100 GB
What value do you get from carrying around all of that history? Your code is changing so rapidly that it looks absolutely nothing like it did a year ago, so at what point are you going to want to see what it looked like back then and every single change that happened to it since? Wouldn't you benefit more from creating a tool that can semantically truncate history entries that are no longer relevant, since even with scn your history will continue to grow out of control?
gmueckl 3 days ago | parent
__MatrixMan__ 3 days ago | parent
If you're Anthropic, you probably don't want a 100Gb of haystack lying around in which a damning needle might be found.
Cthulhu_ 3 days ago | parent
Topfi 3 days ago | parent
mscrnt 3 days ago | parent
softwaredoug 3 days ago | parent
Cthulhu_ 3 days ago | parent
That said if you give it a problem and constraints / conditions / objectives I'm sure it's good enough now to come up with a solution.
amai 3 days ago | parent
„Scion is by no means a suitable replacement for git for general use. The concepts we’ve outlined here really only make sense for truly enormous monorepos, with either tens of thousands of engineers or swarms of agents prolifically writing code. Plus, Anthropic is unique in that our ability to spend tokens for internal use far exceeds what any other business would realistically want to spend. We do this both to address our own software development needs, and to test Claude’s capabilities.“
patwolf 3 days ago | parent
angry_octet 3 days ago | parent
All the evidence of AI hacking events points to the need for agent source control and collaboration in completely controlled environments, which precludes giving access to the one-repo-to-rule-them-all in an AI-coded VCS.
multisport 3 days ago | parent
It seems clear to me that they hope to some day own code storage (why wouldn't they) and this seems a pretty good first-principles attempt at it.
catlifeonmars 3 days ago | parent
LoganDark 2 days ago | parent
It could totally be helpful to both new startups as well as individual hobbyists working on greenfield projects. I find myself starting greenfield projects all the time these days, just because it's so easy and quick to try stuff out.
crakhamster01 2 days ago | parent
To that end though, this line feels like it (intentionally?) undersells the engineering team -
> Very often, we found that the role of the engineers was to tell Claude “no.”
To me, this blog post highlighted the immense value that domain-specific knowledge still carries in engineering. I wouldn't be surprised if their team was comprised of former Facebook/Google/Github source control engineers. Individuals with real experience on these types of systems.
The dream for a lot of folks in the industry right now is that you could just staff a bunch of generalists on a problem like this, and through the power of Claude come up with a sufficient solution. I think the reality is that without the domain expertise to direct Claude, you would end up with something vastly different, and not really usable at Anthropic's scale.
cush 2 days ago | parent
arendtio 2 days ago | parent
xtajv 2 days ago | parent
Wake me up when somebody tells them that they still have to pay for electricity.
lofaszvanitt 2 days ago | parent
zxspectrum1982 1 day ago | parent
Mistake #2: Anthropic essentially reinvented Subversion.